生成AI時代にもコンテンツ抽出が重要な理由Why content extraction still matters in the GenAI era
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
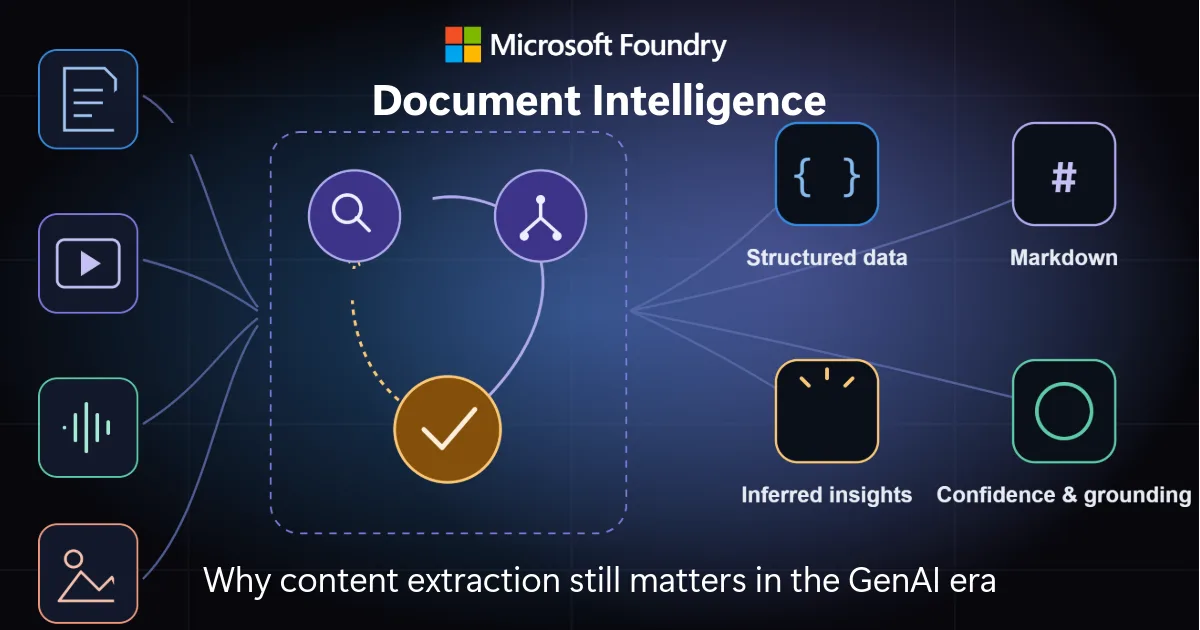
- コンテンツ抽出レイヤーは、PDF、画像、音声を検証可能で根拠の明確な情報へ整形し、生成AIエージェントが利用できるようにする。
- 企業データの乱雑さに対処し、信頼できる自動判断を支える。
A dedicated extraction layer converts PDFs, images, and audio into traceable, structured evidence for GenAI agents, enabling enterprises to automate decisions with confidence.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (devblogs.microsoft.com) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (devblogs.microsoft.com).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
コンテンツ抽出
生成AI時代の企業AIでは、選択するモデルだけでなく、エージェントが行動の根拠とするコンテンツを信頼できるかどうかが重要になる。専用のコンテンツ抽出レイヤーは、生成AIエージェントによる判断を支えるための基盤として位置付けられている。
PDF・画像・音声
実際のエンジニアリングの多くは、生のPDFや画像、音声ファイルを、エージェントが利用できる情報へ変換する部分にある。単にファイルを読める状態にするのではなく、内容を根拠が明確で検証可能な形に整え、追跡可能かつ構造化された証拠として扱えるようにすることが抽出レイヤーの役割となる。
乱雑な企業データ
大規模言語モデルの能力が高まる一方で、扱うコンテンツはより乱雑になっていると説明されている。モデルがコンテンツを読み、推論できるとしても、それだけで専用の抽出処理が不要になるわけではない。元の資料に曖昧さや制約が残ったままなら、エージェントによる個々の判断も、その影響を引き継ぐことになる。
信頼できる自動判断
企業が生成AIエージェントに依存するほど、入力となる情報には根拠の明確さと監査可能性が求められる。抽出レイヤーは、形式の異なる企業データを、エージェントが行動に利用できる検証可能な情報へ整形する。これにより、企業は判断の根拠を確認できる状態を保ちながら、自動化された意思決定を進められるとされる。
Enterprise AI
The future of enterprise AI depends less on the model chosen than on whether agents can trust the content they use. This matters because every automated decision can inherit the limitations and ambiguities present in its source material.
Five years into the era of large language models, models have become stronger while enterprise content remains messy. As a result, much of the engineering work lies in preparing that content so agents can act on information that is grounded and verifiable.
Dedicated extraction layer
A dedicated extraction layer converts raw PDFs, images, and audio files into information suitable for generative AI agents. Its role remains important even when models can already read and reason over content.
The ability to process a file does not by itself ensure that the resulting information is traceable, structured, or reliable enough for automated action. Content extraction addresses this gap by shaping source material into evidence that agents can use.
Grounded, verifiable information
The extraction process is intended to preserve a clear connection between an agent’s usable information and the content from which it came. This gives enterprises structured evidence rather than leaving agents to act directly on raw, ambiguous material.
Grounding and verifiability are therefore central requirements. The more enterprises depend on agents, the more important it becomes for the information behind their decisions to be clear and open to verification.
Auditable agent decisions
Reliable automation requires more than increasingly capable models. It also requires content that supports confidence in the decisions agents make.
By turning messy enterprise data into traceable evidence, the extraction layer supports decisions that can be examined and audited. Without that preparation, agents remain exposed to uncertainty embedded in PDFs, images, audio, and other source material, regardless of the model’s strength.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPoko大規模言語モデルの時代が始まって5年たっても、コンテンツ抽出が必要なんだ。これって大きいこと?Five years into the large language model era, content extraction is still needed. Is that a big deal?
- TECHガイドTECH Guideこの記事では、モデルは強くなった一方、企業のコンテンツはより乱雑になったとしています。判断の土台を整える重要性はむしろ増しています。The models have grown stronger, but enterprise content has become messier. The article argues that preparing trustworthy inputs matters more, not less.
- ポコPoko専用の「抽出レイヤー」って、何をするところ?What does a dedicated “extraction layer” actually do?
- TECHガイドTECH GuidePDFや画像、音声を、出どころを追えて確かめられる形に整え、生成AIエージェントへ渡す役目です。It turns PDFs, images, and audio into structured evidence that can be traced and checked, then passes it to GenAI agents.
- ポコPoko自分なら、ばらばらの資料を先に整えて、AIに判断を手伝ってもらいたいな。そういう使い方?I’d organize scattered files first, then ask AI to help with decisions. Is that the idea?
- TECHガイドTECH Guide記事の範囲では、その使い方に近いです。ただし、元の資料に曖昧さが残れば、エージェントの判断もその影響を受けます。That’s close to the use described here. But if the source material remains ambiguous, the agent’s decisions inherit those limitations too.