Home›Categories›Papers / Benchmarks

Category detail

Research21 total

Research カテゴリの更新を、新着順・30日トレンド・関連記事として確認できます。Browse Research updates by recency, 30-day trend, and related topics.

Total21現在掲載中の記事Articles currently listed
Last 7d2直近7日の掲載数Entries in the latest 7 days
Vs prev 7d0%その前の7日間と比較Compared with the prior 7 days
Avg/day0.3直近7日 ÷ 7Latest 7 days divided by 7

Research navigation

Research は選定した論文・レポートを含みますResearch includes selected papers and reports

このカテゴリでは選定した論文・レポートを扱い、専用の arXiv レーンでは論文だけをまとめて閲覧できます。

Browse selected papers and reports here, or use the dedicated arXiv lane for a papers-only view.

arXiv Papers
TrendLast 30 days
This week 2— 0%Last week 2Daily avg 0.3Peak 1
Sep 9Sep 16Sep 23Sep 30Oct 7Oct 8 ↑today
Papers/Benchmarks trend counts
DateCount
2026-09-090
2026-09-100
2026-09-110
2026-09-120
2026-09-130
2026-09-140
2026-09-150
2026-09-160
2026-09-170
2026-09-180
2026-09-190
2026-09-200
2026-09-210
2026-09-220
2026-09-230
2026-09-241
2026-09-250
2026-09-260
2026-09-270
2026-09-280
2026-09-291
2026-09-301
2026-10-010
2026-10-020
2026-10-030
2026-10-040
2026-10-050
2026-10-060
2026-10-071
2026-10-081
現在の Research 一覧(arXiv 専用レーンを除く)の掲載数。直近 7 日間を濃く、それ以前を薄く表示Based on the current Research listing (excluding the dedicated arXiv lane); the last 7 days are shown in full colour and earlier days are muted.

All articles21 total

新着順Newest first
今日TODAY1 entries
🔥 HOT公式OfficialPapers/Benchmarks·Microsoft Research Blog

Agent Lightning v1.0:実運用ハーネスでエージェントを訓練する3,500行の軽量エージェント強化学習フレームワークAgent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses

重要度 HighHigh priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約Agent Lightning v1.0は約3,500行で、実運用のエージェントハーネスを強化学習へ直接接続する制御基盤を提供する。Kubernetes上で商用サンドボックスに頼らず学習でき、開発者の再実装負担を減らす。

AI SUMMARYAgent Lightning v1.0 provides a roughly 3,500-line control plane that trains agents through deployment harnesses, reducing reimplementation for agent developers.

Agent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses
昨日YESTERDAY1 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

AIが誤ること、そして失敗が教えることWhat AI gets wrong and what failure teaches us

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約Microsoft Researchの対談は、標準的なベンチマークを超えてAIを評価し、予想外の失敗から性能の限界を探る。利用者の要望に合う、より信頼できるシステムを築きたい開発者に役立つ。

AI SUMMARYMicrosoft Research examines AI beyond standard benchmarks and learns from unexpected model failures, helping practitioners build systems that better serve users.

What AI gets wrong and what failure teaches us
9/30(水)Wed, Sep 301 entries
公式OfficialPapers/Benchmarks·Hugging Face Blog

Open TTS Leaderboard:多言語音声合成と音声クローニングの大規模評価Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約Open TTS Leaderboardは、8,000超の公開TTSモデルが存在する中、多言語音声合成と音声クローニングを大規模に比較する評価基盤を提示する。分断された評価を揃え、開発者や利用者のモデル選定を助ける。

AI SUMMARYOpen TTS Leaderboard provides scalable comparisons for multilingual speech synthesis and voice cloning amid 8,000-plus Hub models, helping developers and users choose consistently.

Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning
9/29(火)Tue, Sep 291 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

生物学の複雑性に対応するAI研究システム「Quine」の紹介Introducing Quine: An AI research system designed for the complexity of biology

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

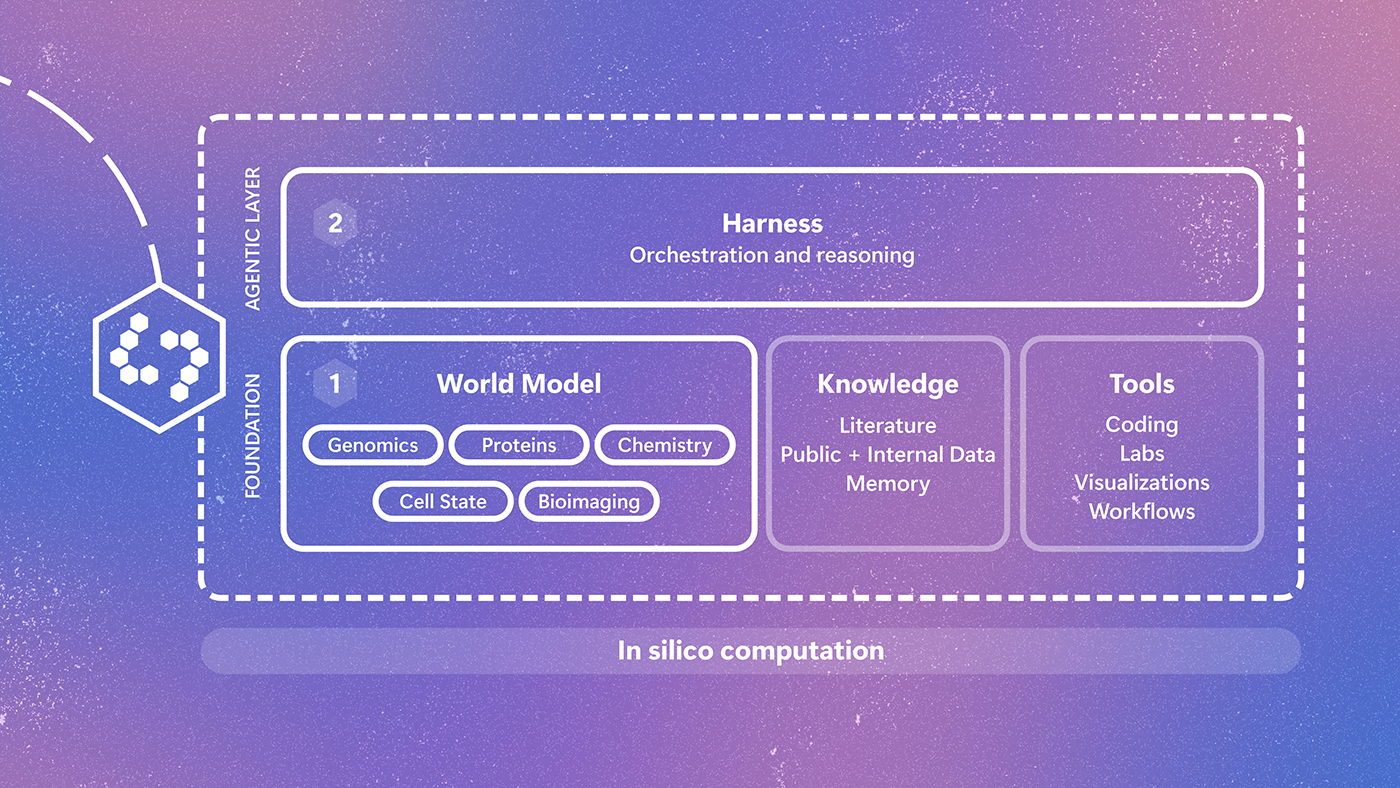
AI要約Quineは、生物学の複数のスケールとデータ形式を結び付ける初期段階のマルチモーダル世界モデルです。広範な候補を計算で絞り、科学者が実験前に有望な仮説を優先できるようにします。

AI SUMMARYQuine combines diverse biological data across scales in an early-stage multimodal world model. It helps scientists rank hypotheses computationally before lab work.

Introducing Quine: An AI research system designed for the complexity of biology
9/24(木)Thu, Sep 241 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

実環境の物理AIロボティクスに向けた推論オフロードOffloaded inference for real-world physical AI robotics

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約物理AIロボットの推論をエッジやクラウドのGPUへ移す手法は、移動マニピュレーションで成功率を高め、大規模モデルの利用と稼働時間の延長を実現し、実環境で動くロボットの応答性と拡張性を向上させる。

AI SUMMARYRemote GPU inference for physical AI robots raised success on mobile-manipulation tasks, supported bigger models, and extended runtime for real-world deployments.

Offloaded inference for real-world physical AI robotics
9/1(火)Tue, Sep 11 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

GigaPath-FlashとGigaTIME-Flash:効率的な病理基盤モデルで大規模集団からの発見へGigaPath-Flash and GigaTIME-Flash: Toward population-scale discovery with efficient pathology foundation models

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約GigaPath-FlashとGigaTIME-Flashは、病理基盤モデルの高い性能を維持しつつ計算負荷を削減する。より大規模な集団研究と幅広い探索を可能にし、研究者の発見を後押しする。

AI SUMMARYGigaPath-Flash and GigaTIME-Flash lower compute requirements for AI pathology analysis without sacrificing strong results, enabling broader studies at population scale.

GigaPath-Flash and GigaTIME-Flash: Toward population-scale discovery with efficient pathology foundation models
8/13(木)Thu, Aug 131 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

MindTopoがVLMの空間推論能力を明らかにMindTopo reveals VLMs’ spatial reasoning abilities

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約Microsoftが提案するベンチマーク「MindTopo」は、AIがトポロジー的な空間関係をどれだけ理解できるかを評価する新基準であり、VLMの空間推論・計画能力の弱点と改善機会を浮き彫りにする。

AI SUMMARYMindTopo is a new benchmark from Microsoft Research that evaluates how well vision-language models grasp topological spatial relationships, exposing current limitations and pointing toward improvements in AI spatial reasoning and planning.

MindTopo reveals VLMs’ spatial reasoning abilities
8/4(火)Tue, Aug 41 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

Orchard: スケーラブルなエージェントAIのためのオープンフレームワークOrchard: An open framework for scalable agentic AI

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約MicrosoftリサーチがオープンソースフレームワークOrchardを公開し、AIエージェントの学習・評価インフラを共通化することで小規模モデルでも高い性能を引き出せるようにした。研究者がタスク横断的にインフラを再利用できる点が特徴。

AI SUMMARYMicrosoft Research released Orchard, an open-source framework that unifies infrastructure for training and evaluating AI agents across diverse task types, allowing smaller models to achieve strong performance. It lowers barriers for researchers building scalable agentic systems.

Orchard: An open framework for scalable agentic AI
7/31(金)Fri, Jul 311 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

Echoverse: コンピューター操作エージェント向けの深化・進化する環境Echoverse: Deep, evolving environments for computer-use agents

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約MicrosoftリサーチはEchoverseを発表し、コンピューター操作AIエージェントが学習・評価できる動的で深みのある環境を提供する。エージェント開発の現実的なベンチマーク構築に貢献する研究成果として注目される。

AI SUMMARYMicrosoft Research introduced Echoverse, a framework providing deep and evolving environments for training and evaluating computer-use AI agents. It aims to enable more realistic benchmarking and development of agents that interact with software interfaces.

Echoverse: Deep, evolving environments for computer-use agents
7/10(金)Fri, Jul 101 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

Aurora 1.5: 天気・地球システム向けオープン基盤モデルの拡張Aurora 1.5: Extending open foundation models for weather and Earth-system applications

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約Aurora 1.5は22変数の追加、時間単位の時間分解能、確率的アンサンブル予測を新たに備え、気象・気候・エネルギー分野での実用性を大幅に向上させた。

AI SUMMARYAurora 1.5 expands the weather foundation model with 22 additional variables, hourly resolution, and probabilistic ensemble forecasting, making it more actionable for climate, energy, and real-world forecasting use cases.

7/9(木)Thu, Jul 91 entries
公式OfficialPapers/Benchmarks·Microsoft Research Blog

Flint: AIの時代のための可視化言語Flint: A visualization language for the AI era

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約MicrosoftリサーチはオープンソースのチャートDSL「Flint」を公開。コンパクトな仕様からAIエージェントが表現豊かなグラフを生成でき、人間も読み書きしやすい中間的なアプローチを実現する。

AI SUMMARYMicrosoft Research released Flint, an open-source visualization DSL that enables AI agents to generate expressive charts from concise, human-readable specs, bridging the gap between minimal chart definitions and polished output.

7/1(水)Wed, Jul 12 entries
公式OfficialPapers/Benchmarks·Hugging Face Blog

ScarfBench: エンタープライズJavaフレームワーク移行のためのAIエージェントベンチマークScarfBench: Benchmarking AI Agents for Enterprise Java Framework Migration

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約IBM ResearchがScarfBenchを公開。AIエージェントがエンタープライズJavaのフレームワーク移行タスクをどれだけ自律的にこなせるかを評価するベンチマークで、実務での活用可能性を測る基準を提供する。

AI SUMMARYIBM Research introduced ScarfBench, a benchmark designed to evaluate AI agents on real-world enterprise Java framework migration tasks, providing a standardized way to measure how effectively models handle complex legacy modernization work.

公式OfficialPapers/Benchmarks·Microsoft Research Blog

SkillOpt: 訓練可能なパラメータとしてのエージェントスキルSkillOpt: Agent skills as trainable parameters

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約SkillOptはAIエージェントの指示(スキル)をモデルの重みを変えずに自動最適化する手法で、手動編集に頼らず体系的にエージェント挙動の信頼性を高める。

AI SUMMARYSkillOpt treats agent skill instructions as trainable parameters, automatically refining them through a principled optimization loop rather than ad-hoc manual edits, improving agent reliability without updating model weights.

6/19(金)Fri, Jun 191 entries
公式OfficialPapers/Benchmarks·Hugging Face Blog

MosaicLeaks: リサーチエージェントは機密を守れるか?MosaicLeaks: Can your research agent keep a secret?

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約AIリサーチエージェントが機密情報をモザイク的に漏洩させるリスク「MosaicLeaks」を検証した研究で、ローカルLLMを用いたエージェント設計における情報セキュリティの重要性を示している。

AI SUMMARYThis research introduces MosaicLeaks, a study examining how AI research agents can inadvertently leak sensitive information through aggregated outputs, highlighting critical security considerations for agent design using open models.

6/18(木)Thu, Jun 182 entries
公式OfficialPapers/Benchmarks·Hugging Face Blog

LoRAを超えて:最も人気のあるファインチューニング手法に勝てるか?Beyond LoRA: Can you beat the most popular fine-tuning technique?

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約HuggingFaceがLoRAと競合する各種PEFTアルゴリズムを比較検証し、タスクや制約に応じた最適な手法の選び方を解説している。LoRA一択ではなく用途次第でより優れた選択肢が存在することを示す点で重要。

AI SUMMARYHugging Face explores PEFT methods that rival or surpass LoRA, benchmarking alternatives across tasks to help practitioners choose the best fine-tuning approach for their specific constraints.

公式OfficialPapers/Benchmarks·Hugging Face Blog

エージェント能力は十分か?独自ツールでオープンモデルをベンチマークするIs it agentic enough? Benchmarking open models on your own tooling

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約オープンLLMのエージェント性能を自社ツール環境で評価するベンチマーク手法を解説し、モデル選定の実践的指針を提供する。

AI SUMMARYThis article presents a practical framework for benchmarking open LLMs on agentic tasks using custom tooling, helping developers choose the right model for real-world agent workflows.

6/2(火)Tue, Jun 21 entries
公式OfficialPapers/Benchmarks·DORA Insights (Google)

「tokenmaxxing」時代におけるバランスの取り方——DORAが警鐘を鳴らすFinding balance in the era of tokenmaxxing

重要度 InfoInformational深掘り候補 · 技術記事 · Papers / BenchmarksDeep-dive candidate · technical post · Papers / Benchmarks

AI要約AIトークン消費量を社内リーダーボードで競わせる「tokenmaxxing」がAI導入促進策として広がるなか、DORAの調査はこの数値偏重がグッドハートの法則に陥り生産性指標を歪めると警告し、質と量のバランスの重要性を訴えている。

AI SUMMARYDORA warns that "tokenmaxxing"—rewarding raw AI token consumption via internal leaderboards to spur adoption—can become a vanity metric that distorts real productivity, urging teams to balance quantity with quality.

3/10(火)Tue, Mar 101 entries
公式OfficialPapers/Benchmarks·DORA Insights (Google)

DORA調査:AI導入から効果的なSDLC活用へ、緊張関係をどう調整するかBalancing AI tensions: Moving from AI adoption to effective SDLC use

重要度 InfoInformational深掘り候補 · 技術記事 · Papers / BenchmarksDeep-dive candidate · technical post · Papers / Benchmarks

AI要約DORAは、AIがコード生成を加速し初期摩擦を減らす一方で、検証負担やスキル低下、統合の難しさという隠れたコストを生むと指摘。単なる導入から効果的活用へ移るには、生産性と品質、信頼と検証のバランスが鍵だと論じる。

AI SUMMARYDORA argues that while AI speeds initial code generation, it adds hidden taxes like verification overhead, skill degradation, and integration challenges, so leaders must balance productivity with quality to shift from adoption to effective SDLC use.

2/17(火)Tue, Feb 171 entries
公式OfficialPapers/Benchmarks·DORA Insights (Google)

DORA調査:AI依存をどう管理するかManaging AI dependency

重要度 InfoInformational深掘り候補 · 技術記事 · Papers / BenchmarksDeep-dive candidate · technical post · Papers / Benchmarks

AI要約DORAがUCバークレー校の学生と行った調査をもとに、AIツールへの過度な依存リスクを指摘し、ガードレール設定やスキル維持、批判的検証を通じて生産性と長期的な専門性を両立する方法を解説する。

AI SUMMARYDORA's research with UC Berkeley students examines the risk of over-relying on AI coding tools and shows how developers set guardrails, retain skills, and apply critical verification to balance productivity with lasting expertise.

1/7(水)Wed, Jan 71 entries
公式OfficialPapers/Benchmarks·DORA Insights (Google)

DORA 2025年の振り返り:AI時代の開発生産性研究の進展DORA 2025: Year in review

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約DORAは2025年、「State of AI-assisted Software Development Report」とDORA AI Capabilities Modelを公開した。AI支援開発の実態と成熟化の指針を整理し、生産性向上を目指す開発組織に役立つ。

AI SUMMARYDORA released the State of AI-assisted Software Development Report and DORA AI Capabilities Model in 2025, giving teams evidence and guidance to mature AI adoption.

1/2(金)Fri, Jan 21 entries
公式OfficialPapers/Benchmarks·DORA Insights (Google)

DORAソフトウェアデリバリ指標の歴史と進化A history of DORA’s software delivery metrics

重要度 MediumMedium priority技術記事 · Papers / Benchmarkstechnical post · Papers / Benchmarks

AI要約DORAのソフトウェアデリバリ指標は、従来の4指標から信頼性を含む現在の5指標モデルへ発展した。10年以上にわたる研究と改訂の経緯を整理し、DevOpsチームが指標の背景を踏まえて性能を評価する助けとなる。

AI SUMMARYDORA's software delivery framework moves from four key metrics to a five-metric model including reliability, helping DevOps teams assess performance more clearly.