Home›Tags›#llm

Tag timeline

#llm273 total

同じキーワードで束ねられた更新を確認できます。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total273#llm の全掲載記事All listed entries tagged #llm
Showing30このページの件数Entries on this page
Page1/10静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 1/10 · 273 total

昨日YESTERDAY3 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

原題 ENEnglish titlellm-mistral 0.16llm-mistral 0.16

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約llm-mistral 0.16は、新たにMistral Large 4などの推論モデルへ対応した。同ツール経由で高度な推論機能を使いたいLLMユーザーにとって、選択できるモデルの幅が広がる更新だ。

AI SUMMARYllm-mistral 0.16 adds compatibility with reasoning models, including the recent Mistral Large 4, broadening model choice for LLM users seeking advanced reasoning.

🔥 HOTコミュニティCommunityLocal Models·Simon Willison's Weblog

Mistral Large 4「Le chonk」登場Introducing Mistral Large 4: Le chonk

重要度 HighHigh priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Mistral Large 4は、1兆パラメータ、稼働490億パラメータのAPIプレビューとして公開され、推論レベルは「none」と「high」の2段階。月末にはオープンウェイト版も予定され、開発者が大規模モデルを試す選択肢が広がる。

AI SUMMARYMistral Large 4 enters API preview with 1 trillion parameters, 49 billion active, and two reasoning levels. Open weights are due by month-end, widening developer access.

Introducing Mistral Large 4: Le chonk
🔥 HOTコミュニティCommunityLocal Models·Simon Willison's Weblog

原題 ENEnglish titleMistral Large 4Mistral Large 4

重要度 HighHigh priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Mistral Large 4のSVG生成力を、Claude Opus 5.5、GPT-6.1-sol、Gemini 3.8 Flashと同じ奇抜な火星の画像課題で比較し、飽和した評価指標では見えにくいモデル間の差を判断できる。

AI SUMMARYMistral Large 4 is tested against Claude Opus 5.5, GPT-6.1-sol, and Gemini 3.8 Flash on the same unusual SVG prompt, revealing differences that saturated benchmarks may miss.

10/5(月)Mon, Oct 51 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

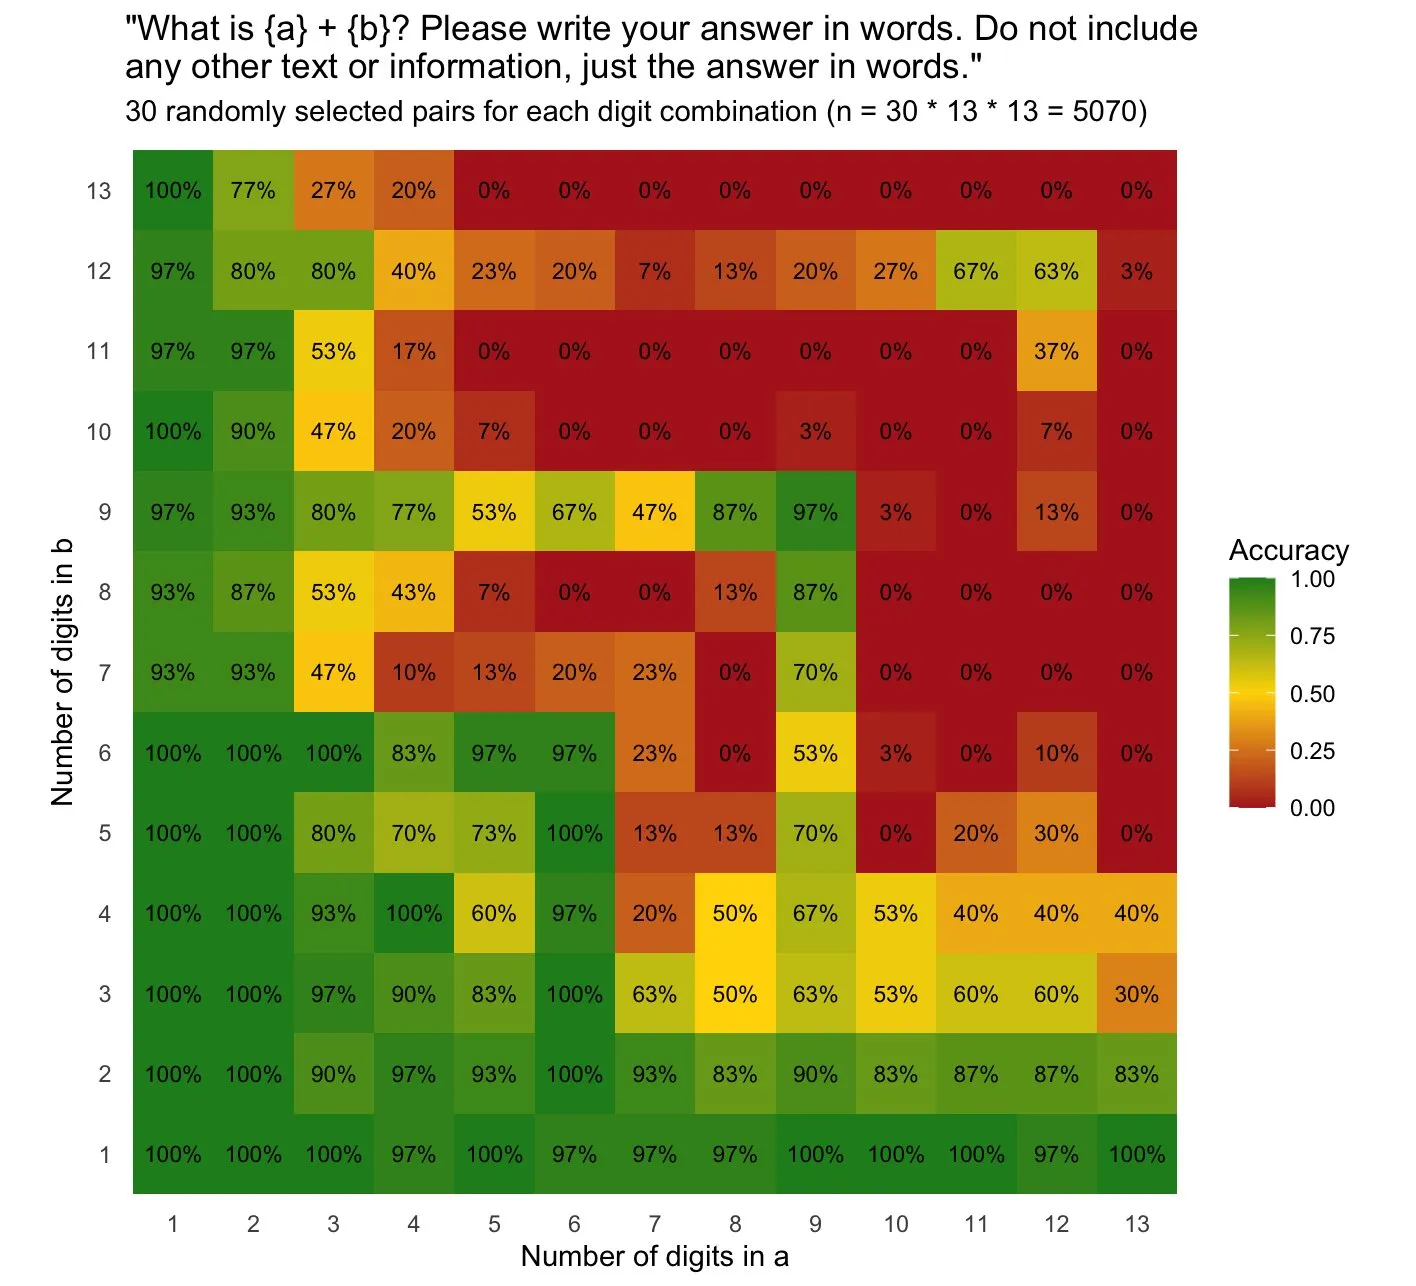
Qwen3.8 27Bによる足し算の文章回答Qwen3.8 27B addition in words

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Qwen3.8 27Bは、大きくなる数の足し算を行い、答えを数字ではなく言葉で返す試験をDGX Spark上で実施した。管理されたローカル環境でGPT-4oとの計算能力を比較できる。

AI SUMMARYQwen3.8 27B was tested on increasingly large additions while spelling out each result, using a Q4_K_M GGUF on DGX Spark. This enables a controlled local comparison with GPT-4o.

Qwen3.8 27B addition in words
10/4(日)Sun, Oct 41 entries
コミュニティCommunityCopilot·Qiita VSCode

VS Code GitHub Copilot Chatの裏側:ステートレスLLMを操るコンテキスト&エージェント・オーケストレーションの全貌Inside VS Code GitHub Copilot Chat: Context and Agent Orchestration for Stateless LLMs

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約VS Code GitHub Copilot Chatは、履歴、ツール、指示ファイルをクライアント側で再構成し、ステートレスなLLMに会話の連続性を持たせます。Agent modeとPrompt Cachingの設計上の得失を示し、拡張可能なAIエージェント開発に役立ちます。

AI SUMMARYVS Code GitHub Copilot Chat rebuilds history, tools, and instruction files client-side for each stateless LLM call. Agent mode and prompt caching trade-offs guide scalable agent design.

VS Code GitHub Copilot Chatの裏側:ステートレスLLMを操るコンテキスト&エージェント・オーケストレーションの全貌
9/25(金)Fri, Sep 252 entries
公式OfficialCopilot·GitHub Copilot Blog

チャットが不向きなUIであるときWhen chat is the wrong UI

重要度 InfoInformational深掘り候補 · 技術記事 · GitHub CopilotDeep-dive candidate · technical post · GitHub Copilot

AI要約LLMの主要な操作画面として、登場から3年を経てもチャットが使われ続ける前提に疑問を投げかける。対話欄に頼らず用途に合うUIを選ぶ視点を示し、AI体験を設計する開発者の判断に役立つ。

AI SUMMARYLLMs still default to chat as their main interface three years into the current AI wave, and the author challenges that assumption to help developers design interactions suited to each task.

When chat is the wrong UI
公式OfficialCopilot·GitHub Blog (AI & ML)

GitHub Security Lab Taskflow AgentによるAI活用ファジングAI-powered fuzzing with the GitHub Security Lab Taskflow Agent

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約GitHub Security Lab Taskflow Agentは、カバレッジ監視、未到達コード用ハーネスの作成、クラッシュの選別をLLMに担わせ、継続的な脆弱性探索に必要な人手の削減を目指します。

AI SUMMARYGitHub Security Lab Taskflow Agent uses an LLM for coverage monitoring, harness creation, and crash triage, reducing human effort in continuous vulnerability discovery.

AI-powered fuzzing with the GitHub Security Lab Taskflow Agent
9/24(木)Thu, Sep 241 entries
🔥 HOTコミュニティCommunityCopilot·Qiita GitHub Copilot

GPT-6 Luna は本当に安い? 2026 年 9 月の新モデルを GitHub Copilot の料金と用途で選ぶIs GPT-6 Luna Really Cheap? Choosing September 2026 Models by GitHub Copilot Pricing and Use Case

重要度 HighHigh priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約GPT-6 Luna は低コストと高速応答を強みに、確認しやすい作業の第一候補となる。複数資料の調査や修正には、Copilot Pro+ 以上または Business / Enterprise で利用できる GPT-6 Sol を挙げ、用途別のモデル選定を助ける。

AI SUMMARYGPT-6 Luna is the low-cost, fast choice for easy-to-check tasks; GPT-6 Sol covers cross-file research and fixes on Copilot Pro+, Business, or Enterprise, helping users choose.

GPT-6 Luna は本当に安い? 2026 年 9 月の新モデルを GitHub Copilot の料金と用途で選ぶ
9/18(金)Fri, Sep 181 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Bonsai 2 27B:約9分の1の容量でほぼ無損失の圧縮Bonsai 2 27B: Near-Lossless Compression in a 9x Smaller Footprint

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Bonsai 2 27Bは、品質低下を抑えつつ通常の約9分の1となる約5.95GBのGGUFで提供される。実行にはPrism版llama.cppが必要で、Apple silicon搭載Macでのローカル運用を可能にする。

AI SUMMARYBonsai 2 27B comes as a roughly 5.95 GB GGUF, about one-ninth the normal size with little quality loss. Prism's llama.cpp fork is needed, helping Mac users run it locally.

9/10(木)Thu, Sep 101 entries
公式OfficialOpenHands/OpenCode·OpenHands Releases

OpenHands、v1.17.0をリリースOpenHands Releases v1.17.0

重要度 MediumMedium priority公式リリース · OpenHands / OpenCodeofficial release · OpenHands / OpenCode

AI要約OpenHands v1.17.0は、ダッシュボードでマニフェスト宣言値を表示し、会話タグとフィルタリングも追加しました。クラウドのLLM接続や自動化設定を扱う利用者の可視性と運用性を高めます。

AI SUMMARYOpenHands v1.17.0 adds manifest-declared values to dashboard views and introduces conversation tags and filtering. Cloud LLM connections and improved automation controls help teams operate agents more effectively.

OpenHands Releases v1.17.0
8/30(日)Sun, Aug 301 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

「Hy4 Preview」の紹介Introducing Hy4 Preview

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Hy4 Previewは、総7700億・稼働490億パラメータと100万トークンのコンテキストを備えるTencentのテキスト専用オープンウェイトLLMです。推論設定を含むチャットテンプレートも公開され、長文処理やモデル能力の検証に役立ちます。

AI SUMMARYHy4 Preview is Tencent's text-only open-weight LLM with 770B total, 49B active parameters and a 1M-token context. Its chat template helps users assess reasoning and long-context behavior.

Introducing Hy4 Preview
8/28(金)Fri, Aug 282 entries
公式OfficialOpenHands/OpenCode·OpenHands Releases

OpenHands v1.16.0 リリースOpenHands Releases v1.16.0

重要度 MediumMedium priority公式リリース · OpenHands / OpenCodeofficial release · OpenHands / OpenCode

AI要約OpenHands v1.16.0では、対応LLMプロバイダーの選択UI、Linuxデスクトップ向けインストーラービルド、オートメーション実行のライブフェーズ表示などが追加された。開発者の環境構築と運用監視が改善される。

AI SUMMARYOpenHands v1.16.0 adds LLM provider selection in settings, a Linux desktop installer with deb packaging, and live phase visibility for automation runs, improving setup and operational monitoring for developers.

OpenHands Releases v1.16.0
公式OfficialGemini/Gemma·Google DeepMind Blog

Gemini Omni 1.1 Flash で開発者はより細かい制御が可能にGemini Omni 1.1 Flash lets you build with more control

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約Googleが Gemini Omni 1.1 Flash を公開し、開発者向けに出力や動作の制御性を強化した。AIアプリケーション構築の柔軟性を求める開発者に恩恵をもたらす。

AI SUMMARYGoogle released Gemini Omni 1.1 Flash with enhanced developer controls over model behavior and output, giving builders finer-grained tools for production AI applications.

Gemini Omni 1.1 Flash lets you build with more control
8/27(木)Thu, Aug 271 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Qwen3.8-Flash-Next:Qwen4アーキテクチャのプレビューとなるマルチモーダルMoEモデルQwen3.8-Flash-Next

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約QwenがQwen4の設計を先行公開するマルチモーダルMoEモデル「Qwen3.8-Flash-Next」をリリース。総パラメータ125Bながらアクティブは6Bのみで、高い推論効率を実現している。

AI SUMMARYQwen3.8-Flash-Next is a multimodal MoE model previewing the Qwen4 architecture, with 125B total parameters but only 6B active at inference time, delivering strong performance at low computational cost.

Qwen3.8-Flash-Next
8/26(水)Wed, Aug 261 entries
公式OfficialCopilot·GitHub Blog (AI & ML)

本番導入前にLLMを評価する方法How to evaluate LLMs before production

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約GitHubがシークレットスキャンへのLLM実用導入を通じて得た評価手法の知見を共有。本番前に品質・精度を検証するための実践的なアプローチを解説している。

AI SUMMARYGitHub shares practical lessons learned from evaluating LLMs for real-world secret scanning, offering guidance on how to rigorously assess model quality before deploying to production.

How to evaluate LLMs before production
8/24(月)Mon, Aug 242 entries
論文PaperPapers/Benchmarks·arXiv cs.LG

モデル以外は何も変わらない:CellFill — 量子化LLMへのビット同一・取り消し可能な更新のための境界付きセル内学習Nothing Changed but the Model: CellFill -- Bounded In-Cell Learning for Bit-Identical, Revocable Updates to Quantized LLMs

重要度 MediumMedium priority論文/研究 · Papers / Benchmarkspaper/research · Papers / Benchmarks

AI要約CellFillは量子化LLMの各重みセル内の空き空間を利用し、元のチェックポイントのビットを変えずに知識を追加・取り消しできる手法で、評価やキャッシュの再利用性を維持できる点が重要です。

AI SUMMARYCellFill stores incremental knowledge updates inside the unused capacity of quantized weight cells, enabling bit-identical, revocable edits to deployed LLMs without replacing the original checkpoint or invalidating existing evaluations.

Nothing Changed but the Model: CellFill -- Bounded In-Cell Learning for Bit-Identical, Revocable Updates to Quantized LLMs
コミュニティCommunityLocal Models·Qiita LLM

【ローカルLLM】国産LLM「LLM-jp-4-33B」と「Qwen3.8-27B」の推論性能比較(RTX 5070 Ti + RTX 3070 Ti)A hands-on benchmark comparing the newly released Japanese LLM "LLM-jp-4 33B"…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMCが公開した約332億パラメーターのDense型モデル「LLM-jp-4 33B」を、RTX 5070 TiとRTX 3070 Tiの2枚構成でローカル実行し、Qwen3.8-27Bとの推論性能を比較検証した記事。

AI SUMMARYA hands-on benchmark comparing the newly released Japanese LLM "LLM-jp-4 33B" (a 33B Dense model) against Qwen3.8-27B, run locally on a dual-GPU setup of RTX 5070 Ti and RTX 3070 Ti.

【ローカルLLM】国産LLM「LLM-jp-4-33B」と「Qwen3.8-27B」の推論性能比較(RTX 5070 Ti + RTX 3070 Ti)
8/23(日)Sun, Aug 234 entries
コミュニティCommunityLocal Models·Qiita LLM

富豪AI(加算思考)への疑問。日本のカーナビ・電子辞書の引き算思想でllama.cppの最深部をハックした話(RAM 6.5GB極貧環境)A developer hacked llama.cpp internals on a RAM-constrained 6.5 GB machine…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RAM 6.5GBという極限環境でllama.cppの内部を改造し、独自アルゴリズム「AMI」によりAttentionキャッシュを効率化することで、リソース加算に頼らず推論を成立させる手法を解説した技術記事。

AI SUMMARYA developer hacked llama.cpp internals on a RAM-constrained 6.5 GB machine using a subtraction-first design philosophy inspired by Japanese car-nav and electronic dictionaries, proposing the AMI (Attention Mesh Index Transmission) algorithm as a public-domain technique for efficient LLM inference.

富豪AI(加算思考)への疑問。日本のカーナビ・電子辞書の引き算思想でllama.cppの最深部をハックした話(RAM 6.5GB極貧環境)
コミュニティCommunityLocal Models·Qiita LLM

RAG構築の壁を越える!ローカル×クラウドのハイブリッド構成とコスト戦略This article addresses three common RAG implementation challenges—poor…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約実務でRAGシステムを構築する際に直面する検索精度の低さ・クラウドコストの増大・機密データの外部送信リスクという三つの課題を、ローカルLLMとクラウドを組み合わせたハイブリッド構成で解決するアプローチを解説した記事。

AI SUMMARYThis article addresses three common RAG implementation challenges—poor retrieval accuracy, high cloud costs, and confidential data exposure—by proposing a hybrid architecture that combines local LLMs with cloud services to balance performance, cost, and privacy.

RAG構築の壁を越える!ローカル×クラウドのハイブリッド構成とコスト戦略
コミュニティCommunityLocal Models·Qiita LLM

ローカルLLMにISMSの適合状況評価を支援させる ― 第4回 判定の仕組みThe fourth installment of a series on using a local LLM for ISMS conformity…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約業務PCのローカルLLMでISMS適合評価を行う連載第4回。LLMの判定根拠を可視化し、顧客報告書に耐えうる透明性を確保する仕組みを解説している。

AI SUMMARYThe fourth installment of a series on using a local LLM for ISMS conformity assessment explains how to surface the model's reasoning so that its verdicts against JIS Q 27001/27002 are auditable and suitable for client reports.

ローカルLLMにISMSの適合状況評価を支援させる ― 第4回 判定の仕組み
コミュニティCommunityLocal Models·Qiita LLM

深夜3時のKeyErrorを防ぐ!非同期Python×AST×ローカルLLM自己修復アーキテクチャThis article details a self-healing middleware architecture that combines…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約非同期Pythonアプリで発生するランタイムエラーをASTとローカルLLMを組み合わせた自己修復ミドルウェアで自動検知・修正するアーキテクチャを解説した記事。完全自動化の幻想を排し、実践的な「泥臭い」設計指針を示している。

AI SUMMARYThis article details a self-healing middleware architecture that combines Python AST analysis with a local LLM to automatically detect and patch runtime errors like KeyError in async Python applications, offering a pragmatic alternative to fully-automated coding fantasies.

深夜3時のKeyErrorを防ぐ!非同期Python×AST×ローカルLLM自己修復アーキテクチャ
8/22(土)Sat, Aug 223 entries
コミュニティCommunityLocal Models·Qiita LLM

AI企画会議で10チームの案を個人開発アプリの新機能にするまでThe author built a local tool called Concept Arena that assigns the same…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約動画管理アプリの新機能を検討するため、10種類の異なる視点を持つAIチームが企画・批評・改善を繰り返すローカルツール「Concept Arena」を自作し、さくらのAI Engineの無償枠を活用して推論を行った。

AI SUMMARYThe author built a local tool called Concept Arena that assigns the same product challenge to 10 AI teams with different perspectives, cycling through ideation and critique to surface new features for a personal video-management app, using Sakura's AI Engine free tier.

AI企画会議で10チームの案を個人開発アプリの新機能にするまで
コミュニティCommunityLocal Models·Qiita LLM

テンソル並列の列分割・行分割を数字で理解する — Qwen3.8-27B を RTX 5060 Ti 16GB ×2 で回すA hands-on guide explaining tensor parallelism column-split and row-split…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 5060 Ti 16GB を2枚使ったテンソル並列環境で Qwen3-27B を実行し、列分割・行分割の仕組みを具体的な数値で解説した実践記事。マルチGPU推論の理論と実装を同時に学べる点が有用。

AI SUMMARYA hands-on guide explaining tensor parallelism column-split and row-split mechanics with concrete numbers, demonstrated by running Qwen3-27B on two RTX 5060 Ti 16GB GPUs purchased ahead of a price hike.

テンソル並列の列分割・行分割を数字で理解する — Qwen3.8-27B を RTX 5060 Ti 16GB ×2 で回す
コミュニティCommunityLocal Models·Qiita LLM

RAGとローカルLLMとは何か?AIエージェントに「外部の知識」をどう持たせるかThis article concludes a series on AI agent design by explaining RAG and local…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RAGとローカルLLMの仕組みを解説し、AIエージェントが学習データ外の知識を活用するための設計手法を紹介するシリーズ最終回。外部知識をエージェントに組み込む実践的なアプローチをまとめている。

AI SUMMARYThis article concludes a series on AI agent design by explaining RAG and local LLMs, focusing on how agents can incorporate external knowledge beyond their training data into practical workflows.

RAGとローカルLLMとは何か?AIエージェントに「外部の知識」をどう持たせるか
8/20(木)Thu, Aug 205 entries
コミュニティCommunityLocal Models·Qiita LLM

RTX 4070で90日連続稼働したローカルLLMの電気代を気温別に測った — 夏と冬で電気代が2倍違ったA 90-day continuous run of Qwen 35B on an RTX 4070 home workstation revealed…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 4070にQwen 35Bを載せた自宅ワークステーションを90日間24時間稼働させ、気温別・タスク別に電気代を計測した結果、夏季と冬季で最大2倍の差が生じることが判明した。

AI SUMMARYA 90-day continuous run of Qwen 35B on an RTX 4070 home workstation revealed that ambient temperature doubles electricity costs between summer and winter, offering rare real-world data for local LLM operators.

RTX 4070で90日連続稼働したローカルLLMの電気代を気温別に測った — 夏と冬で電気代が2倍違った
コミュニティCommunityClaude Code·Zenn Claude

GLM-5.3:ポスト学習のみでTerminal-Benchスコアが6倍に向上GLM-5.3: 6x Terminal-Bench Gain From Post-Training Alone

重要度 MediumMedium priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約中国のZ.aiが追加事前学習なしのポスト学習だけでGLM-5.3をリリースし、Terminal-Bench 3.0スコアを4.6から28.3へと約6倍に引き上げた。サイバーセキュリティ分野でも予想外の性能向上が確認されており、ポスト学習の可能性を示す注目の成果だ。

AI SUMMARYZ.ai released GLM-5.3 using post-training alone—no new pretraining—pushing Terminal-Bench 3.0 from 4.6 to 28.3 and achieving unexpected cybersecurity gains, highlighting how much headroom remains in post-training optimization.

GLM-5.3: 6x Terminal-Bench Gain From Post-Training Alone
コミュニティCommunityLocal Models·Qiita LLM

Alibabaオープンモデルの現在地を整理。半年で30億DL・派生30万・Qwen3.8-27BはApache 2.0Alibaba's Qwen open models reached 3 billion downloads across all platforms in…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約AlibabaのQwenシリーズは直近6か月で全プラットフォーム合計30億ダウンロードを達成し、派生モデルも30万を超えた。Qwen3の8B〜27BモデルにはApache 2.0ライセンスが適用され、商用・研究用途での利用障壁が大きく下がっている。

AI SUMMARYAlibaba's Qwen open models reached 3 billion downloads across all platforms in six months, with over 300,000 derivative models created. Qwen3 models ranging from 8B to 27B parameters are released under Apache 2.0, significantly lowering barriers for commercial and research use.

Alibabaオープンモデルの現在地を整理。半年で30億DL・派生30万・Qwen3.8-27BはApache 2.0
コミュニティCommunityLocal Models·Qiita LLM

【ローカルLLM】Qwen3.8-27BをデュアルGPUで高速化するThis article explores running Qwen3.8-27B locally on a dual-GPU setup to…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 5070 Ti 単体では VRAM 不足だった Qwen3.8-27B を、デュアル GPU 構成にすることで高速かつ安定して動作させる手法を検証した記事。

AI SUMMARYThis article explores running Qwen3.8-27B locally on a dual-GPU setup to overcome the 16 GB VRAM limit of a single RTX 5070 Ti, demonstrating improved inference performance with Ollama.

【ローカルLLM】Qwen3.8-27BをデュアルGPUで高速化する
コミュニティCommunityLocal Models·Qiita LLM

深夜のデッドロックからエンジニアを守る!非同期Python×ローカルLLM例外自動修復&AST安全検This article details a suite that combines async Python with a local LLM to…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約非同期PythonとローカルLLMを組み合わせ、実行時例外を自動検出・修復しASTで安全性を検証するスイートの設計と実装を解説。深夜障害対応の負担を減らす実践的アーキテクチャとして注目される。

AI SUMMARYThis article details a suite that combines async Python with a local LLM to automatically detect and repair runtime exceptions, then validates fixes via AST analysis before applying them. The approach aims to reduce on-call burden during late-night incidents.

深夜のデッドロックからエンジニアを守る!非同期Python×ローカルLLM例外自動修復&AST安全検
8/18(火)Tue, Aug 181 entries
コミュニティCommunityLocal Models·Qiita LLM

Tencent Cloud TokenHubのモデルをDeepSeek Harnessで利用する方法This article explains how to connect Tencent Cloud TokenHub models to DeepSeek…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeek Harnessを使い、Tencent Cloud TokenHub上のモデルをローカル環境から呼び出す設定手順を解説した記事で、オープンモデルの活用幅が広がる。

AI SUMMARYThis article explains how to connect Tencent Cloud TokenHub models to DeepSeek Harness (dsh), broadening options for running open models via the CLI tool while it remains in Developer Preview.

Tencent Cloud TokenHubのモデルをDeepSeek Harnessで利用する方法