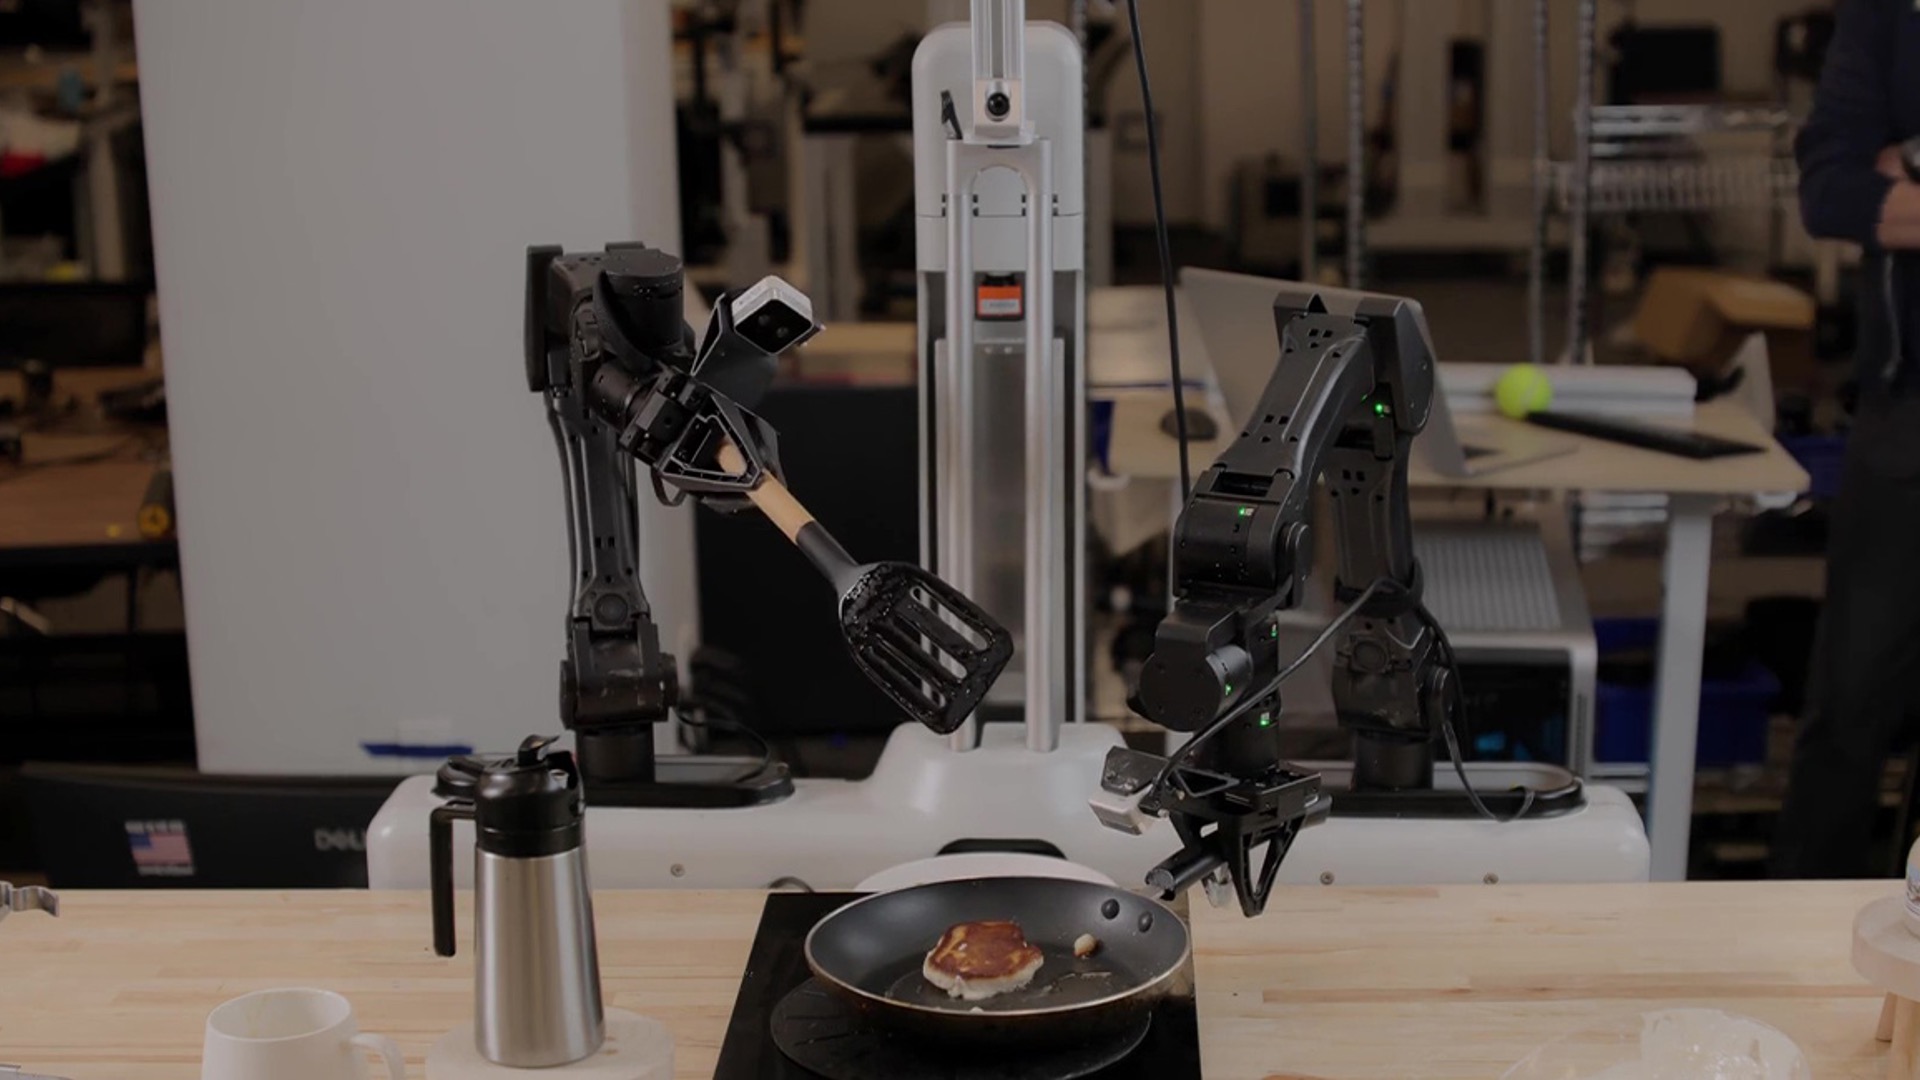
Skild AI、NVIDIAのフィジカルAIで1本の動画からロボットに新作業を学習させるSkild AI Taps NVIDIA Physical AI to Teach Robots New Tasks From a Single Video
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
- Skild AIのロボット基盤モデルS1は、1本の動画実演から未知の長時間タスクを学べる。
- 重み更新や個別の追加学習なしで作業を理解・実行し、製造・物流現場の柔軟な自動化を後押しする。
- Skild AI's S1 robot foundation model learns unfamiliar, long-horizon tasks from one video demonstration.
- It performs work without weight updates or task-specific retraining, helping factories and warehouses adapt automation faster.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (blogs.nvidia.com) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (blogs.nvidia.com).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
1本の動画実演
Skild AIが発表したロボット基盤モデル「S1」は、1本の動画実演から、これまで経験していない長時間の作業を学習できるよう設計されている。大幅な再プログラミングを必要とするロボットに対し、変化する現場へ適応しやすい仕組みを目指したモデルだ。
製造フロアや倉庫、生産ラインでは、担当する作業だけでなく、設備の配置や扱う製品も変化する。S1は動画を入力として受け取り、映像で示された作業の内容を理解して実行することで、こうした固定されていない環境への対応を支援する。
インコンテキスト学習
S1の特徴は、モデルの重みを更新せず、作業ごとの追加学習も行わない点にある。動画による実演をその場の文脈として利用し、未知の作業を理解して実行する。この手法はインコンテキスト学習と呼ばれている。
個別の作業に合わせた事後学習を経ずに実行へ移れるため、作業内容や配置が変わる製造・物流現場において、柔軟な自動化を後押しするものと説明されている。対象には、短い動作だけでなく、複数の工程が続く長時間タスクも含まれる。
NVIDIA AI基盤
Skild AIは、NVIDIA AIインフラストラクチャ上でS1を構築し、関連する研究も実施した。両社の協業はモデル開発だけに限らず、合成データの生成、モデル学習、シミュレーション、現実環境でのフィジカルAI展開に及ぶ。
両社は、適応可能なロボット知能を研究室から工場や、そのほかの動的な稼働環境へ移すために共同で取り組んでいる。S1は、その中で動画を通じて新しい作業を扱う役割を担う。
Manufacturing Floors and Warehouses
Skild AI’s S1 robot foundation model is designed to learn previously unseen, long-horizon tasks from a single video demonstration. This matters for manufacturing floors, warehouses and production lines, where tasks, layouts and products can change while most robots require significant reprogramming to keep up.
S1 is intended to support more adaptable automation by allowing a robot to understand and perform unfamiliar work from a video rather than through a task-specific programming process.
One Video Demonstration
Video serves as the model’s input, showing the task that the robot is expected to understand and execute. According to the announcement, one demonstration is sufficient for S1 to learn a previously unseen task, including work that extends across a long sequence of actions.
The model was launched last week. Its central capability is learning directly from the context provided by the video, rather than relying on a separate training process tailored to each new task.
In-Context Learning
S1 performs the demonstrated work without updating its model weights or undergoing task-specific post-training. This approach is called in-context learning.
By avoiding weight updates and individual retraining for each task, the model is designed to help factories and warehouses adapt automation faster as operating conditions change. The stated focus is on understanding and executing the demonstrated task while leaving the underlying model weights unchanged.
NVIDIA AI Infrastructure
Skild AI built S1 and conducted the associated research using NVIDIA AI infrastructure. The work forms part of a broader collaboration between Skild AI and NVIDIA spanning synthetic data generation, model training, simulation and real-world physical AI deployment.
The companies are working together to move adaptable robot intelligence from the laboratory into factories and other dynamic operating environments.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPokoたった1本の動画で、未知の長時間タスクを学べるって驚いた! これって大きいこと?Learning an unfamiliar, long task from just one video sounds wild! Is that a big deal?
- TECHガイドTECH Guideこの記事では、多くのロボットは作業変更に大幅な再プログラムが要るとされる。それを減らして柔軟な自動化を狙う点が大きいのじゃ。The article says many robots need major reprogramming when work changes. S1 aims to reduce that burden and make automation more adaptable—that’s the significant part.
- ポコPoko「インコンテキスト学習」って何? 動画を見るだけで学ぶって、つまりどういうこと?What’s “in-context learning”? What does it mean for a robot to learn just by watching a video?
- TECHガイドTECH Guide紹介された仕組みでは、動画を手本に作業を理解し、重みの更新や作業別の追加学習なしで実行することじゃよ。Here, it means using the video as an example, then understanding and performing the task without changing the model’s weights or doing extra task-specific training.
- ポコPoko自分なら、新製品が来た工場や配置が変わった倉庫で、作業動画を見せて素早く対応させたいな!I’d use it in a factory with a new product or a warehouse with a changed layout—show the task once and adapt quickly!
- TECHガイドTECH Guideまさにそうした変化の多い現場を想定した技術じゃ。ただし本文で示された使い方は、まず1本の実演動画を入力するのが前提じゃよ。That’s exactly the kind of changing workplace it targets. In the setup described, though, the robot first needs a single demonstration video as its input.





