TPU上の動画拡散向け時空間アテンションを高速化Accelerating Spatio-Temporal Attention for Video Diffusion on TPUs
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
- Sparse VideoGenは、注意ヘッドを空間・時間方向の疎なマスクへ動的に振り分ける。
- TPU向けSplash Attentionで空タイルを省き、高解像度動画生成の高速化を可能にする。
- Sparse VideoGen assigns attention heads on the fly to sparse spatial or temporal patterns.
- TPU-tuned Splash Attention skips empty tiles, speeding diffusion-based creation of high-resolution video.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (developers.googleblog.com) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (developers.googleblog.com).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
二次遅延
高解像度の動画拡散モデルでは、自己アテンションの二次的な遅延がボトルネックになる。これに対し、Sparse VideoGen(SVG)とTPU向けSplash Attentionの最適化を組み合わせ、1440p動画生成のエンドツーエンド推論で最大1.69倍の高速化を達成した。
疎なマスク
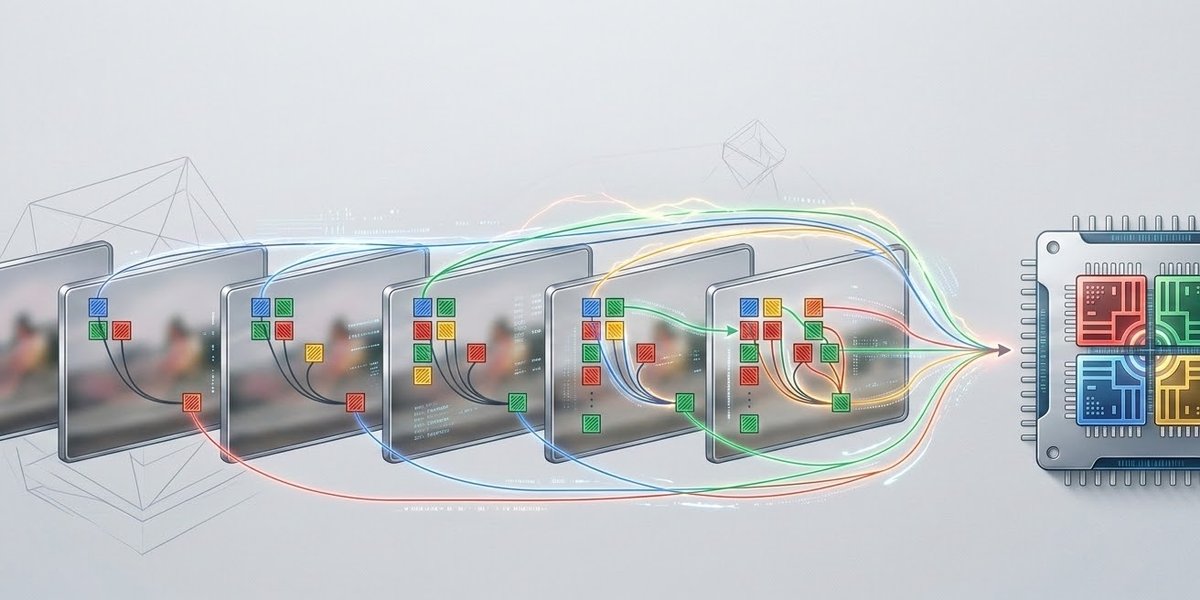
SVGは、注意ヘッドを高度に構造化された空間方向または時間方向の疎なマスクへ動的に振り分ける。すべての注意ヘッドで一様に処理するのではなく、空間・時間の各パターンに応じてルーティングすることで、アルゴリズム上の疎性を作り出す仕組みだ。
ただし、計算対象を疎にするだけでは、TPU上の実処理がそのまま速くなるとは限らない。物理的な高速化につなげるには、疎なマスクとハードウェアのタイル実行を対応させ、不要な処理を実際に省けるようにする必要があった。
空タイル
TPU向けSplash Attentionカーネルでは、メモリ上の空タイルを迂回し、計算対象から外すよう最適化した。さらに、正確な座標マスキングを境界タイルだけに限定した。これにより、疎な領域に対して発生していた無駄な行列演算を削減している。
時間優先順
トークンのメモリ配置も時間優先順へ並べ替え、連続アクセスが可能になるよう調整した。疎なマスクの構造、タイル単位の実行、メモリ上の並びをそろえることで、SVGのアルゴリズム上の疎性をTPU上の処理削減へ結び付けた。
Quadratic Latency Bottleneck
High-resolution video diffusion models face a quadratic latency bottleneck in self-attention. Sparse VideoGen addresses this bottleneck by combining dynamic attention routing with TPU-focused kernel and memory-layout optimizations, significantly reducing wasted matrix operations during video generation.
The central challenge was not only to introduce algorithmic sparsity, but also to translate that sparsity into physical hardware speedups. The implementation therefore aligned sparse attention patterns with the way hardware tiles are executed on TPUs.
Sparse VideoGen
Sparse VideoGen dynamically assigns attention heads to highly structured sparse masks. Depending on the routing, an attention head uses either a spatial sparse pattern or a temporal sparse pattern.
This on-the-fly assignment reduces the work associated with self-attention while retaining separate spatial and temporal structures. However, sparse masks alone were not sufficient to deliver the targeted hardware gains. The sparse patterns also had to correspond to the actual execution and memory-access behavior of the TPU.
Splash Attention
Developers optimized the Splash Attention kernel so that empty memory tiles could be bypassed rather than processed. This made the kernel’s execution more closely reflect the sparse structure selected by Sparse VideoGen and reduced matrix operations that would otherwise be wasted on empty regions.
Exact coordinate masking was restricted strictly to boundary tiles. Token memory layouts were also permuted into temporal-major order, providing contiguous access for the temporal patterns. Together, skipping empty tiles, limiting exact masking to boundaries, and reorganizing token memory connected the algorithm’s spatial and temporal sparsity to physical tile execution.
End-to-End Inference Speedup
The combined optimizations accelerated diffusion-based creation of high-resolution video on TPUs. By aligning sparse masks, tile processing, coordinate masking, and contiguous temporal access, the implementation achieved up to a 1.69x end-to-end inference speedup for 1440p video generation.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPoko1440p動画生成で推論が最大1.69倍に速くなったの? これって大きいこと?Inference for 1440p video generation was up to 1.69× faster? Is that a big change?
- TECHガイドTECH Guide全体の推論時間で出た最大値だよ。使わない行列演算を減らした効果が、処理全体の高速化につながっているね。That’s the maximum end-to-end inference speedup reported. It shows that cutting wasted matrix operations can improve the whole process.
- ポコPoko「空のタイルを飛ばす」って、どういう仕組みなんだろう?What does “skipping empty tiles” actually mean?
- TECHガイドTECH Guideタイルは処理するデータの区画みたいなものだよ。計算対象がない区画を通らず、境界だけ座標を正確に確認する仕組みなんだ。A tile is like a block of data to process. Empty blocks are bypassed, while exact coordinate masking is limited to boundary tiles.
- ポコPoko自分なら、1440p動画を作る待ち時間を短くしたいときに使えたらうれしいな。I’d want to use it to cut the wait when creating 1440p videos.
- TECHガイドTECH Guideその使い方に合いそうだね。ただしTPU向けのSplash Attention最適化が前提で、1.69倍はあくまで最大の結果だよ。That fits the reported use case. Just note that it relies on TPU-tuned Splash Attention, and 1.69× is the maximum result, not a guaranteed speedup.



