EmbeddingGemma 2:開発者ガイドEmbeddingGemma 2: The Developer Guide
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
- EmbeddingGemma 2は、テキスト、コード、画像、動画、音声を768次元の共通表現へ変換するオープンソースモデルです。
- 用途別エンコーダーと128次元までの短縮により、開発者はメモリとベクトル保存量を抑えながら検索性能を維持できます。
- EmbeddingGemma 2 unifies text, code, image, video, and audio embeddings in 768 dimensions.
- Modular encoders and 128d truncation help developers cut memory and vector storage costs.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (developers.googleblog.com) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (developers.googleblog.com).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
768次元の共通表現
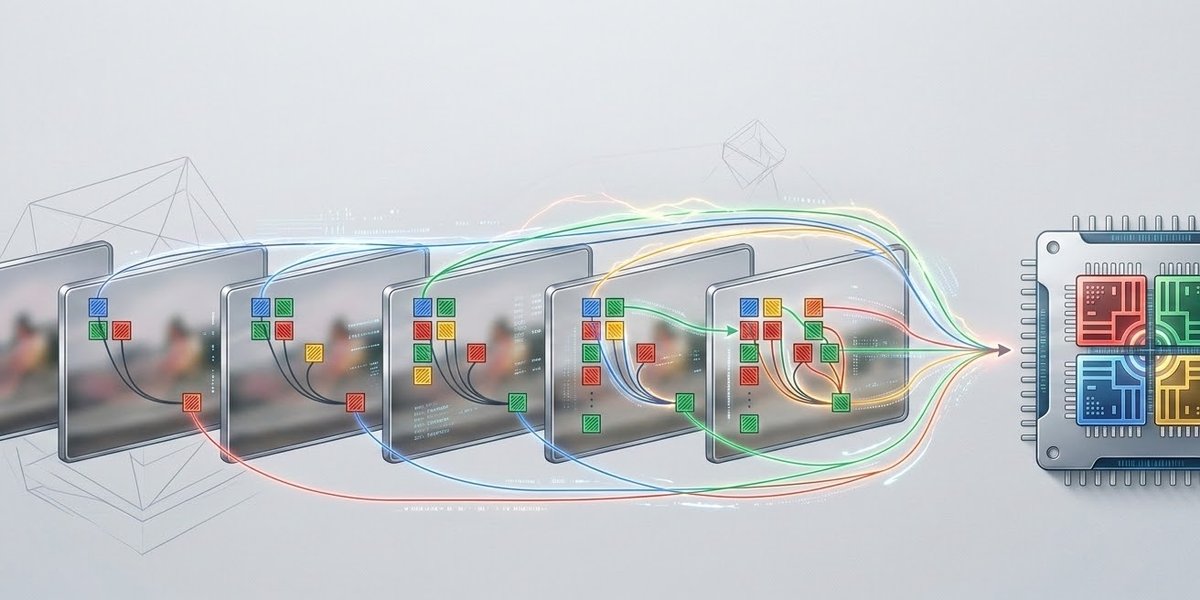
EmbeddingGemma 2は、テキスト、コード、画像、動画、音声を、統一された768次元空間へ変換するコンパクトなオープンソースのマルチモーダル埋め込みモデルです。異なる種類のデータを共通表現へ写像し、検索に利用できる点が中核となります。
ここでいう768次元は、各入力を768個の要素からなる表現として扱うことを示します。テキストや画像だけでなく、コード、動画、音声も同じ次元数の空間へ変換されるため、複数のモダリティを統一的な埋め込みとして扱えます。
選択式エンコーダー
開発者はsentence-transformersライブラリを使い、モダリティ別に分かれたモジュール式エンコーダーを選択的に読み込めます。エンコーダーの規模は270Mから740Mパラメーターまで用意されており、必要なモダリティに応じて読み込み対象を選べます。
すべてを一律に読み込むのではなく、用途に必要なエンコーダーへ絞ることで、メモリ使用量を最適化できると説明されています。扱うデータの種類と利用可能なメモリに合わせて構成を調整できる仕組みです。
128次元への短縮
Matryoshka Representation Learningにより、埋め込みの次元数は動的に128次元まで短縮できます。標準の768次元表現を常にそのまま保存するのではなく、用途に応じてより短い表現を利用できる設計です。
次元を短くすると、ベクトルデータベースに保存する要素数を抑えられます。これにより保存要件を大幅に削減しながら、高い検索性能を維持できるとされています。モジュール式エンコーダーによるメモリ最適化と組み合わせ、読み込み時と保存時の双方で使用量を調整できます。
EmbeddingGemma 2
EmbeddingGemma 2 is a compact, open-source multimodal embedding model designed for text, code, images, video, and audio. It matters for developers because these different inputs can be mapped into one shared representation while memory usage and vector storage requirements can be adjusted.
Unified 768-dimensional space
The model maps every supported modality into a unified 768-dimensional space. Text and code can therefore be represented in the same dimensional space as images, video, and audio.
This unified design provides a common embedding format across the five input types. The model’s output begins at 768 dimensions, while its dimension-reduction capability gives developers an option to use smaller representations when required.
Modular modality encoders
EmbeddingGemma 2 uses modular modality encoders ranging from 270M to 740M parameters. Developers can use the sentence-transformers library to load these encoders selectively.
Selective loading allows an application to load the modality encoders it needs rather than treating all modalities as a single fixed requirement. This enables developers to optimize memory usage according to the text, code, image, video, or audio capabilities required for a particular use.
The different encoder sizes also give developers a defined range of 270M to 740M parameters within the model’s modular structure.
Dynamic dimension truncation
EmbeddingGemma 2 also uses Matryoshka Representation Learning to support dynamic dimension truncation. Embeddings can be shortened from the unified 768-dimensional representation down to 128 dimensions.
Reducing the number of dimensions lowers vector database storage requirements. According to the source, this truncation maintains high retrieval performance while significantly reducing the storage needed for vectors.
Together, selective modality-encoder loading and truncation to 128 dimensions provide two separate controls: one for optimizing memory usage when loading encoders, and another for reducing the amount of vector storage required for embeddings.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPoko仕事で検索を作るなら、文章だけじゃなく画像や音声もまとめて探せるようになるの?If I’m building search for work, could this help search across images and audio, not just text?
- TECHガイドTECH Guideこの記事では、テキスト、コード、画像、動画、音声を共通の768次元表現に変換できるよ。種類をまたぐ検索に使えるモデルなんだ。It maps text, code, images, video, and audio into one shared 768-dimensional representation, so the model can support search across those formats.
- ポコPoko前は、必要のない種類の機能まで全部読み込まないといけなかったの?Before this, did developers have to load support for every format, even when they didn’t need it?
- TECHガイドTECH Guide従来との厳密な違いは書かれていないよ。今回は用途別エンコーダーを選んで読み込み、メモリ使用量を調整できるとしている。The piece doesn’t spell out the exact previous limitation. Here, developers can selectively load modality encoders to optimize memory use.
- ポコPoko必要な機能だけ選び、128次元まで短くして、検索性能を保ちながらメモリや保存量を抑えられるのが大きいんだね。So the big takeaway is choosing only what you need and trimming to 128 dimensions, while keeping retrieval performance high and reducing memory and storage.
- TECHガイドTECH Guide次に注目するなら、270M〜740Mの用途別エンコーダーと、128次元への短縮をどう組み合わせるかだね。Next, watch how developers combine the 270M-to-740M modality encoders with truncation down to 128 dimensions.