Home›Tags›#gguf

Tag timeline

#gguf12 total

同じキーワードで束ねられた更新を確認できます。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total12#gguf の全掲載記事All listed entries tagged #gguf
Showing12このページの件数Entries on this page
Page1/1静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 1/1 · 12 total

10/5(月)Mon, Oct 51 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Qwen3.8 27Bによる足し算の文章回答Qwen3.8 27B addition in words

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Qwen3.8 27Bは、大きくなる数の足し算を行い、答えを数字ではなく言葉で返す試験をDGX Spark上で実施した。管理されたローカル環境でGPT-4oとの計算能力を比較できる。

AI SUMMARYQwen3.8 27B was tested on increasingly large additions while spelling out each result, using a Q4_K_M GGUF on DGX Spark. This enables a controlled local comparison with GPT-4o.
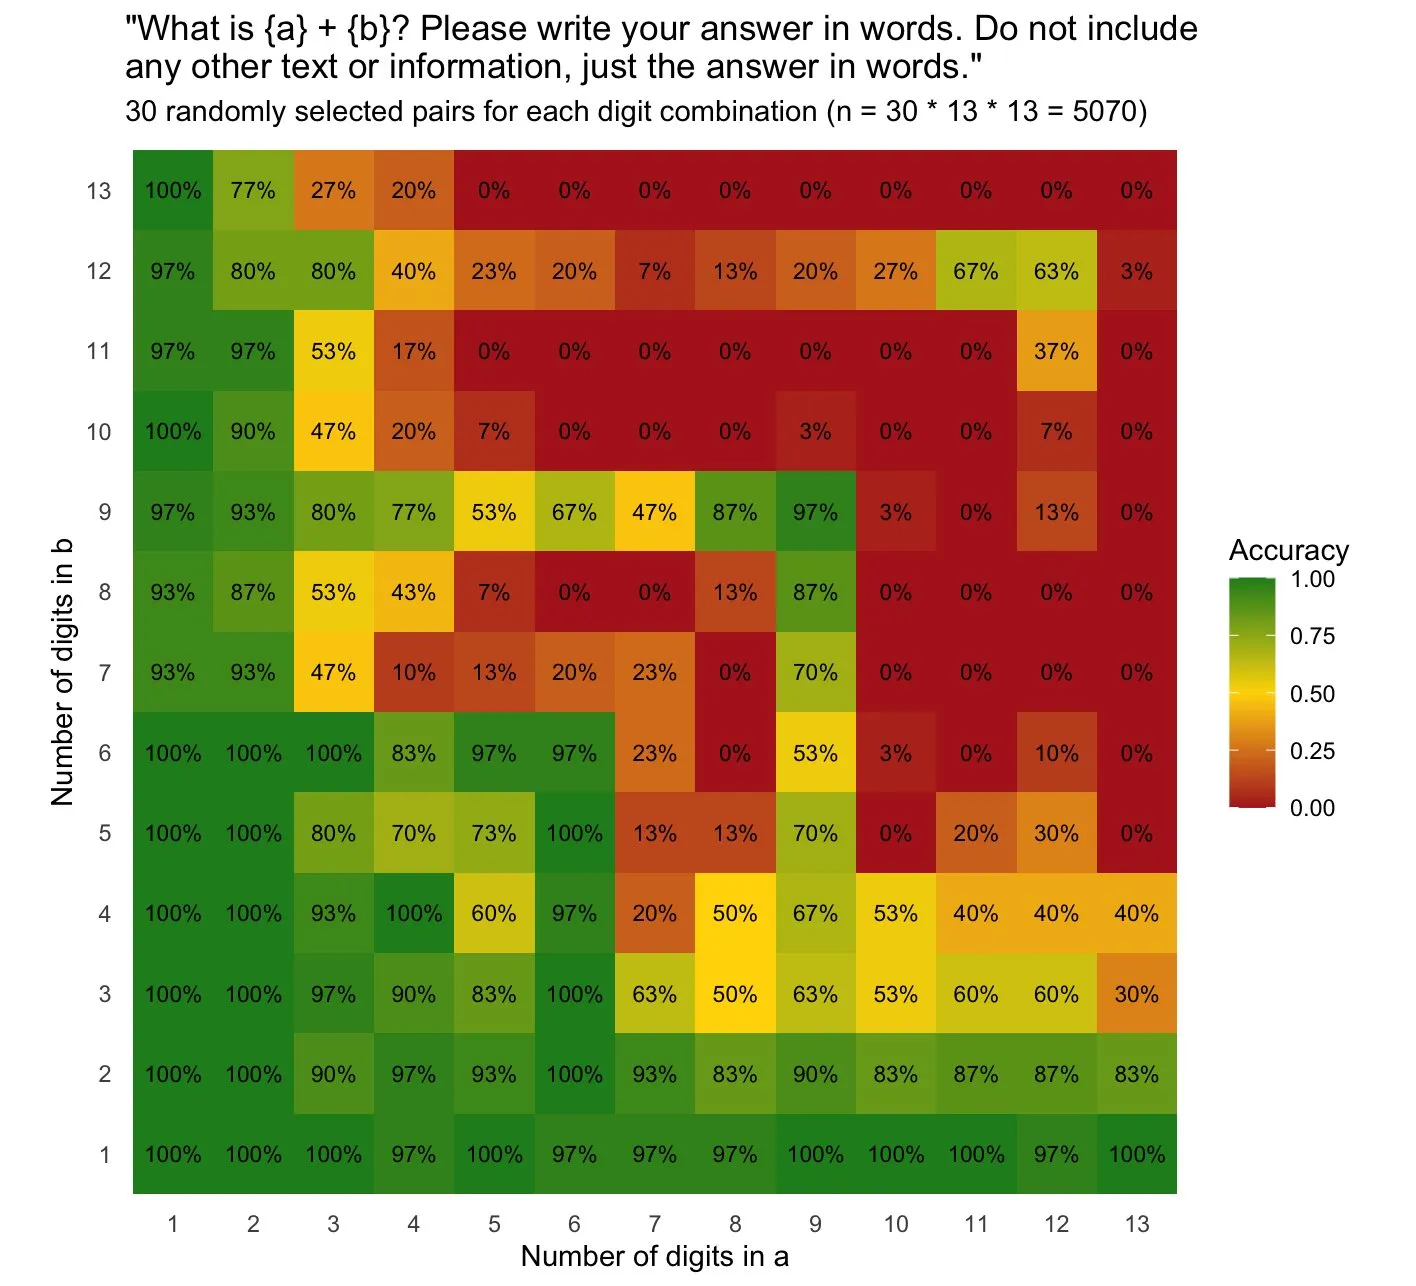
Qwen3.8 27B addition in words
9/25(金)Fri, Sep 251 entries
公式OfficialLocal Models·Ollama Releases

v0.40.0-rc0:llama-serverの互換性パッチ削除に向けた準備v0.40.0-rc0: llama-server: prepare to remove compatibility patch

重要度 InfoInformational深掘り候補 · 公式リリース · Local LLM / Open ModelsDeep-dive candidate · official release · Local LLM / Open Models

AI要約Ollama v0.40.0-rc0は、単一タグでランナー別マニフェストを管理する仕組みと、旧形式GGUFの遅延移行を追加した。子マニフェストやレイヤーも扱えるため、llama.cpp互換化を安全に進められる。

AI SUMMARYOllama v0.40.0-rc0 adds manifest lists for multiple runner variants per tag and on-demand migration of legacy GGUF models, enabling safer llama.cpp compatibility.

v0.40.0-rc0: llama-server: prepare to remove compatibility patch
9/18(金)Fri, Sep 181 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Bonsai 2 27B:約9分の1の容量でほぼ無損失の圧縮Bonsai 2 27B: Near-Lossless Compression in a 9x Smaller Footprint

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Bonsai 2 27Bは、品質低下を抑えつつ通常の約9分の1となる約5.95GBのGGUFで提供される。実行にはPrism版llama.cppが必要で、Apple silicon搭載Macでのローカル運用を可能にする。

AI SUMMARYBonsai 2 27B comes as a roughly 5.95 GB GGUF, about one-ninth the normal size with little quality loss. Prism's llama.cpp fork is needed, helping Mac users run it locally.

9/15(火)Tue, Sep 151 entries
公式OfficialLocal Models·Ollama Releases

v0.34.1-rc2:APIのtypical_pを非推奨化(#18448)v0.34.1-rc2: API: Deprecate typical_p (#18448)

重要度 InfoInformational深掘り候補 · 公式リリース · Local LLM / Open ModelsDeep-dive candidate · official release · Local LLM / Open Models

AI要約Ollama v0.34.1-rc2は、APIのtypical_pパラメーターを非推奨としつつ、この設定を使う既存GGUFモデルへの対応を維持する。利用者は互換性を保ちながら将来のAPI変更に備えられる。

AI SUMMARYOllama v0.34.1-rc2 deprecates the typical_p API parameter but keeps GGUF models already configured with it working, letting users plan migrations without an immediate break.

v0.34.1-rc2: API: Deprecate typical_p (#18448)
9/3(木)Thu, Sep 31 entries
公式OfficialLocal Models·Ollama Releases

Ollama v0.33.3-rc1がリリースOllama Releases v0.33.3-rc1

重要度 InfoInformational深掘り候補 · 公式リリース · Local LLM / Open ModelsDeep-dive candidate · official release · Local LLM / Open Models

AI要約Ollama v0.33.3は、キャッシュ済みプロンプトのトークン数を報告し、GGUFモデル既定のパラメーターを反映するよう改善。MLX、MLX-C、llama.cppも更新され、ローカルLLM利用者の互換性と把握性が高まります。

AI SUMMARYOllama v0.33.3 adds cached prompt token reporting and respects GGUF model defaults, alongside MLX, MLX-C, and llama.cpp updates, benefiting local LLM users.

Ollama Releases v0.33.3-rc1
8/16(日)Sun, Aug 161 entries
コミュニティCommunityLocal Models·Qiita LLM

【ローカルLLM】Qwen3.8-27Bの推論性能をテストする(WSL2 + Ollama + RTX 5070 Ti)A hands-on benchmark of Qwen3.8-27B running locally via Ollama on WSL2 with an…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約新公開のQwen3.8-27BをWSL2+Ollama+RTX 5070 Ti環境でローカル動作させ、ThinkモードでのGGUF量子化モデルの推論性能を検証した実践レポート。

AI SUMMARYA hands-on benchmark of Qwen3.8-27B running locally via Ollama on WSL2 with an RTX 5070 Ti, evaluating reasoning performance in Think mode using a Q4_K_M GGUF quantized model.

【ローカルLLM】Qwen3.8-27Bの推論性能をテストする(WSL2 + Ollama + RTX 5070 Ti)
8/9(日)Sun, Aug 91 entries
コミュニティCommunityLocal Models·Qiita LLM

LLM の量子化モデルで必要メモリと推論速度を見積もる方法This article explains how to accurately estimate memory requirements and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Q4_K_MやQ5_K_Mといった量子化表記だけではモデルのメモリ使用量や推論速度は判断できないため、正確な見積もりに必要な指標と計算方法を解説した記事です。

AI SUMMARYThis article explains how to accurately estimate memory requirements and inference speed for quantized LLM models, clarifying why bit-width labels like Q4_K_M alone are insufficient for practical deployment decisions.

LLM の量子化モデルで必要メモリと推論速度を見積もる方法
8/2(日)Sun, Aug 21 entries
コミュニティCommunityLocal Models·Zenn LLM

Ollama 0.30.8はMLXランナーを内蔵するがGGUFは通らない — M1 Max 64GB実測Ollama 0.30.8 ships with an integrated MLX runner for Apple Silicon, but…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Ollama 0.30.8にMLXバックエンドが統合されたが、バイナリ解析とログ突合の結果、通常の`ollama pull`で取得するGGUFモデルはMLXランナーを経由しないことが判明した。速度改善の恩恵を受けるにはモデル形式の確認が必要となる。

AI SUMMARYOllama 0.30.8 ships with an integrated MLX runner for Apple Silicon, but hands-on investigation on an M1 Max 64GB showed that standard GGUF models pulled via `ollama pull` do not go through the MLX path, meaning users cannot assume a speed gain without verifying the active backend.

Ollama 0.30.8はMLXランナーを内蔵するがGGUFは通らない — M1 Max 64GB実測
7/31(金)Fri, Jul 311 entries
コミュニティCommunityLocal Models·Qiita LLM

TensorSharp とは — C# だけで動く GGUF 推論エンジンが llama.cpp に挑むTensorSharp, a pure C# inference engine for GGUF models, has published…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約.NET製推論エンジン「TensorSharp」がGGUFモデルをC#のみで実行し、llama.cppとのベンチマーク結果を公開してローカルLLMコミュニティで注目を集めている。

AI SUMMARYTensorSharp, a pure C# inference engine for GGUF models, has published benchmarks against llama.cpp, demonstrating that .NET can be a viable platform for local LLM inference.

TensorSharp とは — C# だけで動く GGUF 推論エンジンが llama.cpp に挑む
7/27(月)Mon, Jul 271 entries
コミュニティCommunityLocal Models·Zenn LLM

量子化フォーマットを比較する:GGUF・AWQ・GPTQをvLLMで実測するThis article benchmarks GGUF, AWQ, and GPTQ quantization formats on vLLM,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約GGUF・AWQ・GPTQの3つの量子化フォーマットをvLLM上で実際に計測し、推論速度・メモリ使用量・精度の観点から違いを明らかにした記事。ローカルLLM運用における最適なフォーマット選択の指針となる。

AI SUMMARYThis article benchmarks GGUF, AWQ, and GPTQ quantization formats on vLLM, comparing inference speed, memory usage, and accuracy to help practitioners choose the right format for local LLM deployment.

量子化フォーマットを比較する:GGUF・AWQ・GPTQをvLLMで実測する
7/26(日)Sun, Jul 261 entries
コミュニティCommunityLocal Models·Zenn LLM

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違いAn investigation into why perplexity scores diverged between llama.cpp and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約GGUF形式で互換性があるはずのモデルでも、llama.cpp と他実装でパープレキシティが一致しない原因をLayer 0まで追跡した結果、テンソル演算の経路の違いが数値誤差を生むことが判明した。推論再現性を重視する開発者にとって重要な知見。

AI SUMMARYAn investigation into why perplexity scores diverged between llama.cpp and another GGUF-compatible runtime traced the root cause to differences in tensor computation paths at Layer 0, revealing that format compatibility alone does not guarantee numerical reproducibility.

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違い
7/25(土)Sat, Jul 251 entries
コミュニティCommunityCopilot·Qiita GitHub Copilot

LMStudioとOllamaでggufモデルを相互利用する!This article explains how to share and reuse GGUF model files between LM Studio…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約LMStudioとOllamaはどちらもgguf形式のモデルをローカルで実行できるツールであり、両者のモデルファイルを共有・流用する手順を解説した実用的な記事です。

AI SUMMARYThis article explains how to share and reuse GGUF model files between LM Studio and Ollama, helping users avoid redundant downloads and get more out of their local AI setup.

LMStudioとOllamaでggufモデルを相互利用する!