Home›Tags›#rag

Tag timeline

#rag27 total

同じキーワードで束ねられた更新を確認できます。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total27#rag の全掲載記事All listed entries tagged #rag
Showing27このページの件数Entries on this page
Page1/1静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 1/1 · 27 total

10/1(木)Thu, Oct 11 entries
公式OfficialNews/Policy·AWS News Blog

Amazon S3 Vectors、絞り込み検索の再現率を高めるメタデータ事前フィルタリングに対応Amazon S3 Vectors now supports metadata pre-filtering for higher recall on filtered searches

重要度 MediumMedium priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約Amazon S3 Vectorsは、類似度検索より先に条件を適用するメタデータ事前フィルタリングに対応し、絞り込み検索の再現率を最大5倍に高めた。RAG、エージェント型アプリ、文書検索で、対象に合う結果をより確実に取得できる。

AI SUMMARYAmazon S3 Vectors adds metadata pre-filtering, applying constraints before similarity matching to raise filtered-search recall by up to 5x for RAG workflows, AI agents, and document discovery.
Amazon S3 Vectors now supports metadata pre-filtering for higher recall on filtered searches
9/19(土)Sat, Sep 191 entries
公式OfficialCopilot·GitHub Blog (AI & ML)

コードは読むべきか、RAGは死んだのか、SkillsはMCPを終わらせたのか?Should you read the code, is RAG dead, and did Skills kill MCP?

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約コード読解、RAGの終焉、SkillsによるMCPの代替という3つの主張を、前提や文脈、実務での条件から検証する。AI開発者が表面的な賛否を超えて技術を判断する助けになる。

AI SUMMARYThree AI development claims about reading code, RAG's death, and Skills replacing MCP are tested against context and real work, helping developers make informed choices.

Should you read the code, is RAG dead, and did Skills kill MCP?
8/26(水)Wed, Aug 261 entries
公式OfficialGemini/Gemma·Google Developers Blog

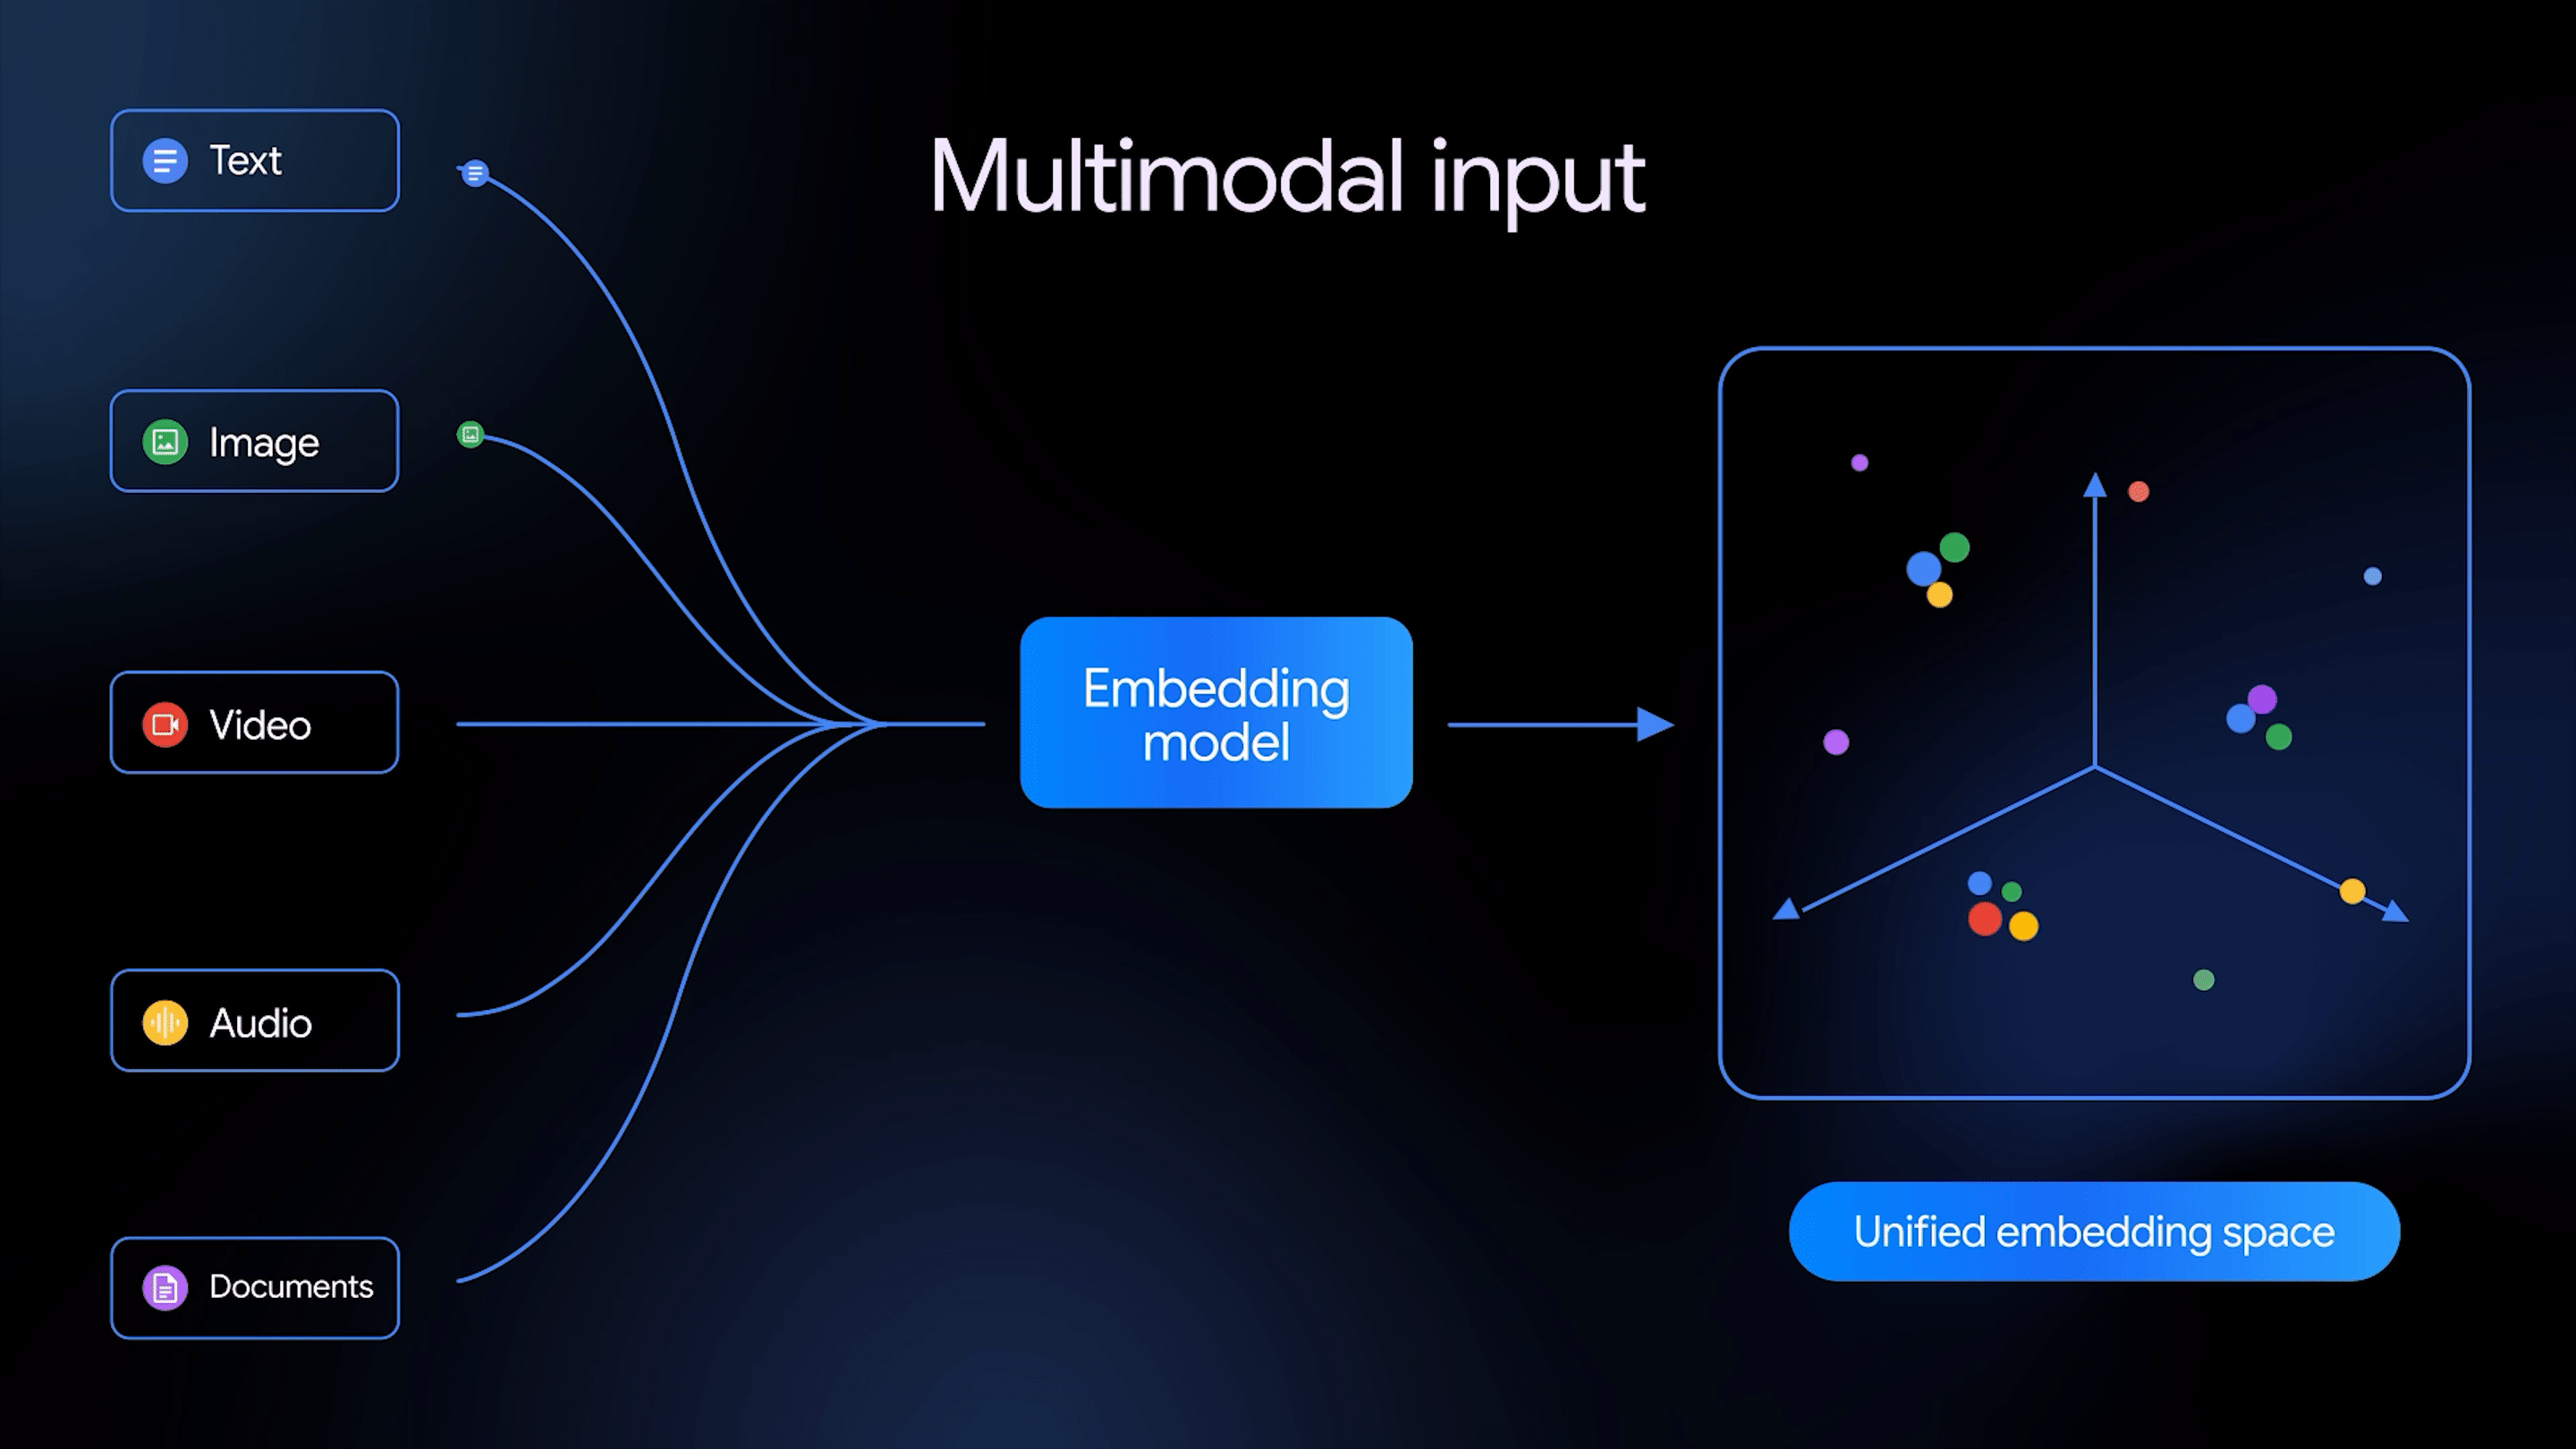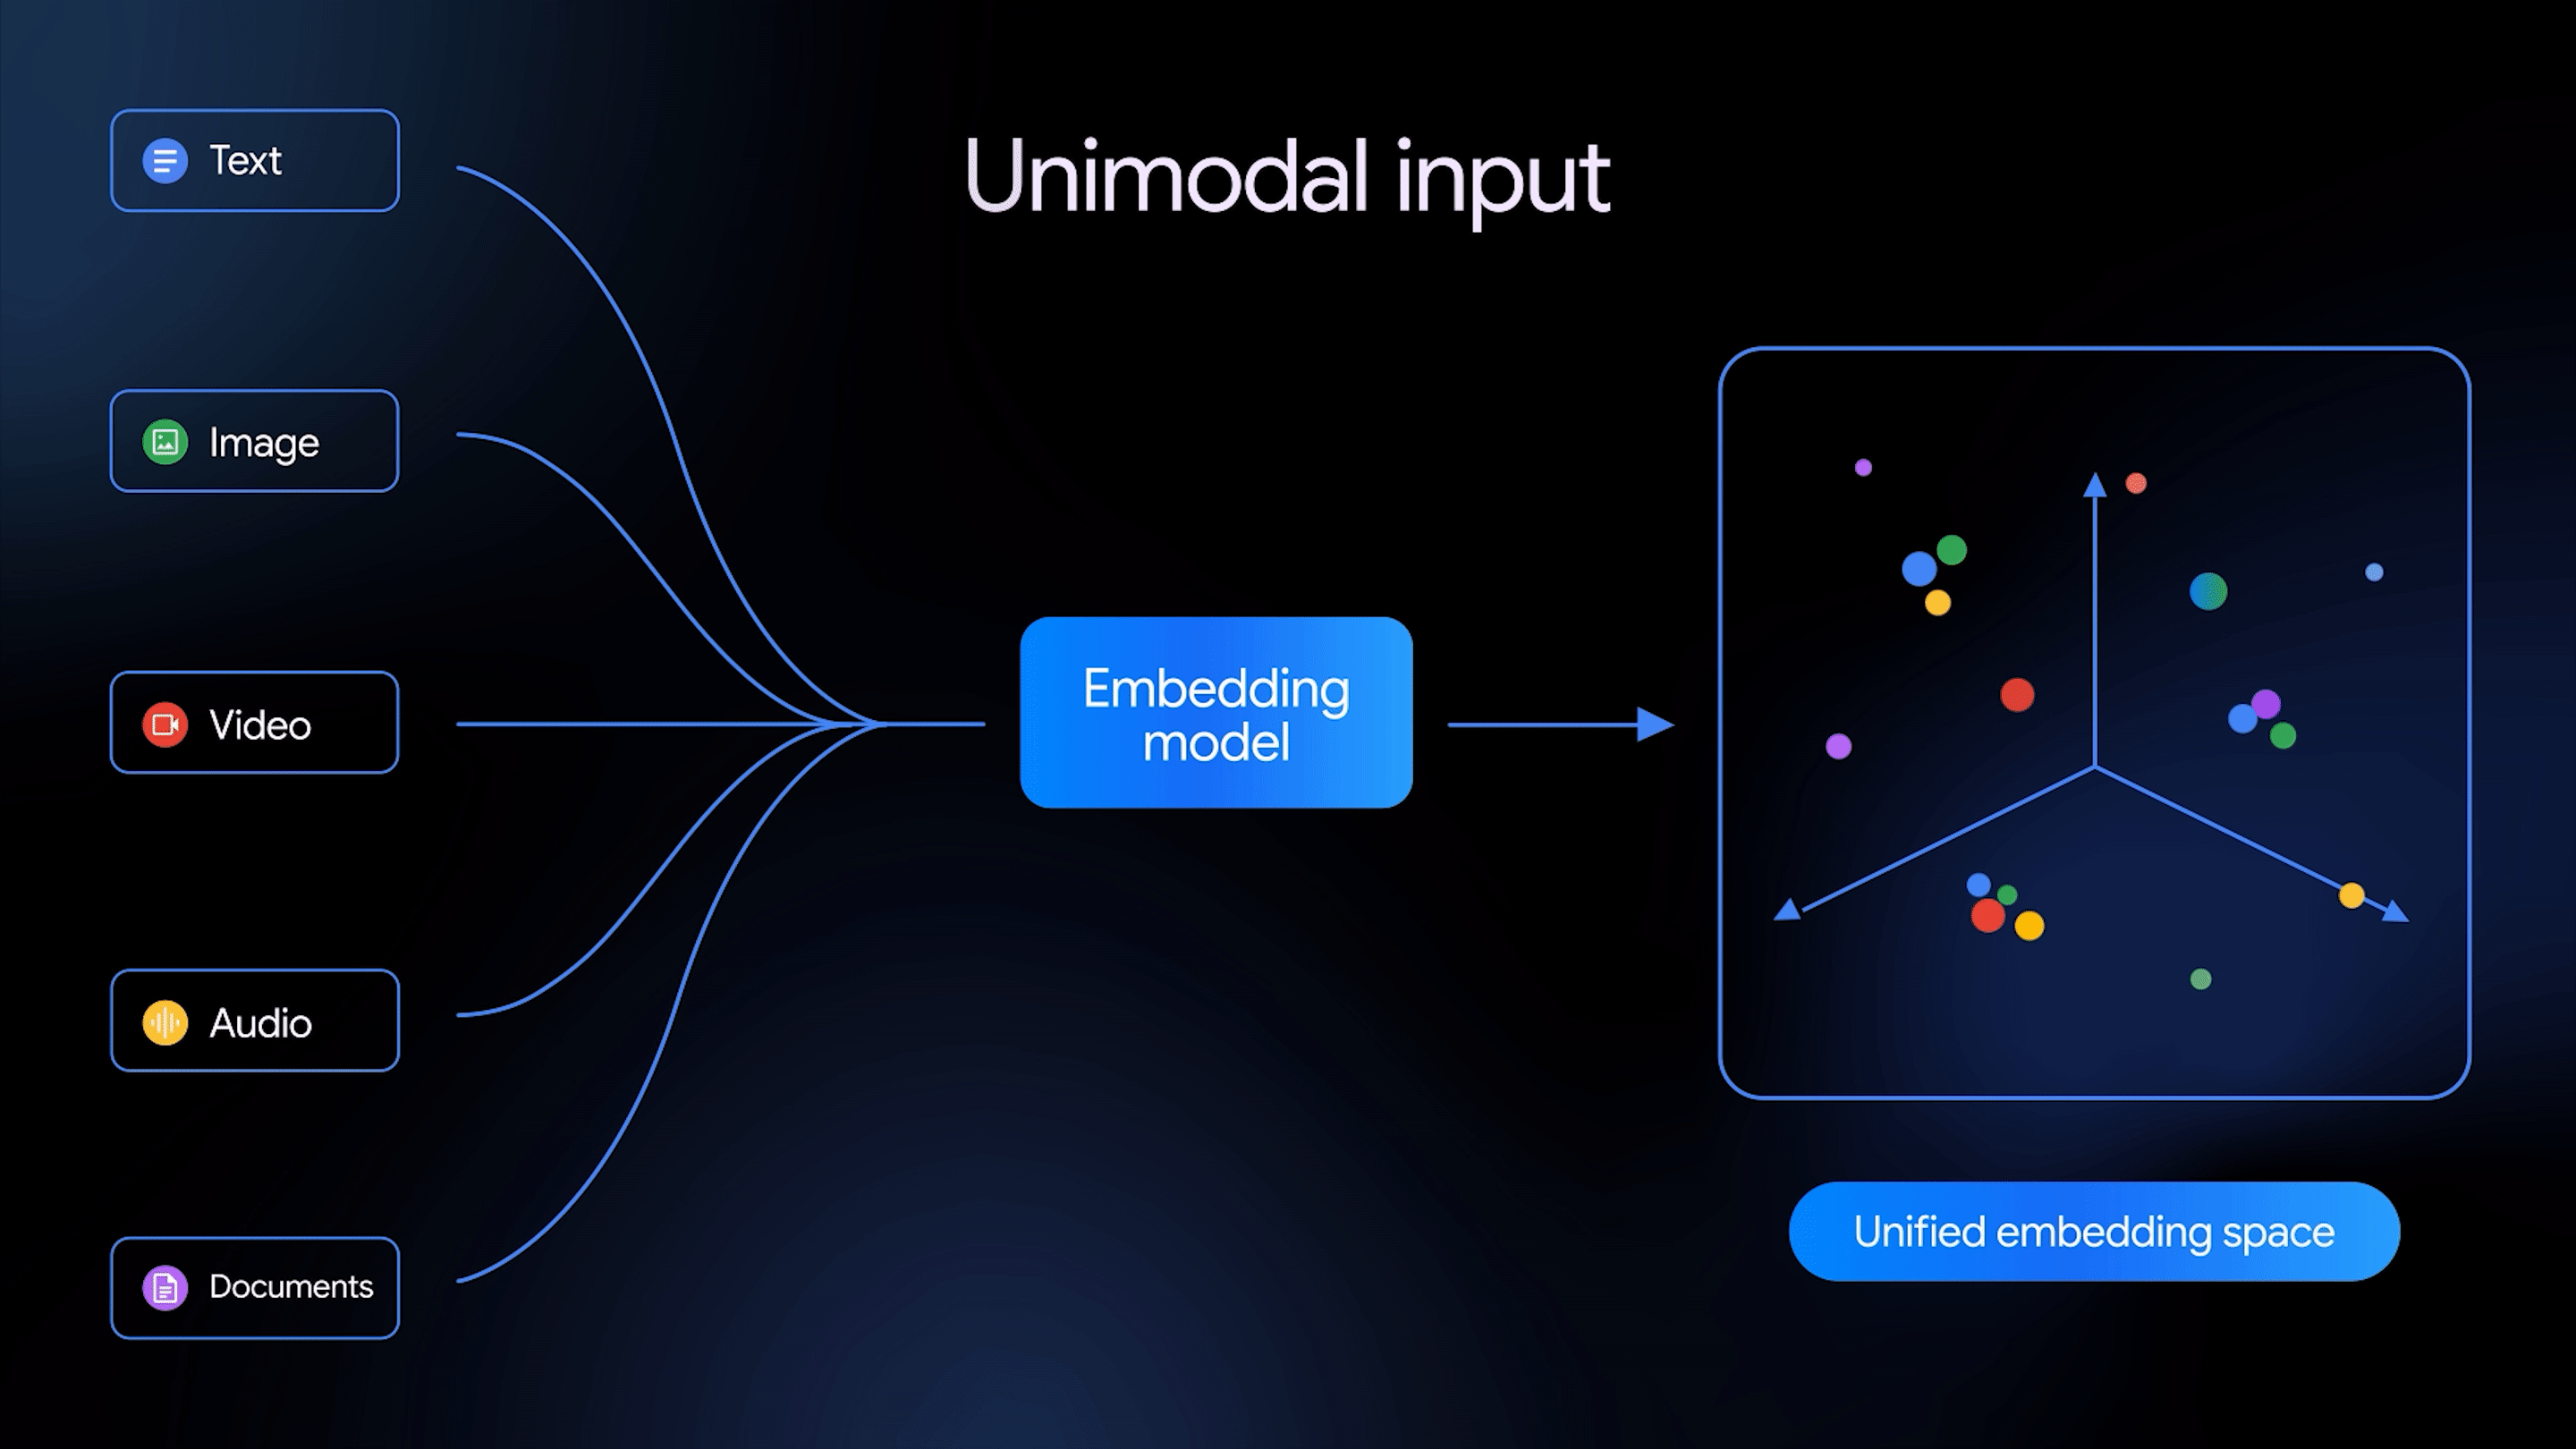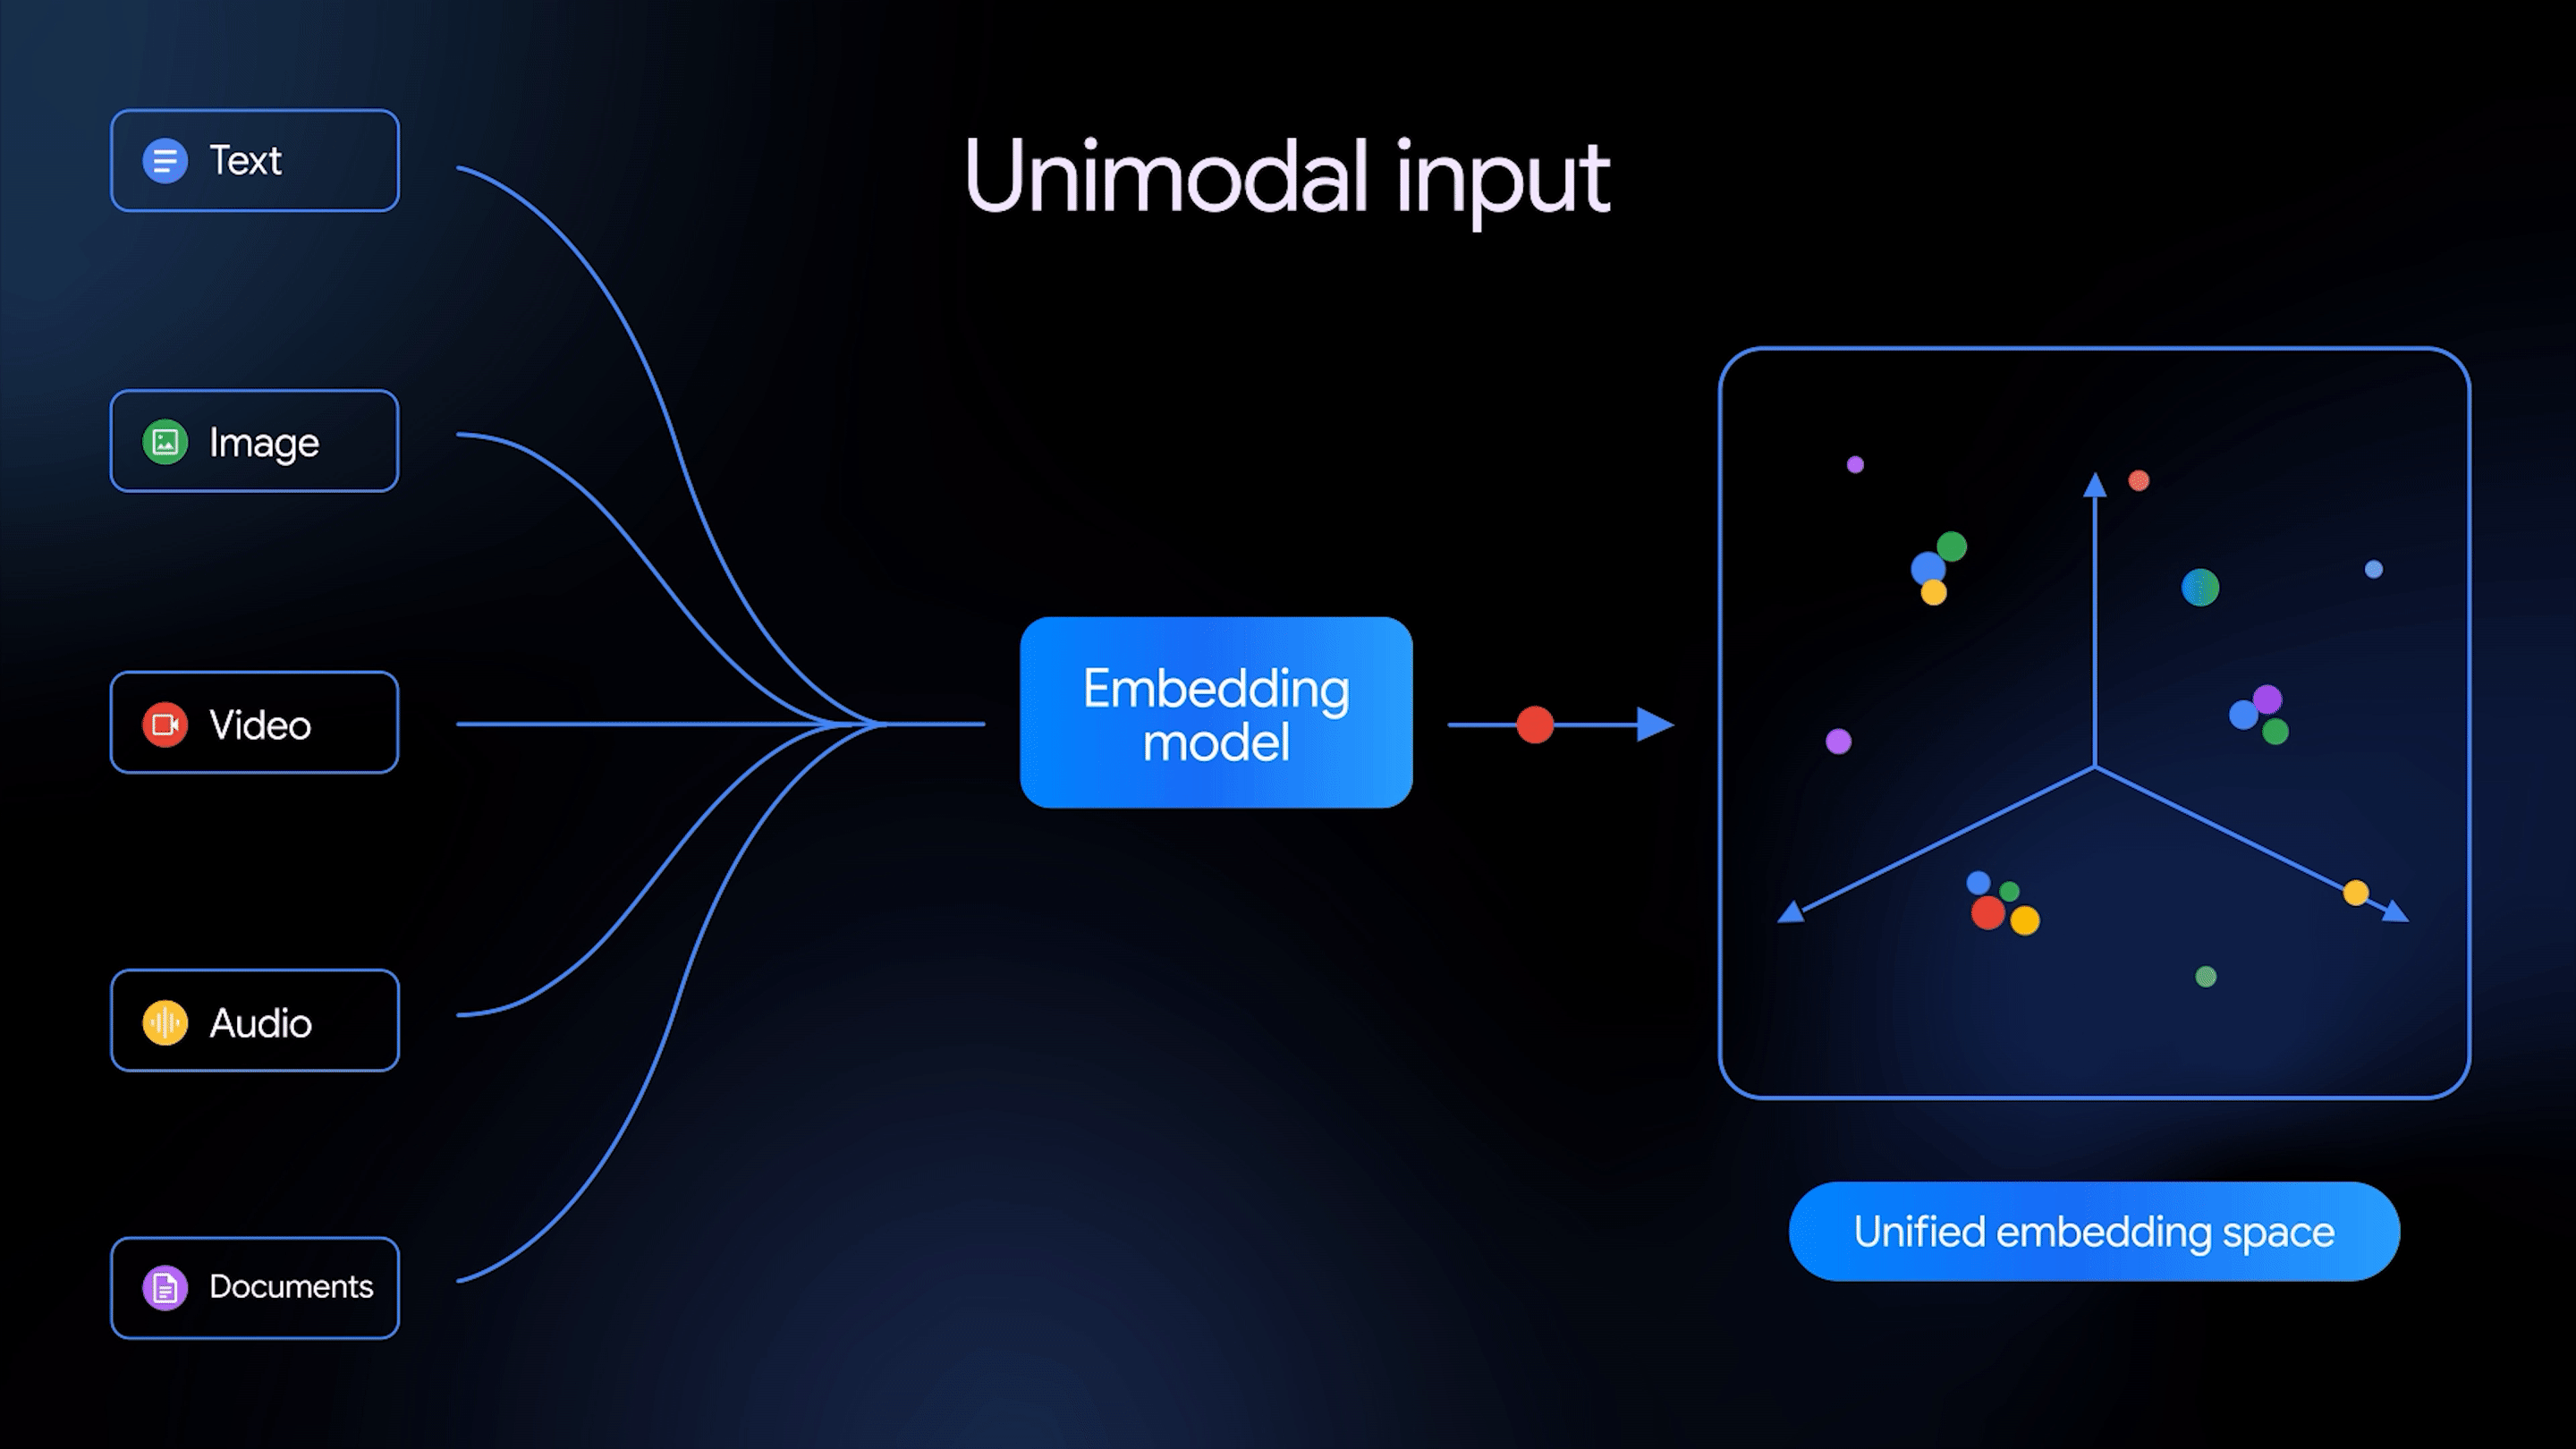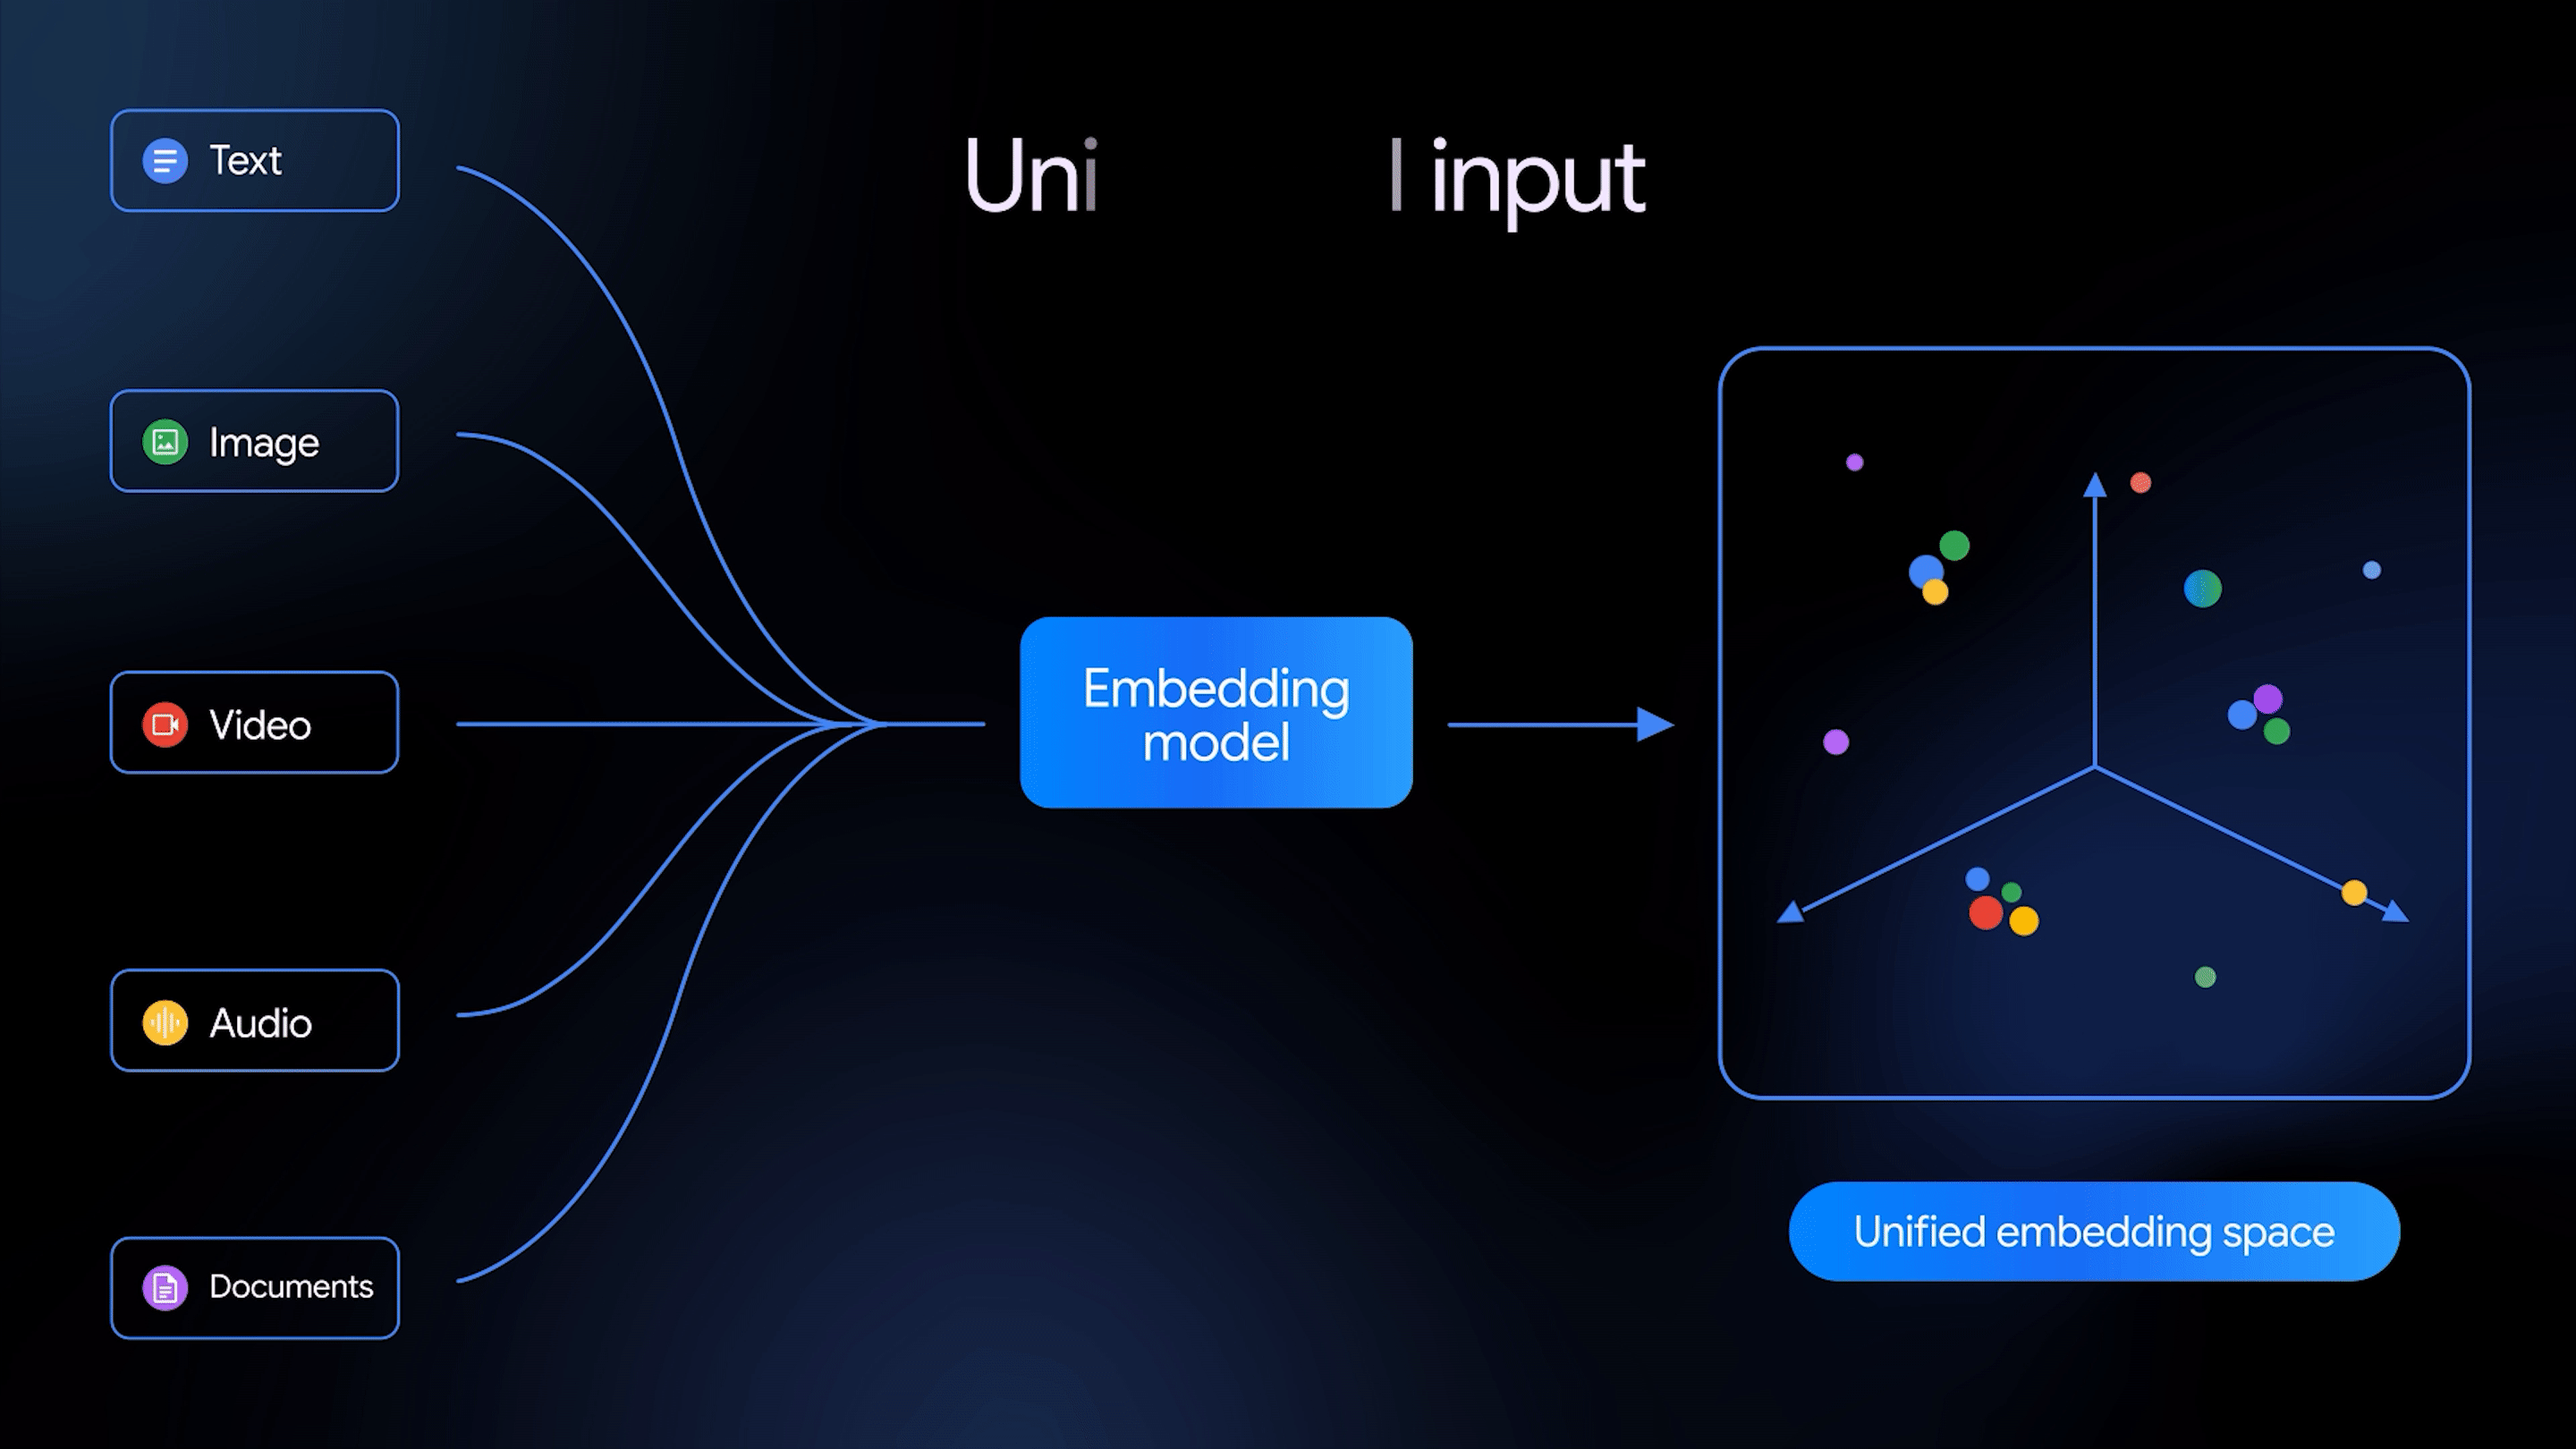
Cloud TPU上での長コンテキスト・マルチモーダル埋め込み推論をエンタープライズレベルの精度で実現Enterprise-Grade Precision for Long-Context Multimodal Embedding Inference on Cloud TPU

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約Google CloudがvLLMにTPUネイティブ対応を追加し、GKEで埋め込みパイプラインを弾力的にスケール可能に。Qwen3-Embedding-8Bなど15K超トークンの大規模コンテキストを処理でき、エンタープライズ向けRAGや検索基盤の構築に役立つ。

AI SUMMARYGoogle Cloud now supports TPU-native inference in vLLM via GKE, enabling scalable embedding pipelines that handle 15K+ token contexts with models such as Qwen3-Embedding-8B, benefiting enterprises building large-scale RAG and semantic search systems.

Enterprise-Grade Precision for Long-Context Multimodal Embedding Inference on Cloud TPU
8/23(日)Sun, Aug 231 entries
コミュニティCommunityLocal Models·Qiita LLM

RAG構築の壁を越える!ローカル×クラウドのハイブリッド構成とコスト戦略This article addresses three common RAG implementation challenges—poor…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約実務でRAGシステムを構築する際に直面する検索精度の低さ・クラウドコストの増大・機密データの外部送信リスクという三つの課題を、ローカルLLMとクラウドを組み合わせたハイブリッド構成で解決するアプローチを解説した記事。

AI SUMMARYThis article addresses three common RAG implementation challenges—poor retrieval accuracy, high cloud costs, and confidential data exposure—by proposing a hybrid architecture that combines local LLMs with cloud services to balance performance, cost, and privacy.

RAG構築の壁を越える!ローカル×クラウドのハイブリッド構成とコスト戦略
8/22(土)Sat, Aug 221 entries
コミュニティCommunityLocal Models·Qiita LLM

RAGとローカルLLMとは何か?AIエージェントに「外部の知識」をどう持たせるかThis article concludes a series on AI agent design by explaining RAG and local…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RAGとローカルLLMの仕組みを解説し、AIエージェントが学習データ外の知識を活用するための設計手法を紹介するシリーズ最終回。外部知識をエージェントに組み込む実践的なアプローチをまとめている。

AI SUMMARYThis article concludes a series on AI agent design by explaining RAG and local LLMs, focusing on how agents can incorporate external knowledge beyond their training data into practical workflows.

RAGとローカルLLMとは何か?AIエージェントに「外部の知識」をどう持たせるか
8/19(水)Wed, Aug 191 entries
公式OfficialGemini/Gemma·Google Cloud Blog

BoxがGemini Embeddings 2でマルチモーダルエンタープライズエージェントを実現How Box is unlocking multimodal enterprise agents with Gemini Embeddings 2

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約BoxはGemini Embeddings 2を活用し、テキストだけでなく画像や図面などを含むマルチモーダルなコンテンツ検索とエージェントAIを企業向けに提供。従来のRAGの限界を超え、企業データの活用範囲を大幅に拡大する。

AI SUMMARYBox is integrating Gemini Embeddings 2 to extend enterprise AI beyond text-only RAG, enabling multimodal agents that can reason over financial models, schematics, and other rich content stored in Box.

How Box is unlocking multimodal enterprise agents with Gemini Embeddings 2
8/18(火)Tue, Aug 181 entries
コミュニティCommunityLocal Models·Zenn AI

LLMでもRAGでもない「LDM(Large Database Model)」——データベースの中で学習するAIの仕組みLarge Database Model (LDM) is an AI model category that learns from relational…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LDM(Large Database Model)はリレーショナルDBの表データを学習対象とするAIモデルであり、自然言語を扱うLLMとは根本的に異なる概念である。IBMの実装が代表例として知られるが、「LDM」という呼称自体は業界用語として広く使われている。

AI SUMMARYLarge Database Model (LDM) is an AI model category that learns from relational database tabular data rather than natural language, making it fundamentally distinct from LLMs and RAG. The term is an industry coinage, with IBM's implementation being the most prominent example.

LLMでもRAGでもない「LDM(Large Database Model)」——データベースの中で学習するAIの仕組み
8/15(土)Sat, Aug 151 entries
コミュニティCommunityLocal Models·Zenn AI

LLM Wikiで自分のトリセツを作ってみたThe author explores LLM Wiki—a knowledge-design framework distinct from RAG and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMが回答の根拠とする知識を設計する仕組み「LLM Wiki」を使い、自分の価値観や好き嫌いをまとめた取り扱い説明書を実際に作成した体験を紹介。RAGとは異なるアプローチで個人の知識を構造化できる点が注目される。

AI SUMMARYThe author explores LLM Wiki—a knowledge-design framework distinct from RAG and Graph RAG—by building a personal "owner's manual" that captures their values and preferences, demonstrating a practical use case for structured self-knowledge with LLMs.

LLM Wikiで自分のトリセツを作ってみた
8/13(木)Thu, Aug 131 entries
コミュニティCommunityLocal Models·Zenn LLM

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話A new Udemy course on local LLM deployment using llama.cpp has launched,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約社内機密や顧客データをクラウドAIに渡せない課題を背景に、llama.cppを使ったローカルLLM構築をGPU・KVキャッシュ・RAGまで体系的に学べるUdemy講座が公開された。

AI SUMMARYA new Udemy course on local LLM deployment using llama.cpp has launched, addressing the common workplace challenge of handling confidential data that cannot be sent to cloud AI services, covering GPU usage, context management, KV cache, and RAG.

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話
8/9(日)Sun, Aug 91 entries
コミュニティCommunityLocal Models·Zenn AI

LLMの仕組みから逆算する、コンテキストエンジニアリングが効く理由Drawing on the mechanics of Transformer-based LLMs, the article derives four…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約TransformerのアーキテクチャをもとにLLMの内部動作を整理し、コンテキストが持つ4つの性質を言語化することで、プロンプト設計が出力品質に直結する理由を体系的に解説している。

AI SUMMARYDrawing on the mechanics of Transformer-based LLMs, the article derives four key properties of context that explain why deliberate context engineering directly determines output quality.

LLMの仕組みから逆算する、コンテキストエンジニアリングが効く理由
7/31(金)Fri, Jul 311 entries
コミュニティCommunityMCP·Qiita MCP

研究室AI基盤の構築(第4回:研究室ナレッジについて考えていたら自作してしまった件(後半))The fourth installment of a lab AI infrastructure series details the…

重要度 MediumMedium priority技術記事 · MCP / Toolingtechnical post · MCP / Tooling

AI要約研究室向けプロジェクト単位ナレッジ管理システムの後編として、自作MCPサーバーの実装詳細と運用方法を解説しており、研究室全体でAIを活用した知識共有を実現する具体的な手順が示されている。

AI SUMMARYThe fourth installment of a lab AI infrastructure series details the implementation of a custom MCP server for project-level knowledge management, showing how research labs can enable AI-assisted knowledge sharing across student projects.

研究室AI基盤の構築(第4回:研究室ナレッジについて考えていたら自作してしまった件(後半))
7/28(火)Tue, Jul 282 entries
コミュニティCommunityLocal Models·Zenn LLM

LLMでテキストから知識グラフを自動抽出する手法を動かしてみたThe author implements and evaluates an LLM-based pipeline for automatically…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMを活用してテキストから知識グラフを自動生成する手法を実際に検証し、その精度や実装上の課題を明らかにした記事。RAGや情報整理への応用可能性を示す点で注目に値する。

AI SUMMARYThe author implements and evaluates an LLM-based pipeline for automatically extracting knowledge graphs from text, demonstrating practical feasibility and surfacing key challenges relevant to RAG and structured knowledge applications.

LLMでテキストから知識グラフを自動抽出する手法を動かしてみた
公式OfficialAgent Frameworks·AWS Machine Learning Blog

RAGを超えて: AWSエンタープライズAIにおけるタスク認識型知識圧縮Beyond RAG: Task-aware knowledge compression for enterprise AI on AWS

重要度 MediumMedium priority技術記事 · Agent Frameworkstechnical post · Agent Frameworks

AI要約数百ドキュメントにわたる分析タスクでRAGの限界を克服するため、AWSはタスク認識型知識圧縮(TAKC)を活用し、知識ベースをタスク特化表現に事前圧縮して多段階キャッシュで効率化する手法を紹介。

AI SUMMARYAWS introduces task-aware knowledge compression (TAKC) to overcome RAG limitations on large-scale analytical tasks, pre-compressing knowledge bases into task-specific representations with multi-fidelity caching on AWS.

Beyond RAG: Task-aware knowledge compression for enterprise AI on AWS
7/24(金)Fri, Jul 242 entries
コミュニティCommunityClaude Code·Zenn Claude

LLM-as-judgeを疑え — 忠実性スコア3.20の犯人は、答案ではなく採点者だったAn investigation into low faithfulness scores in RAG evaluation revealed the…

重要度 MediumMedium priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約RAG評価でLLM-as-judgeの忠実性スコアが低迷した原因を追跡すると、回答品質ではなく評価モデル自体のバイアスや採点ミスが問題だったことが判明した。評価パイプラインの信頼性を検証する重要性を示す実践的な知見。

AI SUMMARYAn investigation into low faithfulness scores in RAG evaluation revealed the culprit was the judge LLM itself, not the answers being evaluated. This highlights why validating your evaluation pipeline is as critical as validating the model under test.

LLM-as-judgeを疑え — 忠実性スコア3.20の犯人は、答案ではなく採点者だった
公式OfficialAgent Frameworks·AWS Machine Learning Blog

Amazon Bedrock マネージドナレッジベースにおける「Agentic Retrieval」機能Agentic retrieval for Amazon Bedrock Managed Knowledge Base

重要度 MediumMedium priority技術記事 · Agent Frameworkstechnical post · Agent Frameworks

AI要約Amazon BedrockのマネージドナレッジベースにAgentic Retrieval機能が追加され、エージェントが複雑なクエリを自律的に分解・検索できるようになった。これによりRAGの精度と柔軟性が大幅に向上する。

AI SUMMARYAmazon Bedrock Managed Knowledge Base now supports agentic retrieval, enabling agents to autonomously decompose and execute complex queries for more accurate and flexible RAG workflows.

Agentic retrieval for Amazon Bedrock Managed Knowledge Base
7/21(火)Tue, Jul 211 entries
公式OfficialAgent Frameworks·AWS Machine Learning Blog

CouchbaseがAmazon BedrockでCapella iQ向けマルチモデルAIアーキテクチャを構築した方法How Couchbase built a multi-model AI architecture for Capella iQ with Amazon Bedrock

重要度 MediumMedium priority技術記事 · Agent Frameworkstechnical post · Agent Frameworks

AI要約CouchbaseはAmazon Bedrockを活用し、Capella iQにマルチモデルAI構成を実装することで、用途に応じた最適なモデル選択と高精度なデータベース支援を実現した。

AI SUMMARYCouchbase details how it leveraged Amazon Bedrock to build a multi-model AI architecture for Capella iQ, enabling dynamic model routing to improve accuracy and cost-efficiency for database assistance.

How Couchbase built a multi-model AI architecture for Capella iQ with Amazon Bedrock
7/19(日)Sun, Jul 191 entries
コミュニティCommunityLocal Models·Zenn LLM

RAGFlowが日本語を中国語に変えてしまうので、LlamaIndexで日英RAGを自作した話Faced with RAGFlow incorrectly converting Japanese text to Chinese, the author…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RAGFlowが日本語テキストを誤って中国語に変換してしまう不具合を受け、著者がLlamaIndexを使って日本語・英語対応のRAGシステムをスクラッチで構築した経緯と実装方法を紹介している。

AI SUMMARYFaced with RAGFlow incorrectly converting Japanese text to Chinese, the author built a custom bilingual Japanese-English RAG pipeline from scratch using LlamaIndex, sharing the implementation details and lessons learned.

RAGFlowが日本語を中国語に変えてしまうので、LlamaIndexで日英RAGを自作した話
7/17(金)Fri, Jul 171 entries
公式OfficialAgent Frameworks·AWS Machine Learning Blog

Amazon Bedrock マネージドナレッジベースでエージェント向けエンタープライズ検索を構築するBuild enterprise search for agents with Amazon Bedrock Managed Knowledge Base

重要度 MediumMedium priority技術記事 · Agent Frameworkstechnical post · Agent Frameworks

AI要約Amazon Bedrock のマネージドナレッジベースを活用し、AIエージェントが社内文書を横断検索できるエンタープライズ検索基盤の構築方法を解説。RAGパターンの実装を簡素化し、エージェントの回答精度向上に貢献する。

AI SUMMARYThis article explains how to use Amazon Bedrock Managed Knowledge Base to build enterprise search capabilities for AI agents, simplifying RAG-based retrieval over internal documents and improving agent response accuracy.

7/15(水)Wed, Jul 151 entries
コミュニティCommunityMCP·Zenn MCP

ナレッジベースRAGプラグイン市場の開発、複数Reactインスタンスとマイクロフロントエンド(4)The fourth installment of a series on building a RAG plugin marketplace…

重要度 MediumMedium priority技術記事 · MCP / Toolingtechnical post · MCP / Tooling

AI要約RAGプラグイン市場の開発シリーズ第4回として、複数のReactインスタンス共存とマイクロフロントエンド構成の課題と解決策を解説している。

AI SUMMARYThe fourth installment of a series on building a RAG plugin marketplace explores how to manage multiple React instances and architect a scalable micro-frontend solution.

7/14(火)Tue, Jul 141 entries
コミュニティCommunityMCP·Zenn MCP

Blumeで作る、LLMに読ませるドキュメントの3つの出口This article explains how to use Blume as an MCP tool to export LLM-readable…

重要度 MediumMedium priority技術記事 · MCP / Toolingtechnical post · MCP / Tooling

AI要約BlumeをMCPツールとして活用し、LLMが参照しやすいドキュメントをMarkdown・JSON・埋め込みベクターの3形式で出力する方法を解説した記事。ドキュメント設計の観点からLLM連携の実践的なアプローチを示している。

AI SUMMARYThis article explains how to use Blume as an MCP tool to export LLM-readable documents in three formats—Markdown, JSON, and embedded vectors—offering practical guidance for structuring documentation in AI-integrated workflows.

7/11(土)Sat, Jul 113 entries
論文PaperPapers/Benchmarks·arXiv cs.AI

VectorizationLLM: ベクトル化に基づくスマートAIアシスタントVectorizationLLM: Smart Vectorization Based AI Assistant

重要度 MediumMedium priority論文/研究 · Papers / Benchmarkspaper/research · Papers / Benchmarks

AI要約本論文はベクトル化技術を活用したLLMベースのAIアシスタント手法を提案し、効率的な情報検索と応答生成の改善を目指している。

AI SUMMARYThis paper proposes VectorizationLLM, an AI assistant leveraging smart vectorization to enhance retrieval and response quality in large language model systems.

論文PaperPapers/Benchmarks·arXiv cs.AI

ストレートスルー引受におけるエージェント型AIと検索拡張モデルAgentic AI and Retrieval-Augmented Models in Straight-Through Underwriting

重要度 MediumMedium priority論文/研究 · Papers / Benchmarkspaper/research · Papers / Benchmarks

AI要約本論文は、保険引受の完全自動化(ストレートスルー処理)にエージェント型AIとRAGを組み合わせる手法を提案し、意思決定の精度と説明可能性の向上を示した。

AI SUMMARYThis paper proposes combining agentic AI with retrieval-augmented generation for fully automated insurance underwriting, demonstrating improved decision accuracy and explainability in straight-through processing.

コミュニティCommunityClaude Code·Zenn Claude

孫のためにAI「侍読」を作った ― ローカルLLMのジレンマをClaudeで解いた話A developer built an AI reading companion called 'Jidoku' for their grandchild,…

重要度 MediumMedium priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約孫の読書支援用AIアシスタント「侍読」を構築する過程で、ローカルLLMの限界に直面し、最終的にClaudeとRAGを組み合わせて実用的なシステムを実現した体験談。プライバシーと性能のトレードオフをどう解決するかを具体的に示している。

AI SUMMARYA developer built an AI reading companion called 'Jidoku' for their grandchild, encountered the limitations of local LLMs around privacy vs. quality, and resolved the dilemma by integrating Claude with a RAG pipeline.

7/10(金)Fri, Jul 101 entries
コミュニティCommunityClaude Code·Zenn Claude

Corpus2Skill深掘り — RAGを捨てて『ナビゲート』する設計は何を変えるのかCorpus2Skill replaces retrieval-augmented generation with a 'navigate' paradigm…

重要度 MediumMedium priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約Corpus2Skillはドキュメントを都度検索するRAGの代わりに、コーパスからスキルを事前抽出してモデルに内在化させる設計を採用しており、レイテンシ削減と一貫性向上を実現する点で注目される。

AI SUMMARYCorpus2Skill replaces retrieval-augmented generation with a 'navigate' paradigm that pre-extracts skills from a corpus and internalizes them into the model, reducing latency and improving response consistency.

6/18(木)Thu, Jun 181 entries
公式OfficialNews/Policy·AWS News Blog

Amazon Bedrock マネージドナレッジベース登場:高速・高精度なエンタープライズAIアプリを実現Introducing Amazon Bedrock Managed Knowledge Base for faster, more accurate enterprise AI applications

重要度 InfoInformational深掘り候補 · 技術記事 · Industry & PolicyDeep-dive candidate · technical post · Industry & Policy

AI要約AWSが完全マネージド型のAmazon Bedrock Managed Knowledge Baseを発表。ネイティブデータコネクタとSmart Parsingで多様な形式のデータを自動処理し、エンタープライズ向けRAGパイプラインの構築を大幅に簡素化する。

AI SUMMARYAWS launched the fully managed Amazon Bedrock Managed Knowledge Base, using native data connectors and Smart Parsing to auto-prepare multi-format data and greatly simplify building enterprise RAG pipelines.

5/19(火)Tue, May 191 entries
公式OfficialLocal Models·Hugging Face Blog

Ettin Rerankerファミリーの紹介Introducing the Ettin Reranker Family

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Hugging FaceがローカルLLM向けの新しいリランカーモデル群「Ettin Reranker」を公開し、検索精度の向上と効率的な再順位付けを実現する。オープンモデルとして提供され、RAGパイプラインの品質改善に活用できる。

AI SUMMARYHugging Face released the Ettin Reranker model family, a suite of open reranking models designed to improve retrieval quality in RAG pipelines by reordering candidate documents more accurately and efficiently.

3/20(金)Fri, Mar 201 entries
公式OfficialAgent Frameworks·Semantic Kernel Releases

Microsoft Semantic Kernel、VectorData .NET 10.1.0をリリースSemantic Kernel vectordata-dotnet-10.1.0

重要度 MediumMedium priority公式リリース · Agent Frameworksofficial release · Agent Frameworks

AI要約MicrosoftがSemantic KernelのVectorData .NETパッケージ10.1.0を公開した。ベクトルストア抽象化の安定化やOpenAI 2.9.1、Azure.AI.OpenAIなど依存関係の更新を含み、.NET向けRAG構築基盤を強化する内容となっている。

AI SUMMARYMicrosoft released VectorData .NET 10.1.0 for Semantic Kernel, bumping dependencies such as OpenAI to 2.9.1 and Azure.AI.OpenAI while stabilizing vector store abstractions, reinforcing the foundation for building RAG apps on .NET.

vectordata-dotnet-10.1.0