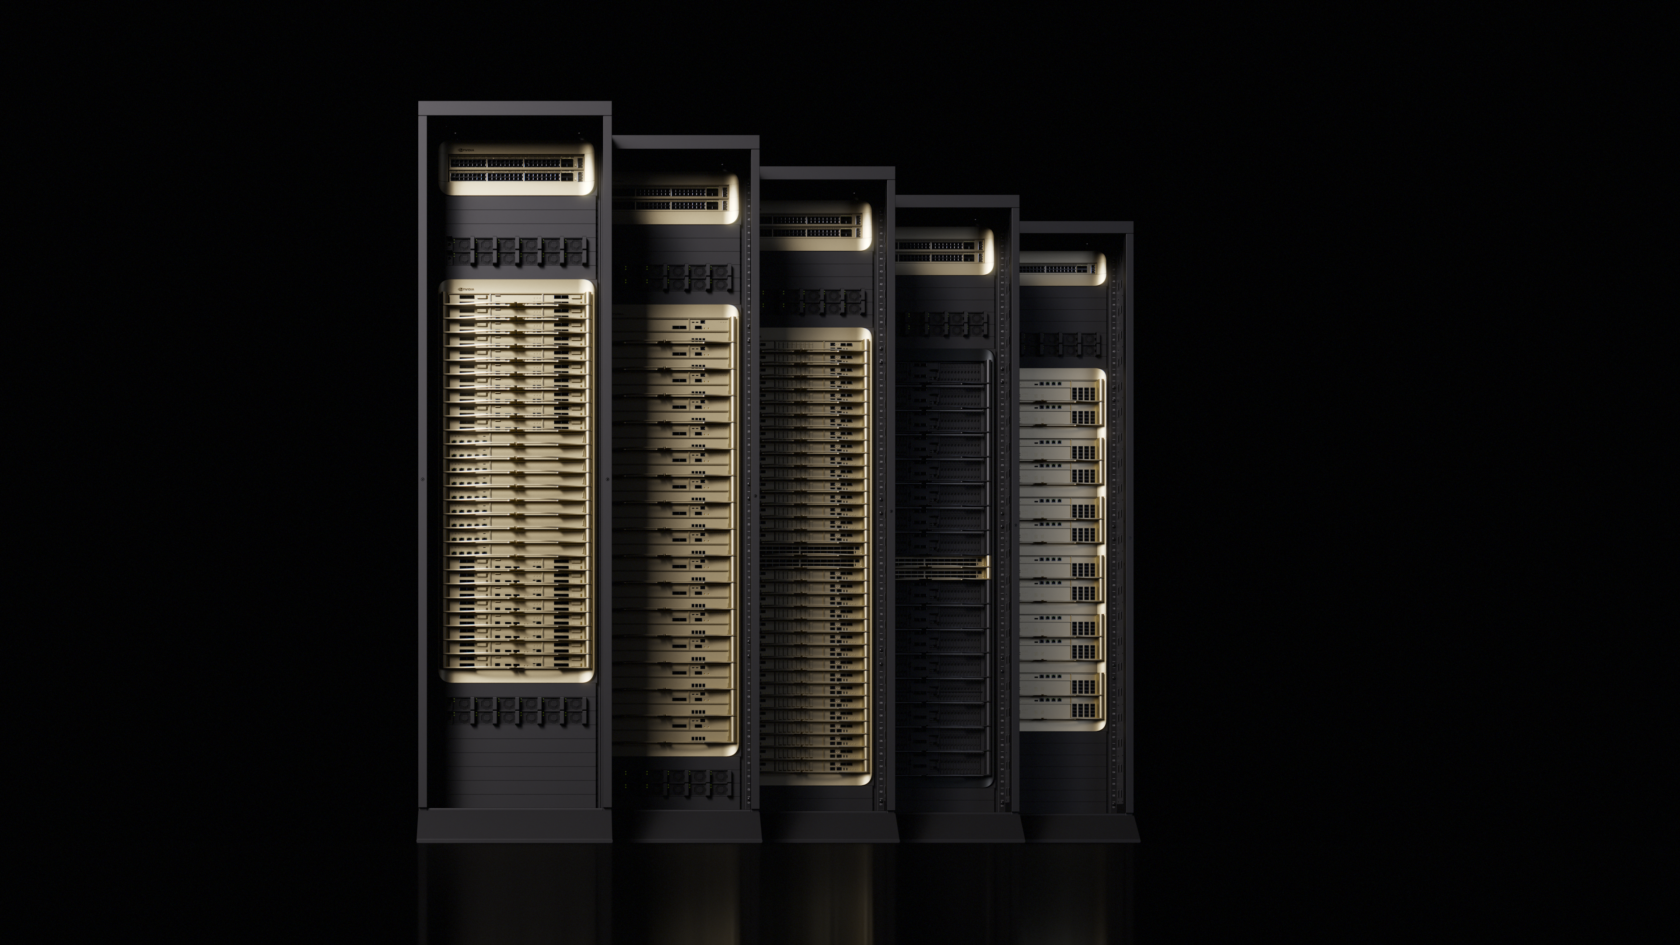
Groq 3 LPX量産開始に合わせ、NVIDIAがエージェント向けVera Rubin推論を拡張With Groq 3 LPX in Full Production, NVIDIA Extends Vera Rubin Inference for Agents
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
- NVIDIAはVera Rubin NVL72をエージェント型AIシステム向けに拡張し、高速トークン生成を実現する。
- AIファクトリー全体の各レイヤーが連携することで次世代推論基盤を構築する狙いだ。
NVIDIA is extending its Vera Rubin NVL72 platform with fast token generation optimized for agentic AI workloads, emphasizing full-stack integration across chips, networks, and systems as the foundation for next-generation inference.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (blogs.nvidia.com) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (blogs.nvidia.com).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
Vera Rubin拡張
NVIDIAは、Vera Rubin NVL72をエージェント型AIシステム向けに拡張し、高速なトークン生成に対応すると説明している。Groq 3 LPXの量産開始に合わせて示された動きで、次世代のAI推論を単一要素ではなく、AIファクトリー全体の連携で捉える点が重要となる。
全レイヤー連携
同社によれば、次の時代のAI推論は、単独の画期的なチップ、ネットワーク、システムだけで定義されるものではない。チップからネットワーク、システムまで、AIファクトリーを構成する各レイヤーが協調して動作することを基盤とする。
Vera Rubin NVL72への高速トークン生成の追加は、この考え方をエージェント型AIのワークロードに適用するものとされる。個別技術だけでなく、推論基盤を構成する層全体の統合を重視した拡張だ。
Vera Rubin NVL72
NVIDIA is extending Vera Rubin NVL72 for agentic AI systems, adding fast token generation for agentic workloads. The announcement presents this capability as part of the foundation for next-generation AI inference rather than as a change centered on a single component.
The item’s title places the expansion alongside the start of Groq 3 LPX mass production. No further technical details about Groq 3 LPX or its relationship to Vera Rubin NVL72 are provided in the source excerpt.
Fast token generation
The stated technical change is fast token generation optimized for agentic systems. The source does not provide performance figures, configuration details, pricing, or information about supported platforms.
Every layer works together
According to NVIDIA, the next era of AI inference will not be defined by one breakthrough chip, network, or system. Instead, the company emphasizes coordination across every layer of the AI factory.
The announcement therefore frames Vera Rubin NVL72 as a full-stack inference platform in which chips, networks, and systems work together to support agentic AI workloads.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPokoVera Rubin NVL72をエージェント型AI向けに拡張するって、何が変わるの?What changes when Vera Rubin NVL72 is extended for agentic AI?
- TECHガイドTECH Guide記事によれば、エージェント型AI向けに高速なトークン生成を加えるそうじゃ。簡単に言うと、AIが回答を素早く組み立てるための拡張じゃな。According to the article, it adds fast token generation for agentic AI. Put simply, it is designed to help AI build responses quickly.
- ポコPokoへえ、それって何がうれしいの?チップだけ速くすればいいわけじゃないの?Oh, nice! Why does that matter? Wouldn’t making the chip faster be enough?
- TECHガイドTECH Guide記事は、単一のチップではなく、チップ・ネットワーク・システムの各層が連携することが重要だとしておる。そこが次世代推論基盤の土台になるという考えじゃよ。The article says no single chip is enough; chips, networks, and systems must work together. That full-stack integration is presented as the foundation for next-generation inference.
- ポコPokoつまり、AIの返答を速くするには、部品ひとつより全体の連携が大事ってことだね。So faster AI responses depend on the whole setup working together, not just one component.
- TECHガイドTECH Guideその理解でよいぞ。Vera Rubin NVL72の拡張で、エージェント型AI向けの高速生成と全体連携をどう形にするかが見どころじゃな。Exactly. The key thing to watch is how the Vera Rubin NVL72 extension turns fast generation and full-stack coordination for agentic AI into practice.





