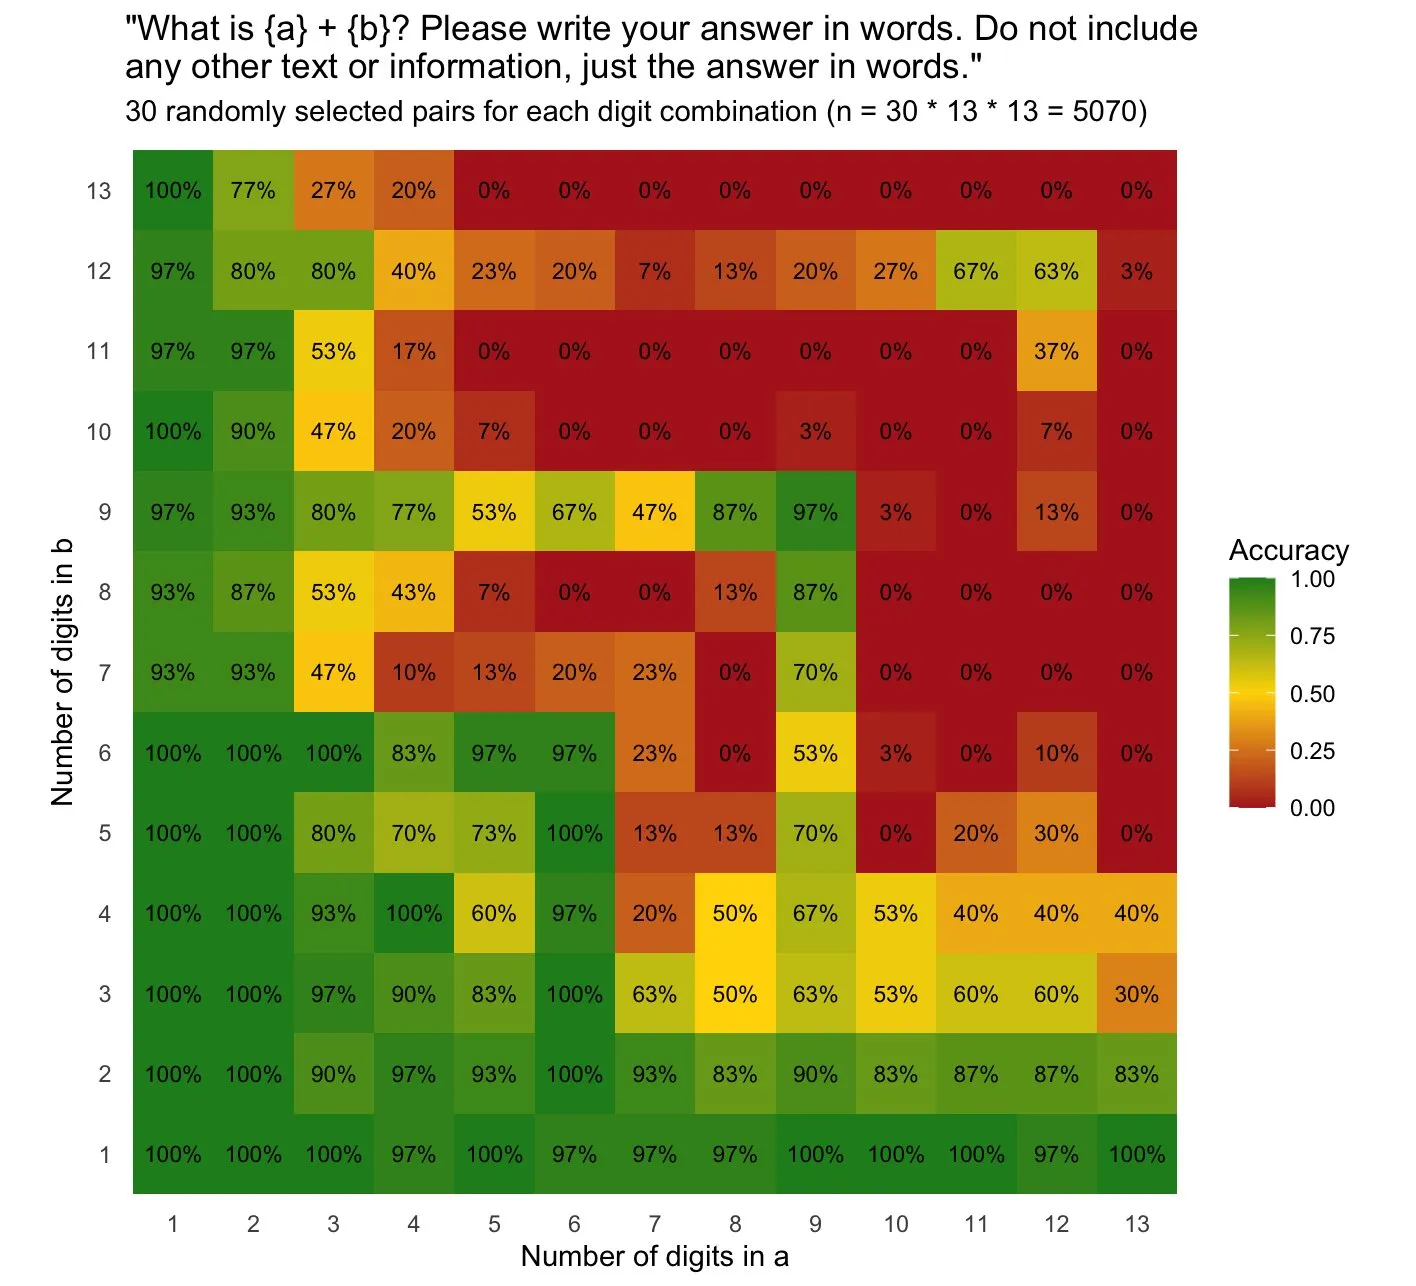
Qwen3.8 27Bによる足し算の文章回答Qwen3.8 27B addition in words
匿名の公開いいねです。記事の保存・お気に入りではなく、Featured、Top 3、重要度、掲載順位には影響しません。仕組みとプライバシーAnonymous public likes are reactions, not saved articles or bookmarks. They do not affect Featured, Top 3, importance, or listing order.How it works and privacy
- Qwen3.8 27Bは、大きくなる数の足し算を行い、答えを数字ではなく言葉で返す試験をDGX Spark上で実施した。
- 管理されたローカル環境でGPT-4oとの計算能力を比較できる。
- Qwen3.8 27B was tested on increasingly large additions while spelling out each result, using a Q4_K_M GGUF on DGX Spark.
- This enables a controlled local comparison with GPT-4o.
本ページの本文と要約は AI による自動生成です。日本語版と英語版は言語ごとに独立して生成されるため、表現や詳しさが異なる場合があります。正確性は元記事 (simonwillison.net) をご確認ください。The body and summaries are AI-generated independently for each language, so wording and detail may differ. Verify accuracy at the original source (simonwillison.net).
要約と収集メタデータに基づく AI 解説。元記事全文の転載・翻訳ではありません。AI explainer based on the summaries and collected metadata, not a copy or translation of the full source article.
足し算の文章回答
Qwen3.8 27Bに、次第に大きくなる数の足し算を行わせ、答えを数字ではなく言葉で返させる試験が実施された。計算だけでなく、求めた結果を文章として表現するところまでを一つの課題として扱っている。
GPT-4oとの比較
この試験のもとになったのは、Colin Frasier氏が2年以上前にGPT-4oを使って行った実験だ。GPT-4oに「合計を計算し、答えを言葉で返す」よう求め、数が大きくなるにつれて結果がどう変わるかを調べた。共有された結果には多数の計算間違いがあり、電卓を使って処理したものではないとの見方が示されている。
DGX Sparkで実行
同じ実験を管理されたローカル環境で再現するため、DGX Sparkが使われた。元の結果を示す画像をCodex Remoteのセッションへ貼り付け、GPT-6 Astraを通じてQwen3.8-27B-Q4_K_M.ggufに同一の実験を実行させている。これにより、Qwen3.8 27BとGPT-4oの計算能力をローカル環境で比較できる形とした。
30回の試行
実行では、各組み合わせについて30回ずつ試行した。まずreasoningを無効にした状態で結果を取得し、その後、reasoningを有効にして再度実験した。比較では、数の大きさだけでなく、推論設定の違いも分けて扱われている。
Addition in words
Qwen3.8 27B was tested on addition problems involving increasingly large numbers, with each result returned in words rather than digits. Running the test on local hardware matters because it provides a fully controlled environment for comparing the model’s calculation performance with GPT-4o.
Increasingly large numbers
The experiment followed an earlier test by Colin Frasier, posted on Bluesky more than two years ago. That test used GPT-4o to examine how well it could “compute the sum but return the answer in words” as the numbers became larger.
Frasier shared a chart showing the results. The author says they are confident GPT-4o did not use a calculator, noting that the model produced many incorrect calculations. Those results inspired a repeat of the experiment using local hardware.
Fully controlled environment
The new test was conducted on a DGX Spark. Frasier’s chart image was pasted into a Codex Remote session using GPT-6 Astra, which was then instructed to run the same experiment with Qwen3.8-27B-Q4_K_M.gguf.
This setup placed the Qwen3.8 27B test in a controlled local environment while preserving the core task from the GPT-4o experiment: calculate sums across increasingly large values and spell out the answers. The use of the Q4_K_M GGUF on DGX Spark provides the basis for the local comparison.
Reasoning enabled
The first Qwen3.8 27B run used 30 attempts for each combination with reasoning disabled. The experiment was then run again with reasoning enabled.
The source does not provide numerical results in the text, so no conclusion can be drawn here about accuracy or whether enabling reasoning changed performance. The stated comparison is between the two reasoning settings and the earlier GPT-4o experiment under the same addition-in-words task.
ポコとTECHガイドPoko & TECH Guide
ポコと当サイトのTECHガイドが、記事の要約と収集した情報から読みどころを語るAI生成の対話です。Poko and TECH Dashboard's own TECH Guide discuss the article's highlights in an AI-generated conversation based on its summary and collected source details.
- ポコPoko大きな数を足すだけじゃなく、答えを言葉で返させたのはなんで?Why make it spell out the answer instead of just adding the large numbers?
- TECHガイドTECH Guideこの記事では、数が大きくなる足し算を正しく計算し、数字ではなく言葉で答えられるかを試しているよ。The test checks whether it can handle increasingly large additions and return each result in words rather than digits.
- ポコPokoじゃあ、モデルの計算力を比べたい人が、同じ条件で確かめやすくなるのかな?So does this help people compare the models’ calculation ability under the same conditions?
- TECHガイドTECH Guideうん。DGX Sparkのローカル環境でQwen3.8 27Bを動かし、GPT-4oとの管理された比較ができる形だね。Yes. It runs Qwen3.8 27B locally on DGX Spark, allowing a controlled comparison with GPT-4o.
- ポコPokoなるほど。足し算と言葉での回答を、ローカルで繰り返し比べたんだね。Got it. They repeatedly tested both addition and spelling out the answers in a local setup.
- TECHガイドTECH Guideそうだね。ただし、Q4_K_M GGUFを使い、各組み合わせ30回、推論の無効時と有効時に試した結果だよ。Right. Keep in mind that this used a Q4_K_M GGUF, with 30 attempts per combination and separate runs with reasoning disabled and enabled.



