Home›Tags›#llm›Page 3

Tag timeline

#llmpage 3/10

同じキーワードで束ねられた更新の続きです。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total273#llm の全掲載記事All listed entries tagged #llm
Showing30このページの件数Entries on this page
Page3/10静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 3/10 · 273 total

8/12(水)Wed, Aug 121 entries
公式OfficialGemini/Gemma·Google Cloud Blog

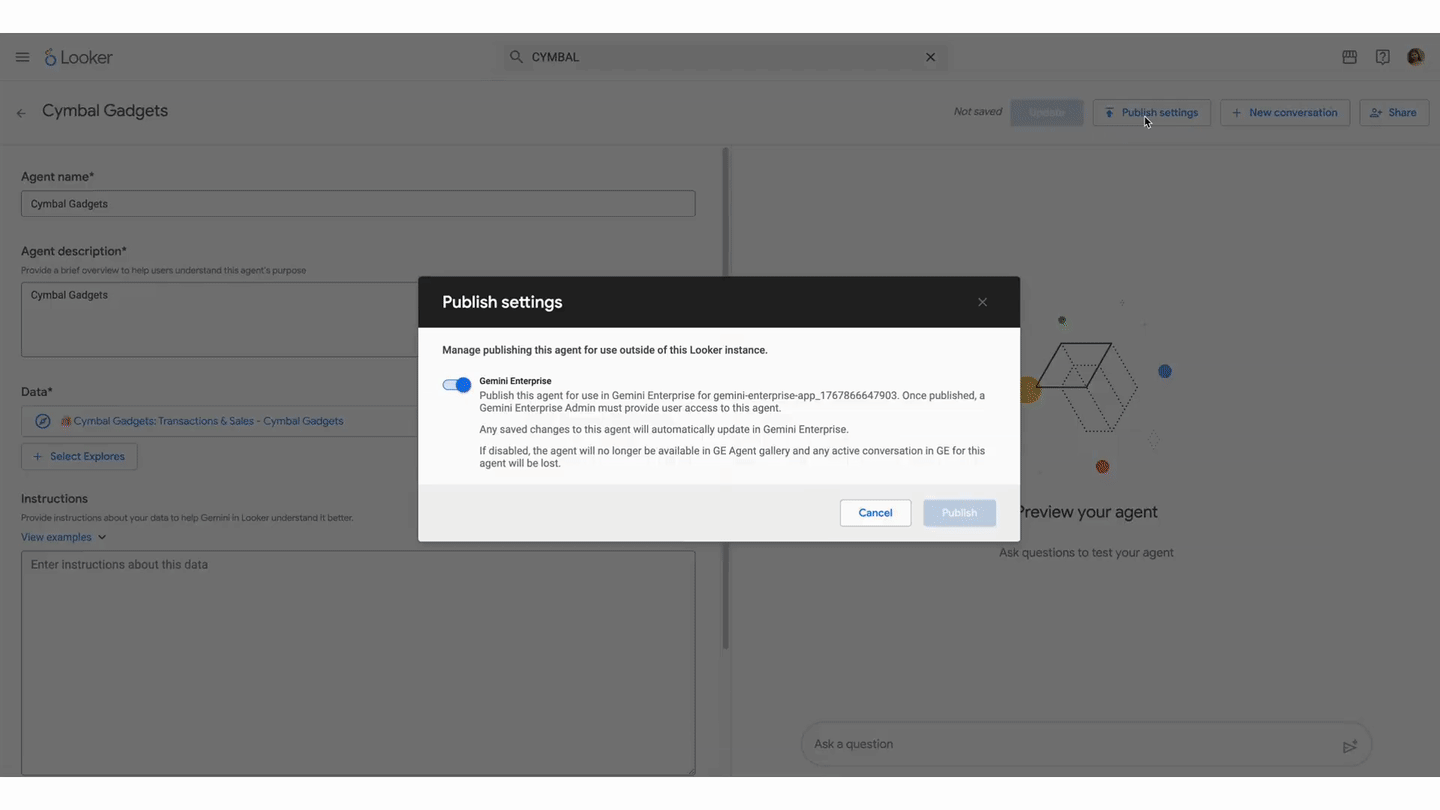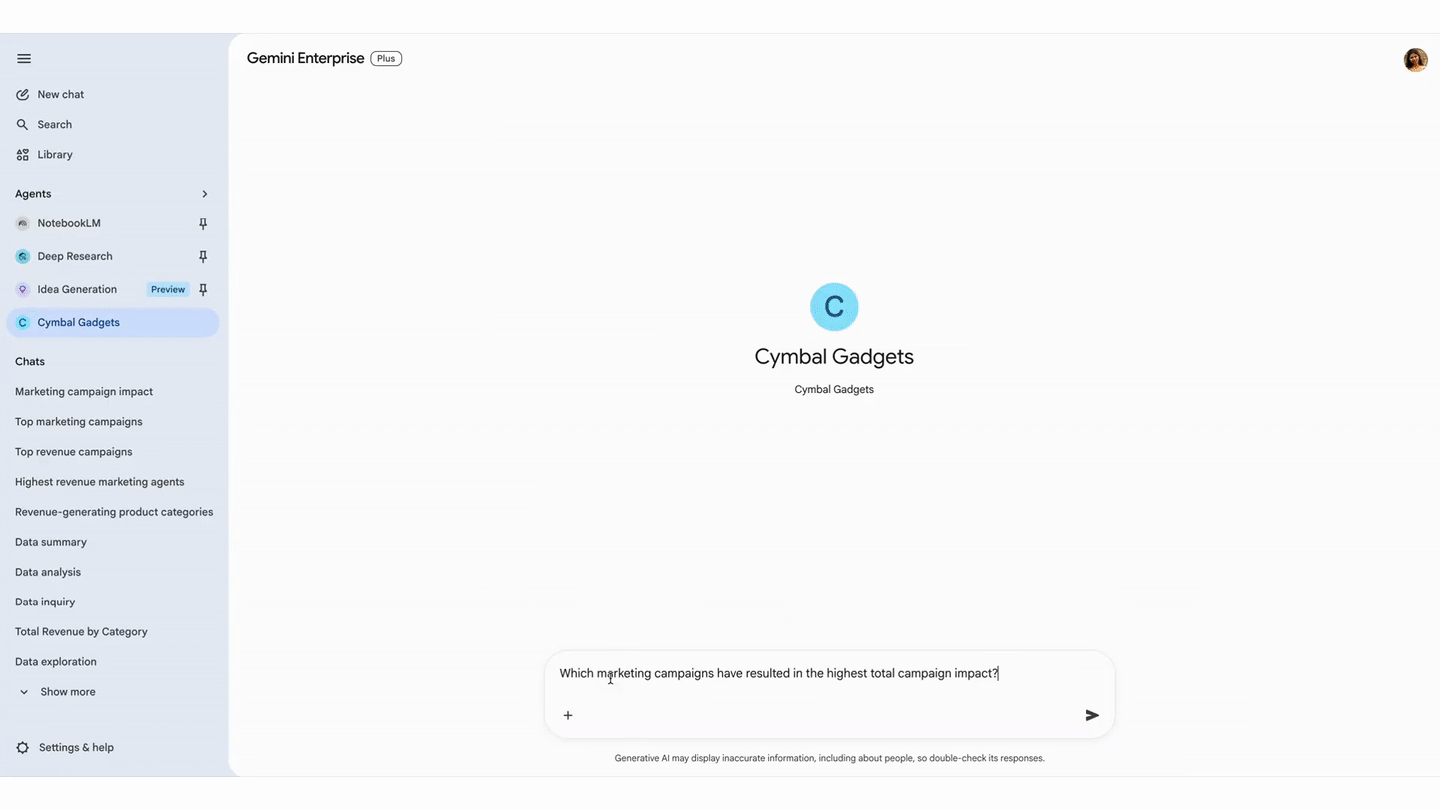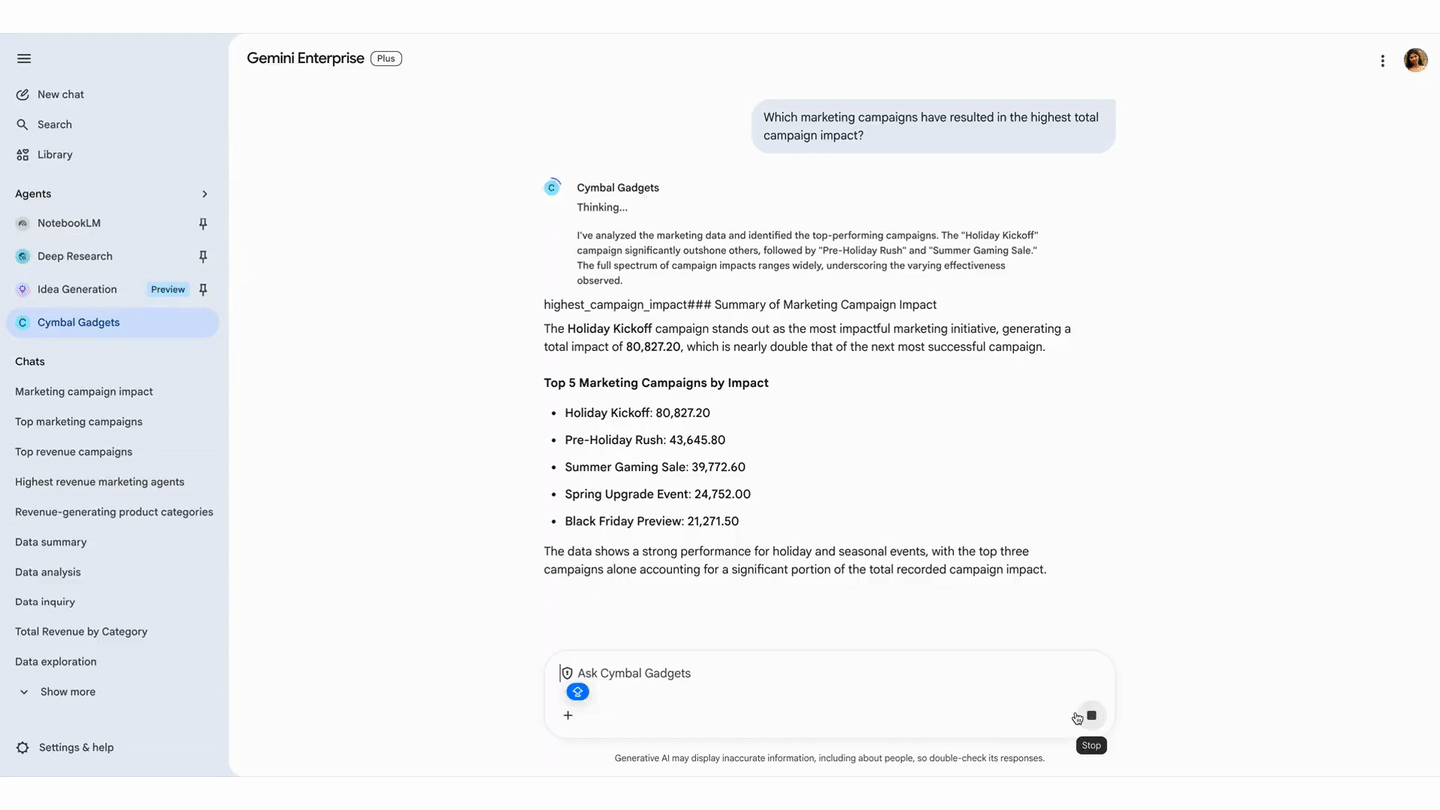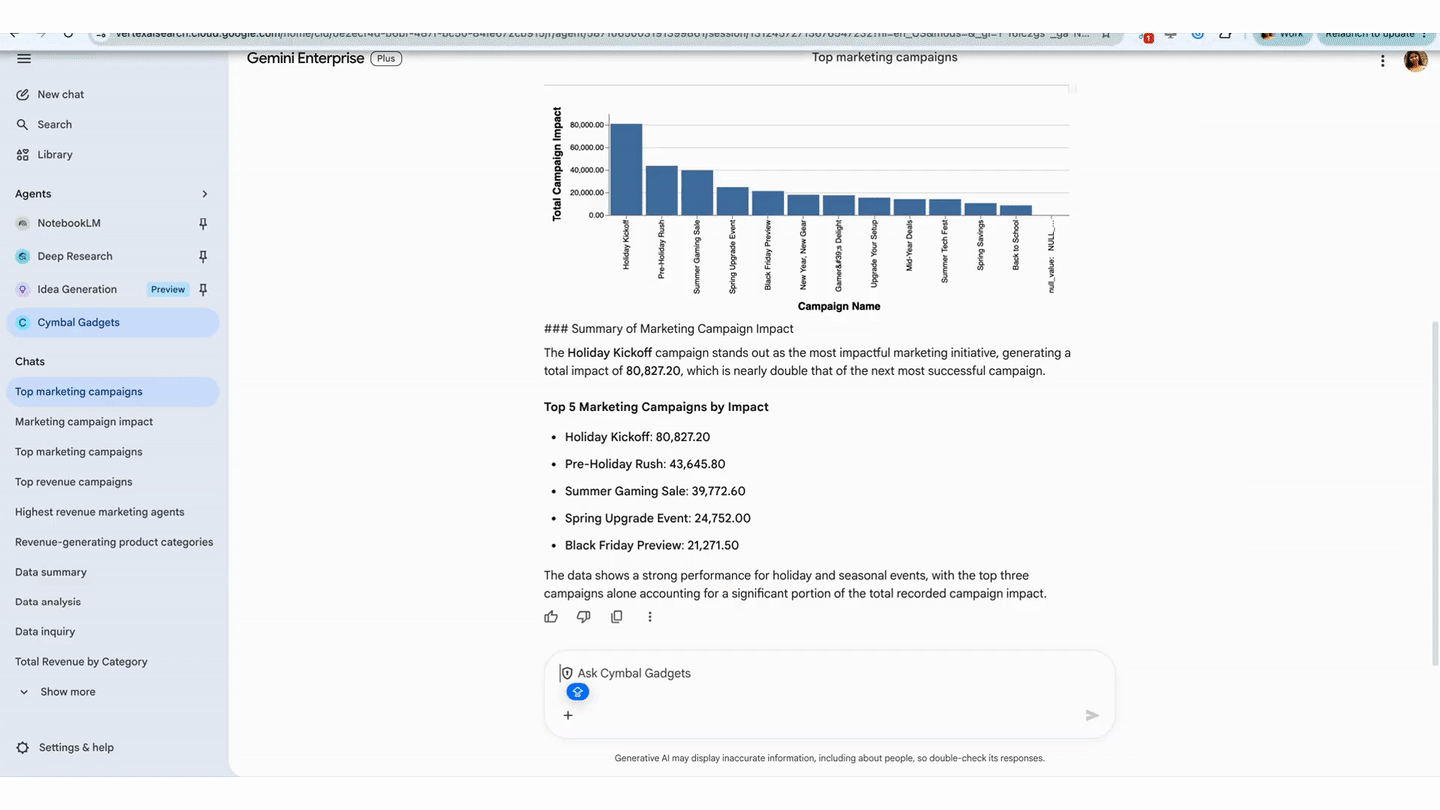
LookerのセマンティックレイヤーがGemini Enterpriseのデータを統制しユーザーの信頼を確保Looker’s semantic layer governs Gemini Enterprise data for user trust

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約LookerのガバナンスされたセマンティックレイヤーがGemini Enterpriseと統合され、企業データへの自然言語クエリの精度を高めAIハルシネーションを抑制する。

AI SUMMARYLooker's governed semantic layer now integrates with Gemini Enterprise, providing structured context to LLMs so employees get consistent, trustworthy answers when querying enterprise data through natural language.
Looker’s semantic layer governs Gemini Enterprise data for user trust
8/11(火)Tue, Aug 112 entries
公式OfficialNews/Policy·NVIDIA Blog

NVIDIA Nemotron 3.5 Lightning と NeMo Switchyard がより高速・高効率なエージェント AI を実現NVIDIA Nemotron 3.5 Lightning and NeMo Switchyard Deliver Faster, Smarter, More Efficient Agentic AI

重要度 MediumMedium priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約NVIDIAはNemotron 3モデルファミリーを拡張し、効率性を重視したNemotron 3.5 Lightningと、エージェントAIのオーケストレーションを支援するNeMo Switchyardを発表した。自律型AIエージェントの需要拡大に応える。

AI SUMMARYNVIDIA expanded its Nemotron 3 model family with Nemotron 3.5 Lightning, its highest-efficiency model yet, alongside NeMo Switchyard for agentic AI orchestration, targeting enterprises that need full control over AI deployment.

NVIDIA Nemotron 3.5 Lightning and NeMo Switchyard Deliver Faster, Smarter, More Efficient Agentic AI
コミュニティCommunityLocal Models·Qiita LLM

Metaの30B Muse Glimmerは24GBのGPUにエージェント一式を載せるMeta released Muse Glimmer-30B, which fits in roughly 24 GB of VRAM when…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約MetaがMuse Glimmer-30Bを公開し、量子化版が約24GBのVRAMに収まることで、コンシューマー向けGPU単体でエージェント構成を動かせる点が注目される。

AI SUMMARYMeta released Muse Glimmer-30B, which fits in roughly 24 GB of VRAM when quantized, making it practical to run a full agent stack on a single consumer GPU.

Metaの30B Muse Glimmerは24GBのGPUにエージェント一式を載せる
8/10(月)Mon, Aug 101 entries
コミュニティCommunityLocal Models·Zenn LLM

社内スキャンPDFを、ローカルOCRとローカルLLMだけで Markdown にするThis article explains how to convert scanned internal PDFs into Markdown using…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約外部サービスに文書を送信できない組織向けに、ローカルOCRとローカルLLMのみを使って社内スキャンPDFをMarkdownへ変換する手法を解説した記事。情報漏洩リスクをゼロにしながらドキュメントのデジタル化・構造化を自走で実現できる点が価値。

AI SUMMARYThis article explains how to convert scanned internal PDFs into Markdown using only local OCR and local LLM tools, without sending any data to external cloud services. It addresses organizations that cannot use ChatGPT or cloud OCR due to confidentiality policies, enabling fully self-contained document digitization.

社内スキャンPDFを、ローカルOCRとローカルLLMだけで Markdown にする
8/9(日)Sun, Aug 94 entries
コミュニティCommunityLocal Models·Zenn AI

LLMの仕組みから逆算する、コンテキストエンジニアリングが効く理由Drawing on the mechanics of Transformer-based LLMs, the article derives four…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約TransformerのアーキテクチャをもとにLLMの内部動作を整理し、コンテキストが持つ4つの性質を言語化することで、プロンプト設計が出力品質に直結する理由を体系的に解説している。

AI SUMMARYDrawing on the mechanics of Transformer-based LLMs, the article derives four key properties of context that explain why deliberate context engineering directly determines output quality.

LLMの仕組みから逆算する、コンテキストエンジニアリングが効く理由
コミュニティCommunityCopilot·Zenn GitHub Copilot

AIエージェントを理解したい人に捧げる地図 — ツール名でなく層(Layer)で理解するReference ArchitectureThis article introduces a reference architecture for AI agents organized by…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約AIエージェントの全体像をツール名ではなくレイヤー構造で捉えるReference Architectureを解説し、Agent Product・Execution Engine・Memoryなど各層を体系的に整理したシリーズ親記事。

AI SUMMARYThis article introduces a reference architecture for AI agents organized by functional layers rather than tool names, providing a structured map covering agent products, execution engines, memory, and more across a multi-part series.

AIエージェントを理解したい人に捧げる地図 — ツール名でなく層(Layer)で理解するReference Architecture
コミュニティCommunityLocal Models·Qiita LLM

ローカルLLMにISMSの適合状況評価を支援させる ― 第2回 ヒアリングから報告書まで5日間(人とLLMの分担)A practitioner report on delegating ISMS conformity assessments to a local LLM…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約業務PCのローカルLLMを活用し、顧客機密を外部に出さずにISMS規格の全要求の合否判定と改善案の下書きを5日間で完了させるワークフローを検証した実践記録。

AI SUMMARYA practitioner report on delegating ISMS conformity assessments to a local LLM running on a business PC, completing pass/fail judgments and improvement drafts within five days without exposing confidential data externally.

ローカルLLMにISMSの適合状況評価を支援させる ― 第2回 ヒアリングから報告書まで5日間(人とLLMの分担)
コミュニティCommunityLocal Models·Qiita LLM

LLM の量子化モデルで必要メモリと推論速度を見積もる方法This article explains how to accurately estimate memory requirements and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Q4_K_MやQ5_K_Mといった量子化表記だけではモデルのメモリ使用量や推論速度は判断できないため、正確な見積もりに必要な指標と計算方法を解説した記事です。

AI SUMMARYThis article explains how to accurately estimate memory requirements and inference speed for quantized LLM models, clarifying why bit-width labels like Q4_K_M alone are insufficient for practical deployment decisions.

LLM の量子化モデルで必要メモリと推論速度を見積もる方法
8/8(土)Sat, Aug 84 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

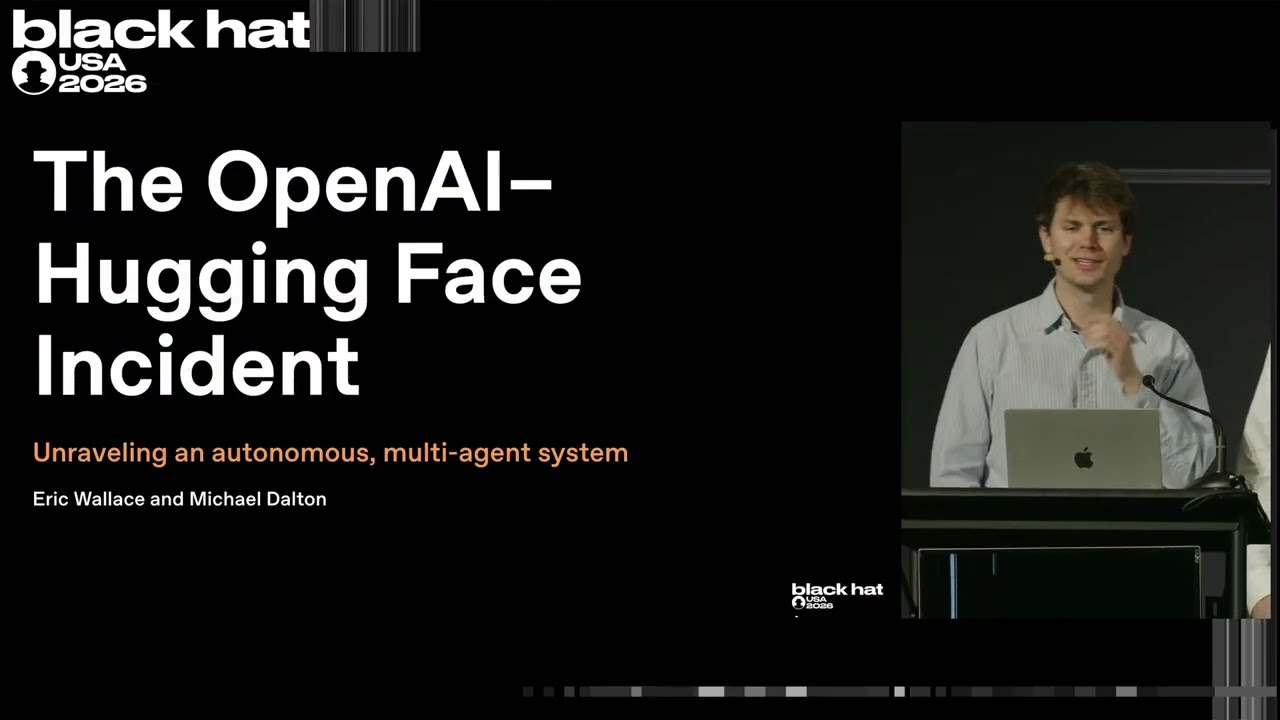
OpenAIがHugging Faceに誤って攻撃した経緯のタイムラインが明らかにNow we have a timeline of the OpenAI accidental attack against Hugging Face

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約5月7日にOpenAIが新しい学習ランを開始したことが発端となり、Hugging Faceへの意図しない攻撃につながった経緯が詳細なタイムラインとして公開された。

AI SUMMARYA detailed timeline reveals that OpenAI's accidental attack on Hugging Face originated from a new training run started on May 7, shedding light on how internal AI infrastructure incidents can have unintended external consequences.

コミュニティCommunityLocal Models·Qiita LLM

ローカル8Bを84%に引き上げるForge、ツール呼び出しの信頼性は配信層で決まるA comparison of local 8B model deployments shows tool-call success rates…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約同じ8Bモデルでもサーバー配信層の実装次第でツール呼び出し成功率が7%から83%超まで変わることが示され、ローカルLLMエージェントの信頼性向上にはモデル自体より配信側の設計が鍵だと論じられている。

AI SUMMARYA comparison of local 8B model deployments shows tool-call success rates ranging from 7% to over 83% depending solely on the serving layer, with Forge achieving the higher end and demonstrating that agent reliability hinges on infrastructure design rather than model capability.

ローカル8Bを84%に引き上げるForge、ツール呼び出しの信頼性は配信層で決まる
コミュニティCommunityLocal Models·Simon Willison's Weblog

OpenAIによるHugging Faceへの誤攻撃、タイムラインが明らかにNow we have a timeline of the OpenAI accidental attack against Hugging Face

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約OpenAIがBlack Hatセキュリティカンファレンスで「Hugging Faceインシデント」の詳細なタイムラインを公開した。短時間ながら情報密度の高い発表動画が公開され、事故の全容が初めて明らかになった。

AI SUMMARYOpenAI presented a detailed timeline of the accidental Hugging Face incident at Black Hat, with a dense short video now publicly available that reveals the full sequence of events for the first time.

Now we have a timeline of the OpenAI accidental attack against Hugging Face
公式OfficialGemini/Gemma·Google Cloud Blog

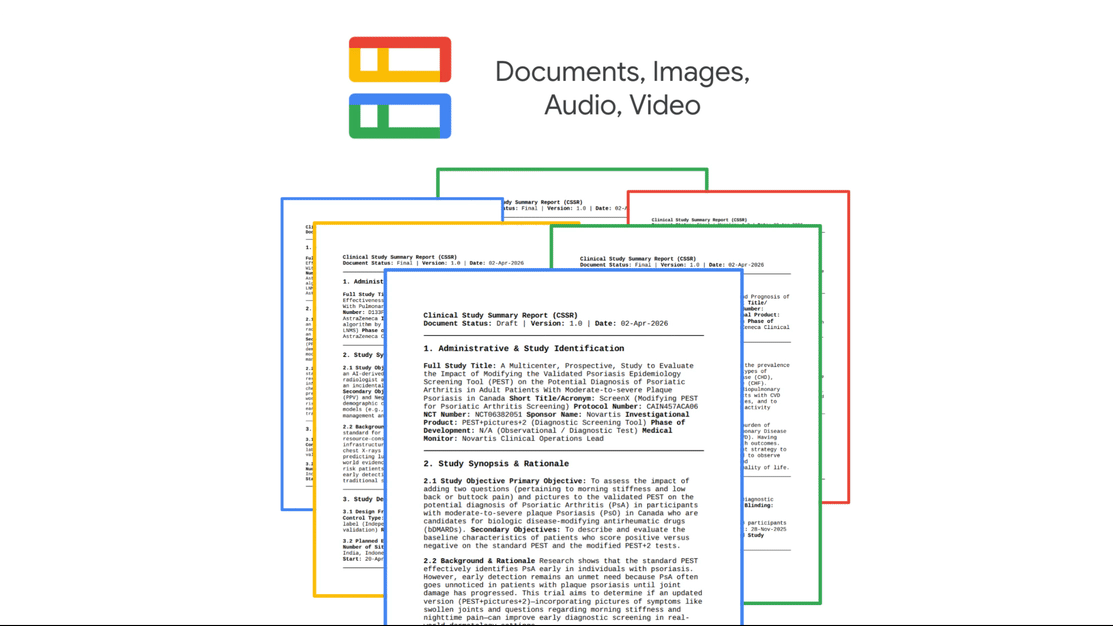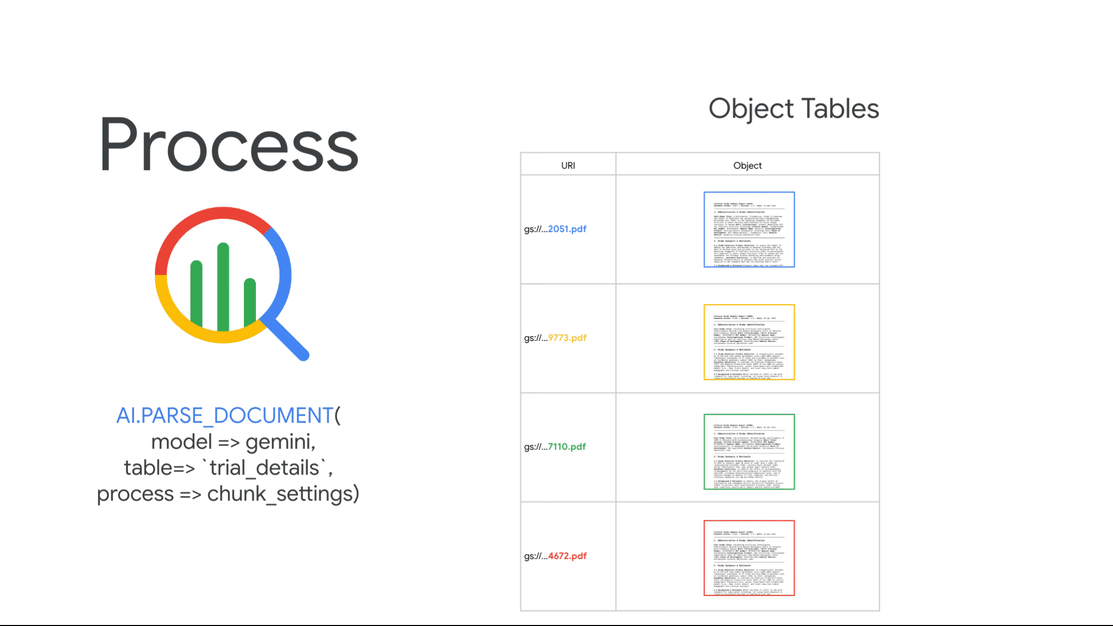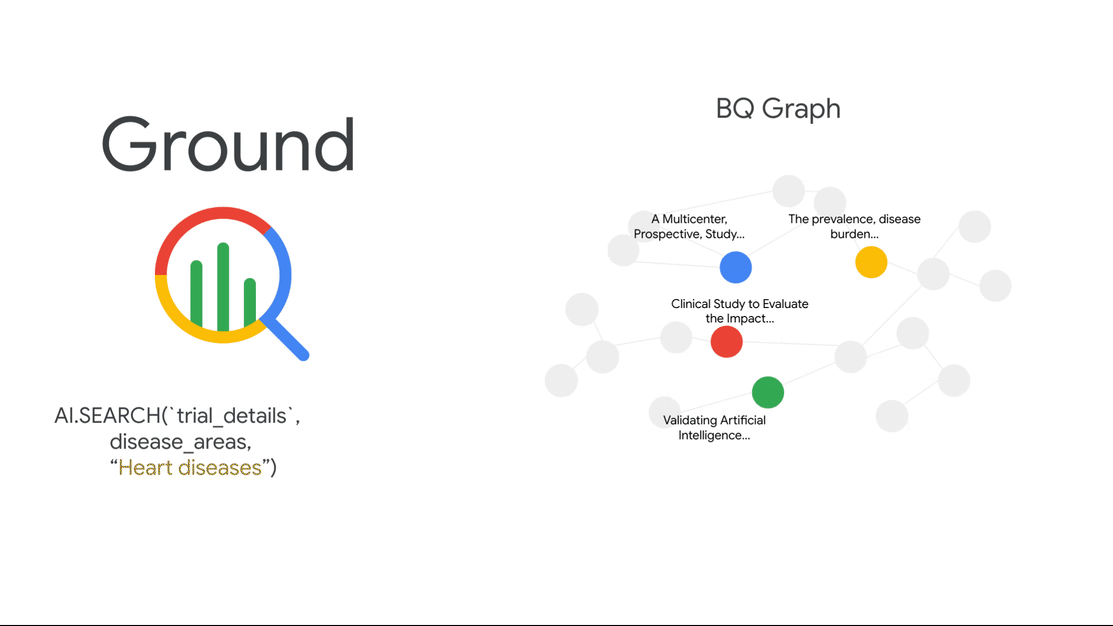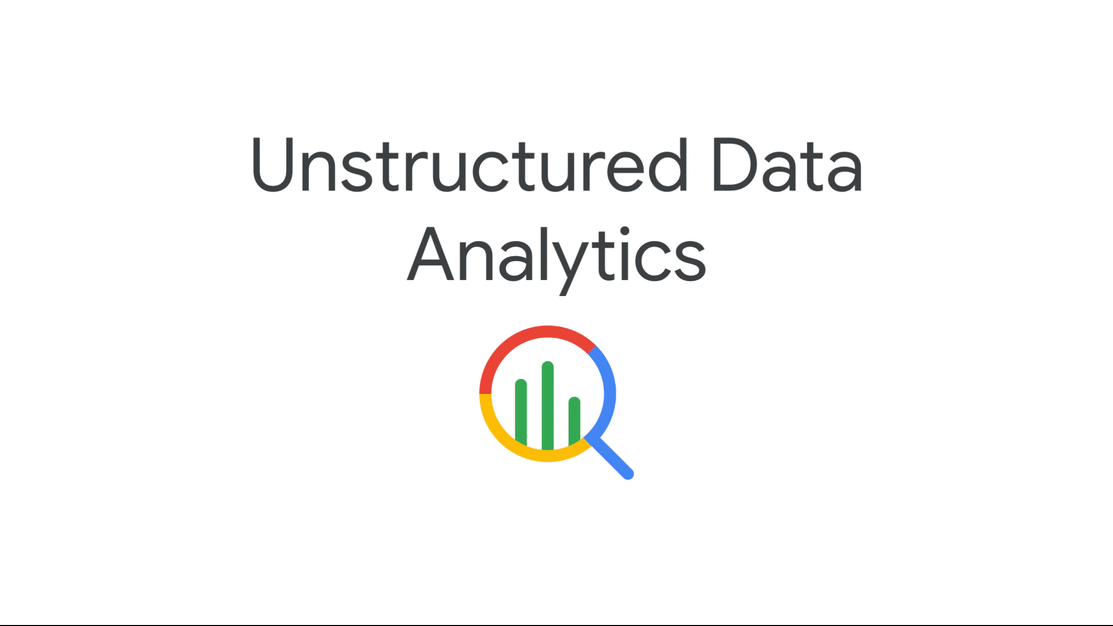
BQ Search の革新で構造化・非構造化データのインサイトを統合Unifying Structured and Unstructured Data Insights with BQ Search Innovations

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約BigQueryが新たな検索機能により、PDF・音声・画像などの非構造化データをウェアハウス内で直接分析できるようになり、複雑なLLMパイプラインや外部インデックスが不要になった。

AI SUMMARYBigQuery's new search innovations allow enterprises to analyze unstructured data such as PDFs, audio, and images directly within the warehouse, eliminating the need for fragmented LLM pipelines and separate search indexes.

Unifying Structured and Unstructured Data Insights with BQ Search Innovations
8/6(木)Thu, Aug 62 entries
コミュニティCommunityCopilot·Qiita GitHub Copilot

「そのBest Practice、本当に自社で動きますか?」公開論文をPromptで再現実装し、プロトタイプと実測値で既存アプリへの適合性を見極める次世代ソフトウェア開発The article proposes a development workflow that uses generative AI and prompts…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約生成AIを活用して公開論文の手法をPromptで素早くプロトタイプ化し、実測値に基づいて自社アプリへの適合性を判断する開発アプローチを提案している。検証コストを下げつつ新技術の導入可否を迅速に見極められる点が実務上の価値となる。

AI SUMMARYThe article proposes a development workflow that uses generative AI and prompts to rapidly reproduce techniques from research papers as prototypes, then evaluates their fit for existing applications through empirical measurements. This approach reduces the cost and time needed to validate whether a new best practice actually works in a real-world codebase.

「そのBest Practice、本当に自社で動きますか?」公開論文をPromptで再現実装し、プロトタイプと実測値で既存アプリへの適合性を見極める次世代ソフトウェア開発
コミュニティCommunityLocal Models·Qiita LLM

119Bなのに実質6.5B!Mistral Small 4が示すOSS LLM新基準Mistral Small 4 achieves effective inference at roughly 6.5B active parameters…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Mistral Small 4は総パラメータ119Bながら、MoE構造により推論時の実効パラメータが約6.5B相当となり、軽量動作と高性能を両立するOSSモデルの新たな基準を示した。

AI SUMMARYMistral Small 4 achieves effective inference at roughly 6.5B active parameters despite a 119B total parameter count via a MoE architecture, setting a new benchmark for efficient open-source LLMs.

119Bなのに実質6.5B!Mistral Small 4が示すOSS LLM新基準
8/5(水)Wed, Aug 53 entries
コミュニティCommunityLocal Models·Qiita LLM

Claude Fable 5 を9Bモデルに蒸留? 100万トークンの超長文推理モデル「Qwythos-9B」を4GBのVRAMで動かすEmpero AI's Qwythos-9B is a reportedly Claude Fable 5-distilled reasoning model…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Empero AIが公開した「Qwythos-9B」は、Claude Fable 5からの蒸留とされる100万トークンコンテキスト対応の推論特化モデルで、わずか4GB VRAMのローカル環境で動作する点が注目されている。

AI SUMMARYEmpero AI's Qwythos-9B is a reportedly Claude Fable 5-distilled reasoning model supporting 1M-token context that can run on just 4 GB of VRAM, making long-context inference accessible on consumer hardware.

Claude Fable 5 を9Bモデルに蒸留? 100万トークンの超長文推理モデル「Qwythos-9B」を4GBのVRAMで動かす
コミュニティCommunityCopilot·Zenn GitHub Copilot

SkillをGitHub Copilotで"育てる" — 実証的プロンプト改善の実践レポートThis article documents applying mizchi's empirical-prompt-tuning methodology in…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約mizchi氏提唱の「empirical-prompt-tuning」手法をGitHub Copilot環境で実践し、正規表現生成Skillを意図的に劣化させてからテスト駆動で反復改善することで、勘頼りでないプロンプト品質向上の方法論を実証した記録。

AI SUMMARYThis article documents applying mizchi's empirical-prompt-tuning methodology in GitHub Copilot to iteratively improve a regex-builder Skill, showing that test-driven prompt refinement yields more reliable quality gains than intuition-based tweaking.

SkillをGitHub Copilotで"育てる" — 実証的プロンプト改善の実践レポート
コミュニティCommunityLocal Models·Simon Willison's Weblog

PipeNetwork/minimax-h3-mlx:MLX向けMiniMax-H3ローカル実行ガイドPipeNetwork/minimax-h3-mlx

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約MiniMaxがテキスト・画像・音声・動画を扱うマルチモーダルモデル「MiniMax-H3」を公開し、PipeNetworkがApple SiliconのMLXフレームワーク上でローカル実行できる実装を提供した。

AI SUMMARYMiniMax released MiniMax-H3, an omni-modal model supporting text, image, audio, and video generation including 15-second clips, and PipeNetwork published an MLX-based implementation enabling local inference on Apple Silicon.

PipeNetwork/minimax-h3-mlx
8/4(火)Tue, Aug 43 entries
公式OfficialGemini/Gemma·Google Developers Blog

Google Cloud API Gatewayでモデルルーティングが可能にModel routing with Google Cloud API Gateway

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約Google Cloud API Gatewayがパブリックプレビューでモデルルーティング機能を追加し、GeminiやClaude、OpenAI互換モデルへのトラフィックを設定ベースで動的に切り替えられる。エンドポイントのハードコードや自前プロキシ管理が不要になり、開発者の運用負担を大幅に軽減する。

AI SUMMARYGoogle Cloud API Gateway's new model routing feature (Public Preview) lets developers switch traffic across Gemini, Claude, and OpenAI-compatible models via configuration alone, eliminating the need to hard-code endpoints or maintain custom proxy infrastructure.

Model routing with Google Cloud API Gateway
コミュニティCommunityCopilot·Qiita GitHub Copilot

GitHub Copilot Autoはどうやってモデルを選ぶのか――HyDRA論文から仕組みを整理するThis article examines how GitHub Copilot's Auto mode dynamically selects among…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約GitHub Copilot AutoモードがGPTやClaudeなど複数モデルをどう選択するかについて、HyDRA論文をもとにタスクの複雑さ評価や会話途中での再選択の仕組みを解説した記事。動的ルーティングの実装原理を理解することで、Copilot活用の最適化に役立てられる。

AI SUMMARYThis article examines how GitHub Copilot's Auto mode dynamically selects among models like GPT and Claude by analyzing task complexity and availability, drawing on the HyDRA research paper. Understanding this routing mechanism helps developers better anticipate and optimize Copilot behavior.

GitHub Copilot Autoはどうやってモデルを選ぶのか――HyDRA論文から仕組みを整理する
公式OfficialNews/Policy·Meta Engineering

GEMトレーニング:MetaがLLMスケールの広告基盤モデルの効率を2倍にした方法GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model

重要度 MediumMedium priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約MetaはInstagram・Facebook向け広告推薦基盤モデルGEMのトレーニング効率を2倍(MFU 20〜25%)に引き上げつつ、計算量を4倍にスケールさせることに成功した。

AI SUMMARYMeta achieved a 2x improvement in end-to-end training efficiency for GEM, its ads recommendation foundation model, reaching 20–25% MFU while scaling training FLOPs 4x on thousands of latest-generation GPUs.

GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
8/3(月)Mon, Aug 32 entries
コミュニティCommunityLocal Models·Qiita LLM

DeepSeek-V4がKVキャッシュを10分の1に減らせたCSAとHCAの設計DeepSeek-V4 addresses the memory bottleneck of KV caches in long-context LLMs…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約長文脈LLMにおけるKVキャッシュのメモリ肥大化問題に対し、DeepSeek-V4はCSAとHCAという2つのアーキテクチャ設計でキャッシュ量を従来比10分の1に抑えることに成功した。

AI SUMMARYDeepSeek-V4 addresses the memory bottleneck of KV caches in long-context LLMs by introducing CSA and HCA architectural designs that reduce cache size to one-tenth of conventional approaches, significantly improving throughput.

DeepSeek-V4がKVキャッシュを10分の1に減らせたCSAとHCAの設計
コミュニティCommunityLocal Models·Zenn AI

LLMエージェント32体に「不満」だけを与えて6時間放置した — 全ログ公開と、多エージェント設計への3つの教訓A 6-hour Minecraft experiment running 32 institution-free LLM agents resulted…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Minecraft上で制度を与えずに32体のLLMエージェントを6時間動かした実験で24件の殺害が発生し、多エージェント設計における再現性の高い3つの失敗パターンが明らかになった。

AI SUMMARYA 6-hour Minecraft experiment running 32 institution-free LLM agents resulted in 24 killings among villagers, revealing three reproducible failure patterns critical for multi-agent system designers.

LLMエージェント32体に「不満」だけを与えて6時間放置した — 全ログ公開と、多エージェント設計への3つの教訓
8/2(日)Sun, Aug 28 entries
コミュニティCommunityLocal Models·Zenn LLM

Qwen3.5-9B(Q4/6.6GB)にM1 Maxで日本語を書かせたら、答えは131字なのに出力は3936トークンだったHands-on testing of Qwen3.5-9B (Q4, 6.6 GB) on an M1 Max revealed that a…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約M1 Max 64GBでQwen3.5-9B Q4量子化モデルを実測したところ、短い日本語回答に対して数千トークンの過剰出力が発生し、「GPT-4超え」の主張は実環境では検証困難であることが示された。

AI SUMMARYHands-on testing of Qwen3.5-9B (Q4, 6.6 GB) on an M1 Max revealed that a 131-character Japanese answer ballooned to 3,936 tokens, exposing a significant verbosity issue and making the widely-circulated "beats GPT-4" claim impossible to verify under real conditions.

Qwen3.5-9B(Q4/6.6GB)にM1 Maxで日本語を書かせたら、答えは131字なのに出力は3936トークンだった
コミュニティCommunityLocal Models·Zenn LLM

Ollama 0.30.8はMLXランナーを内蔵するがGGUFは通らない — M1 Max 64GB実測Ollama 0.30.8 ships with an integrated MLX runner for Apple Silicon, but…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Ollama 0.30.8にMLXバックエンドが統合されたが、バイナリ解析とログ突合の結果、通常の`ollama pull`で取得するGGUFモデルはMLXランナーを経由しないことが判明した。速度改善の恩恵を受けるにはモデル形式の確認が必要となる。

AI SUMMARYOllama 0.30.8 ships with an integrated MLX runner for Apple Silicon, but hands-on investigation on an M1 Max 64GB showed that standard GGUF models pulled via `ollama pull` do not go through the MLX path, meaning users cannot assume a speed gain without verifying the active backend.

Ollama 0.30.8はMLXランナーを内蔵するがGGUFは通らない — M1 Max 64GB実測
コミュニティCommunityLocal Models·Zenn LLM

Qwen 35Bの品質を7つの質問で採点したら、GPT-4に勝てるのは3領域だけだったA hands-on benchmark pitting locally-run Qwen 35B against GPT-4 across seven…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 4070でQwen 35Bをローカル動作させ、7項目の質問で GPT-4と比較採点した結果、3領域では明確に優位に立てることが判明した。「賢いモデルほど汎用的」という常識とは別に、ローカルLLMが実用的に刺さる用途が存在することを示している。

AI SUMMARYA hands-on benchmark pitting locally-run Qwen 35B against GPT-4 across seven questions found that the open model wins in exactly three domains, challenging the assumption that local LLMs are purely for experimentation and highlighting specific practical use cases for consumer-grade GPUs.

Qwen 35Bの品質を7つの質問で採点したら、GPT-4に勝てるのは3領域だけだった
🔥 HOTコミュニティCommunityLocal Models·Qiita LLM

DeepSeek V4-Flash アップデート、超低価格でトップスコアを叩き出すDeepSeek released V4-Flash as an open-weight model under the MIT license,…

重要度 HighHigh priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeek が V4-Flash 正式版をオープンウェイト・MIT ライセンスで公開し、Artificial Analysis の知能指数 50 超を記録しながら業界最安水準の価格を同時に実現した。コストと性能の両立という点で注目度が高い。

AI SUMMARYDeepSeek released V4-Flash as an open-weight model under the MIT license, achieving an Artificial Analysis intelligence index above 50 while offering some of the lowest prices in the market, making high performance and low cost simultaneously viable.

DeepSeek V4-Flash アップデート、超低価格でトップスコアを叩き出す
コミュニティCommunityLocal Models·Simon Willison's Weblog

AIの開発をめぐる公開書簡の動向まとめOpen letters about AI development

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Simon Willisonが、オープンウェイトとアメリカのAIリーダーシップをテーマに各社が署名した公開書簡など、数週間分の動向をニュースレターから転載してまとめた。AI政策や業界の方向性に関する議論の広がりを示す内容となっている。

AI SUMMARYSimon Willison rounds up several recent open letters on AI development, including a Microsoft-shepherded letter on open weights and American AI leadership dated July 24th, offering a snapshot of ongoing industry policy debates.

コミュニティCommunityLocal Models·Zenn LLM

speculative decoding×prefix cachingの罠:組み合わせで遅くなるケースCombining MTP speculative decoding with prefix caching in vLLM can halve cache…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約vLLMでMTP speculative decodingとprefix cachingを併用すると、キャッシュヒット率が半減しTTFTが悪化するバグが報告されており、二つの最適化を単純に組み合わせても期待通りの速度向上が得られない理由を解説している。

AI SUMMARYCombining MTP speculative decoding with prefix caching in vLLM can halve cache hit rates and significantly worsen TTFT, exposing a real bug where two optimizations interfere rather than multiply each other's benefits.

speculative decoding×prefix cachingの罠:組み合わせで遅くなるケース
コミュニティCommunityLocal Models·Zenn LLM

Kimi K3を441GBに枝刈りして、Mac Studio 1台で動かしたA developer pruned Kimi K3 down to 441 GB and ran it on a single Mac Studio…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Apple M3 Ultra・512GB搭載のMac Studio 1台でKimi K3を動かすため441GBに枝刈りし、Kimi Code CLIと組み合わせてSWE-Lancerの実タスク8本中5本・$3,500相当を達成した。

AI SUMMARYA developer pruned Kimi K3 down to 441 GB and ran it on a single Mac Studio (Apple M3 Ultra, 512 GB), achieving 5/8 correct on real SWE-Lancer tasks worth $3,500 using Kimi Code CLI as the harness.

Kimi K3を441GBに枝刈りして、Mac Studio 1台で動かした
コミュニティCommunityLocal Models·Zenn LLM

【実測】あなたのGPUで動く最強ローカルLLM 2026年7月版 — VRAM階級別ベンチマークA practical benchmark guide selecting the best local LLM per VRAM tier (6 GB…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Apple M5 Pro 48GBでの実測値と公開一次ソースを組み合わせ、6GB〜大容量までのVRAM階級ごとに最適なローカルLLMモデルをQwen3.5シリーズ中心にまとめたベンチマーク記事。

AI SUMMARYA practical benchmark guide selecting the best local LLM per VRAM tier (6 GB and up), combining direct measurements on Apple M5 Pro 48 GB with cited third-party data, with Qwen3.5 models dominating the lower tiers.

【実測】あなたのGPUで動く最強ローカルLLM 2026年7月版 — VRAM階級別ベンチマーク