Home›Tags›#llm›Page 2

Tag timeline

#llmpage 2/10

同じキーワードで束ねられた更新の続きです。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total273#llm の全掲載記事All listed entries tagged #llm
Showing30このページの件数Entries on this page
Page2/10静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 2/10 · 273 total

8/18(火)Tue, Aug 183 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Qwen 3.8 27BがArtificial Analysis Intelligence Indexでスコア52を達成Qwen 3.8 27B scores 52 on the Artificial Analysis Intelligence Index

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約27BパラメータのQwen 3.8 27BがGPT-5.6 Lunaと同スコア52を記録し、753BのGLMや1.6TのDeepSeek V4 Proとほぼ同等の性能を示した。小規模モデルがはるかに大きなモデルと肩を並べた点が注目される。

AI SUMMARYQwen 3.8 27B achieved a score of 52 on the Artificial Analysis Intelligence Index, matching GPT-5.6 Luna and nearly tying the 753B GLM-5.2 and 1.6T DeepSeek V4 Pro, highlighting strong efficiency at a much smaller parameter count.

公式OfficialOpenHands/OpenCode·OpenHands Releases

OpenHands v1.14.0 リリースOpenHands Releases v1.14.0

重要度 MediumMedium priority公式リリース · OpenHands / OpenCodeofficial release · OpenHands / OpenCode

AI要約OpenHands v1.14.0では、構造化エラー表示やLLM設定の事前検証、Git同期ページの追加など複数の新機能が導入された。

AI SUMMARYOpenHands v1.14.0 adds canvas structured error display, LLM pre-flight validation to block misconfigured profiles, and a new Git Sync page for automations.

OpenHands Releases v1.14.0
コミュニティCommunityLocal Models·Zenn AI

LLM による意味論検証を支える規律 〜参照整合性への応用例を添えて〜Semantic validation has long relied on costly and inconsistent human review,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約構文検証は機械が担ってきたが、意味論検証は人間のレビューに依存していた。LLM を活用することで、設計意図との整合性チェックを自動化・再現可能にできると論じた記事。

AI SUMMARYSemantic validation has long relied on costly and inconsistent human review, but LLMs can now automate it by reading meaning across code and natural language, as demonstrated through a referential integrity use case.

LLM による意味論検証を支える規律 〜参照整合性への応用例を添えて〜
8/17(月)Mon, Aug 174 entries
コミュニティCommunityLocal Models·Qiita LLM

DeepSeek ローカル実行完全ガイド2026 — Ollama・LM Studio・vLLMで自分のPCに導入A practical 2026 guide covering three methods—Ollama, LM Studio, and vLLM—for…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約MITライセンスで公開されているDeepSeekモデルを、APIキーや月額費用なしで自分のPC上に構築する方法をOllama・LM Studio・vLLMの3手法で解説した実践ガイド。

AI SUMMARYA practical 2026 guide covering three methods—Ollama, LM Studio, and vLLM—for running DeepSeek's MIT-licensed models locally without API keys or subscription costs, keeping data entirely on your own machine.

DeepSeek ローカル実行完全ガイド2026 — Ollama・LM Studio・vLLMで自分のPCに導入
コミュニティCommunityLocal Models·Qiita LLM

vLLMの-dcpが長文脈のKVキャッシュ重複を消して3倍速くするvLLM's -dcp option eliminates redundant KV cache memory caused by tensor…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約テンソル並列構成でGPUのメモリがKVキャッシュの重複で枯渇する問題に対し、vLLMの-dcpオプションが重複を排除し、長文脈推論のスループットを最大3倍改善する。

AI SUMMARYvLLM's -dcp option eliminates redundant KV cache memory caused by tensor parallelism in long-context deployments, enabling up to 3× higher throughput by freeing GPU memory that was previously wasted on duplicated cache entries.

vLLMの-dcpが長文脈のKVキャッシュ重複を消して3倍速くする
コミュニティCommunityLocal Models·Simon Willison's Weblog

Qwen 3.8 27Bは優秀だが、デフォルトで過剰な思考をするQwen 3.8 27B is excellent, but it defaults to wildly overthinking things

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約AlibabaのQwen研究室がApache 2ライセンスのビジョン対応27Bモデル「Qwen 3.8 27B」をリリース。ラップトップで動作する優れたサイズだが、デフォルトで過剰な推論を行う傾向がある点に注意が必要。

AI SUMMARYAlibaba's Qwen lab released Qwen 3.8 27B, an Apache 2 licensed vision-capable model well-suited for laptop inference, though its tendency to overthink by default is a notable caveat for practical use.

Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
コミュニティCommunityLocal Models·Zenn AI

LLMウォーターマークってなんだ?This article explains LLM watermarking — a technique that embeds statistical…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMウォーターマークは、AIが生成した文章にトークン選択の統計的偏りを埋め込むことでAI生成を検証する技術であり、改ざん耐性や実用上の限界も含めて解説されている。

AI SUMMARYThis article explains LLM watermarking — a technique that embeds statistical biases into token selection during text generation to verify AI authorship — and examines its practical limitations and resistance to tampering.

LLMウォーターマークってなんだ?
8/16(日)Sun, Aug 169 entries
コミュニティCommunityLocal Models·Zenn LLM

Qwen3.8 27B に Reasoning Effort を実装してみるThe author resolved Qwen3.8 27B's tendency to over-think on ambiguous tasks by…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Qwen3.8 27Bで思考が長引き生成上限に達する問題を、llama.cppのPer-request reasoning budgetで強制打ち切りすることで解消し、曖昧なタスクでも自律的に完走できるようになった。

AI SUMMARYThe author resolved Qwen3.8 27B's tendency to over-think on ambiguous tasks by enabling per-request reasoning budget in llama.cpp, allowing the model to complete complex tasks like Minecraft clone creation autonomously without hitting generation limits.

Qwen3.8 27B に Reasoning Effort を実装してみる
コミュニティCommunityLocal Models·Qiita LLM

RTX 4070 Ti SUPER 16GBでQwen3.8-27Bを動かしてみた ― OpenCodeは16Kで止まり、32KでWebアプリを完遂したA hands-on report running Qwen3.8-27B locally on an RTX 4070 Ti SUPER 16 GB GPU…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Ubuntu搭載の自宅PCでQwen3.8-27BをローカルLLMとして稼働させ、コーディングエージェントOpenCodeを使ったWebアプリ生成をコンテキスト長16Kと32Kで比較検証した結果、32Kでのみ完走できることが確認された。

AI SUMMARYA hands-on report running Qwen3.8-27B locally on an RTX 4070 Ti SUPER 16 GB GPU shows that the OpenCode coding agent fails to complete a web-app task at a 16 K context window but succeeds at 32 K, offering practical guidance for consumer-GPU LLM setups.

RTX 4070 Ti SUPER 16GBでQwen3.8-27Bを動かしてみた ― OpenCodeは16Kで止まり、32KでWebアプリを完遂した
コミュニティCommunityLocal Models·Qiita LLM

自社推論Runtime:Lykuro Native Inference EngineLykuro has released its own open-source native LLM inference engine, claiming…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LykuroがオープンソースのネイティブLLM推論エンジンを公開し、ollamaおよびMLX-MLを上回るパフォーマンスを達成したと主張している。ローカルLLM推論の選択肢として注目される。

AI SUMMARYLykuro has released its own open-source native LLM inference engine, claiming superior performance over ollama and MLX-ML for local model execution.

自社推論Runtime:Lykuro Native Inference Engine
コミュニティCommunityClaude Code·Zenn Claude

【最速7分】ローカルLLM×Tauriで爆速Markdownビューアを作らせた必勝パターンThe author demonstrates a workflow for auto-generating a lightweight…

重要度 MediumMedium priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約ローカルLLMとクラウドAIを組み合わせ、Tauriベースの軽量Markdownビューアをわずか7分で自動生成する手法を解説。各LLMのコーディング能力比較やWindows環境特有の落とし穴も紹介している。

AI SUMMARYThe author demonstrates a workflow for auto-generating a lightweight Tauri-based Markdown viewer in under seven minutes using local and cloud LLMs, while comparing model coding capabilities and highlighting Windows-specific pitfalls in AI-assisted desktop development.

【最速7分】ローカルLLM×Tauriで爆速Markdownビューアを作らせた必勝パターン
コミュニティCommunityLocal Models·Qiita LLM

Qwen3.8-27B は MoE ではなかった — ローカル音声対話AIへの採用を30回計測して見送るまでThe author evaluated replacing Qwen3.6-35B-A3B (MoE) with Qwen3.8-27B in a…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Ryzen AI MAX+ 395環境のローカル音声対話AIで、MoEモデルのQwen3.6-35B-A3BからQwen3.8-27Bへの乗り替えを検討したが、27Bがdense modelであると判明し、速度・品質の計測30回の結果として採用を見送った。

AI SUMMARYThe author evaluated replacing Qwen3.6-35B-A3B (MoE) with Qwen3.8-27B in a fully local voice-dialogue AI on Ryzen AI MAX+ 395, but after 30 benchmark runs discovered the 27B is a dense model and ultimately decided against the switch.

Qwen3.8-27B は MoE ではなかった — ローカル音声対話AIへの採用を30回計測して見送るまで
コミュニティCommunityLocal Models·Qiita LLM

ローカルLLMにISMSの適合状況評価を支援させる ― 第3回 評価者の判断を「部品」に作り込む話This third installment explains why passing raw ISMS clause text to a local LLM…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約ISO/IEC 27001の条文をそのままLLMに渡しても信頼できる合否判定は得られないため、評価者の判断基準を構造化した「部品」として設計し、ローカルLLMに組み込む手法を解説した連載第3回。

AI SUMMARYThis third installment explains why passing raw ISMS clause text to a local LLM yields unreliable verdicts, and details how to encode auditor judgment into structured components that the model can apply consistently.

ローカルLLMにISMSの適合状況評価を支援させる ― 第3回 評価者の判断を「部品」に作り込む話
コミュニティCommunityLocal Models·Qiita LLM

【ローカルLLM】Qwen3.8-27Bの推論性能をテストする(WSL2 + Ollama + RTX 5070 Ti)A hands-on benchmark of Qwen3.8-27B running locally via Ollama on WSL2 with an…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約新公開のQwen3.8-27BをWSL2+Ollama+RTX 5070 Ti環境でローカル動作させ、ThinkモードでのGGUF量子化モデルの推論性能を検証した実践レポート。

AI SUMMARYA hands-on benchmark of Qwen3.8-27B running locally via Ollama on WSL2 with an RTX 5070 Ti, evaluating reasoning performance in Think mode using a Q4_K_M GGUF quantized model.

【ローカルLLM】Qwen3.8-27Bの推論性能をテストする(WSL2 + Ollama + RTX 5070 Ti)
コミュニティCommunityLocal Models·Zenn AI

LLMを賢くするのではなく「境界」を作る——AXIOM Framework Prototypeを作ってみたThe author built a prototype called AXIOM Framework to address recurring issues…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMへの曖昧な指示や複数言語間の解釈のズレ、エージェント増加に伴う権限管理の複雑化といった課題を解決するため、入力と処理に明示的な「境界」を設けるAXIOM Frameworkのプロトタイプを開発した経緯と設計思想を紹介している。

AI SUMMARYThe author built a prototype called AXIOM Framework to address recurring issues with LLM-based systems—such as ambiguous instruction drift, cross-language inconsistencies, and uncontrolled agent permissions—by imposing explicit boundaries between input and interpretation rather than trying to make the LLM smarter.

LLMを賢くするのではなく「境界」を作る——AXIOM Framework Prototypeを作ってみた
コミュニティCommunityLocal Models·Qiita LLM

DeepSeek V4 Pro (0813)をAPIで使って分かった、AIエージェント実装の落とし穴Integrating DeepSeek V4 Pro (0813) into AI agents and tool-calling workflows…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeek V4 Proを単発チャットでなくエージェントやツール呼び出しに組み込む際、思考トークンの扱いや長文出力に起因する実装上の注意点が明らかになった。

AI SUMMARYIntegrating DeepSeek V4 Pro (0813) into AI agents and tool-calling workflows reveals subtle pitfalls—such as handling reasoning tokens and long outputs—that do not surface in simple chat usage.

DeepSeek V4 Pro (0813)をAPIで使って分かった、AIエージェント実装の落とし穴
8/15(土)Sat, Aug 154 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

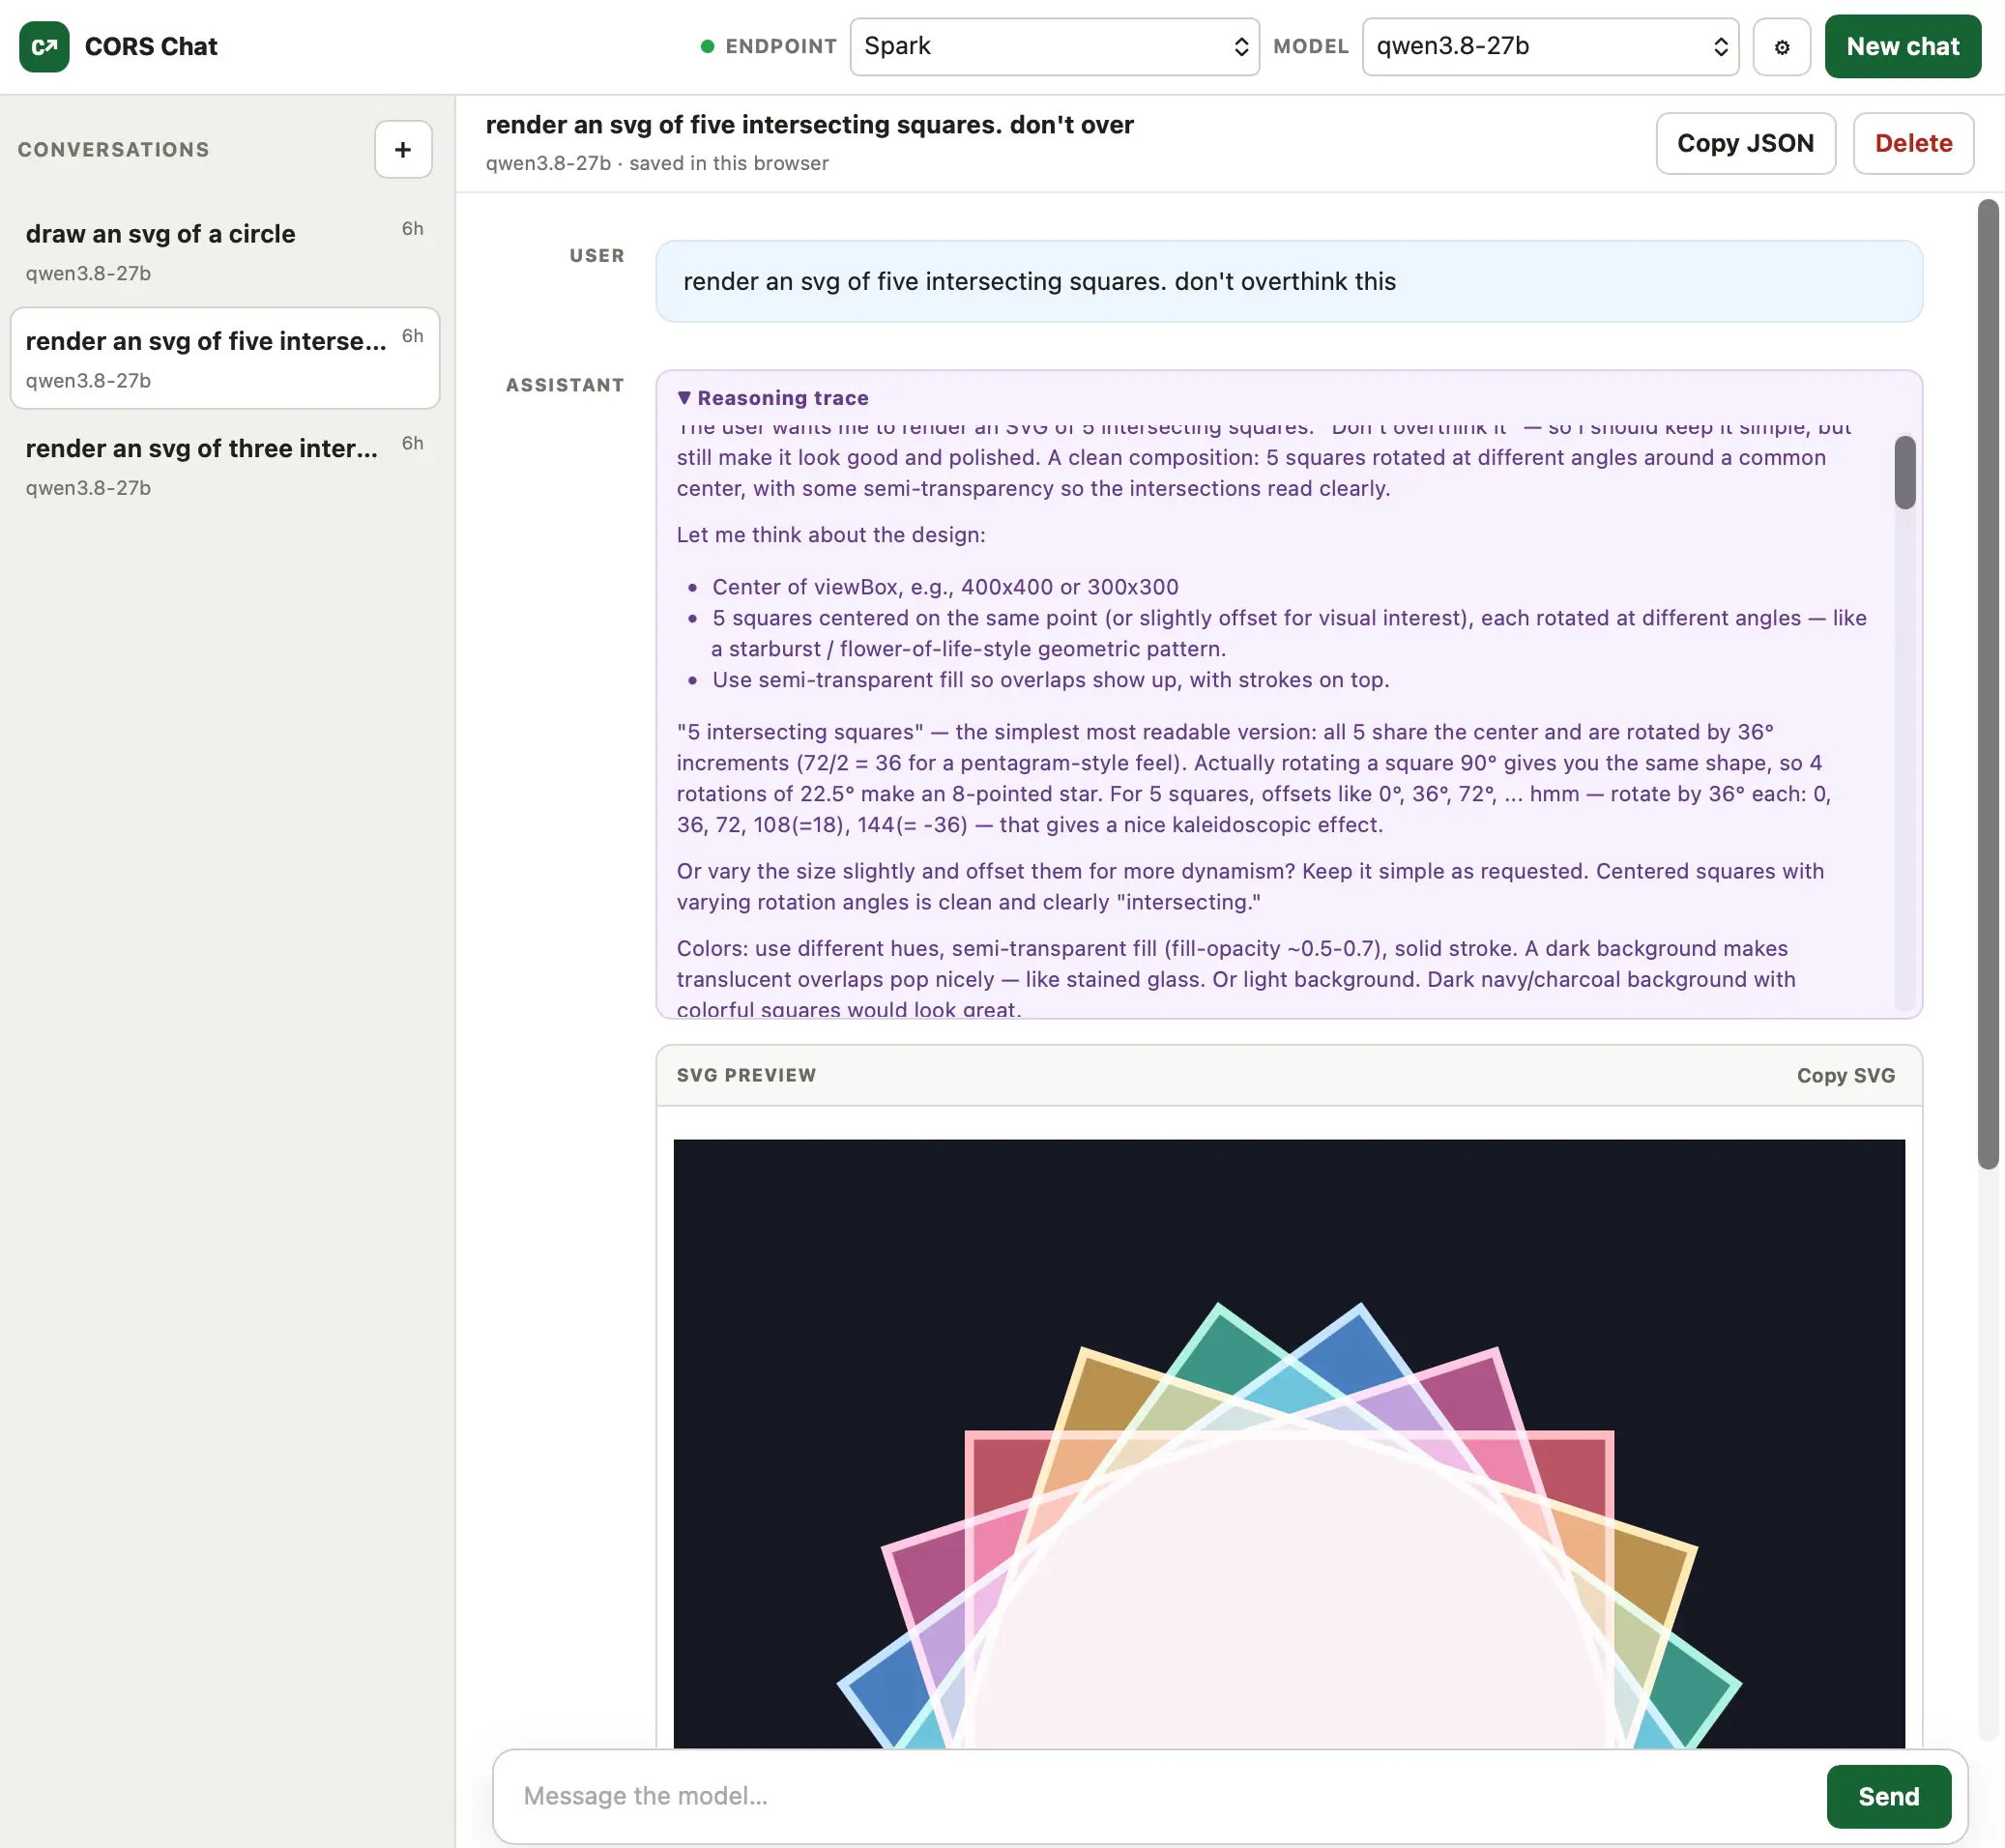
ローカルLLM検証用Web UI「CORS Chat」を公開CORS Chat

重要度 InfoInformational深掘り候補 · 技術記事 · Local LLM / Open ModelsDeep-dive candidate · technical post · Local LLM / Open Models

AI要約CORS ChatはOpenAI Responses形式のチャットAPIを操作できるWeb UIとして公開され、LM Studio上のQwen 3.8 27BをM5 MacBook ProとNVIDIA DGX Sparkで試す開発者のローカルLLM検証を容易にする。

AI SUMMARYCORS Chat adds a browser UI for OpenAI Responses-style chat APIs, tested with Qwen 3.8 27B in LM Studio on an M5 MacBook Pro and NVIDIA DGX Spark, easing local LLM checks.

CORS Chat
コミュニティCommunityLocal Models·Zenn AI

AI主権は「国産LLM」だけでは決まらない──半導体サプライチェーンから考える日本の勝ち筋Japan's AI sovereignty debate tends to focus on domestic LLMs, but this…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約AI主権の確立にはモデル開発だけでなく、半導体製造・装置・材料・電力・人材まで含むサプライチェーン全体の視点が必要であり、TSMCの熊本進出やRapidusの取り組みを踏まえて日本の競争優位を整理した論考。

AI SUMMARYJapan's AI sovereignty debate tends to focus on domestic LLMs, but this analysis argues the real challenge spans the full semiconductor supply chain—from fabrication equipment and materials to power and talent—examining TSMC's Kumamoto plant and Rapidus as key strategic factors.

AI主権は「国産LLM」だけでは決まらない──半導体サプライチェーンから考える日本の勝ち筋
コミュニティCommunityLocal Models·Zenn AI

境界意識:人間とLLMのインタラクションのための概念的フレームワークBoundary Consciousness: A Conceptual Framework for Human–LLM Interacti

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMが「意識」や「意図」を持つかどうかという議論を超え、人間とLLMの相互作用を「境界」という概念で捉え直す理論的枠組みを提案した論文草稿。

AI SUMMARYA theoretical paper proposing a conceptual framework called Boundary Consciousness, reframing human–LLM interaction around the notion of boundaries rather than debating whether LLMs possess consciousness or intent.

Boundary Consciousness: A Conceptual Framework for Human–LLM Interacti
報道NewsNews/Policy·TechCrunch

マーク・ザッカーバーグはAIが「誰のためのもの」と本当に信じているのか?Does Mark Zuckerberg really believe AI is ‘for everyone’?

重要度 MediumMedium priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約MetaがオープンウェイトAIモデル「Glimmer」を公開し、誰でも自分のハードウェアで実行できる一方、強力な「Muse Spark」はAPI経由に限定されており、オープンAIへの姿勢に矛盾があると指摘されている。

AI SUMMARYMeta released Glimmer, an open-weight AI model anyone can self-host, while keeping its more powerful Muse Spark locked behind APIs — raising questions about whether Zuckerberg's 'AI for everyone' rhetoric holds up in practice.

Does Mark Zuckerberg really believe AI is ‘for everyone’?
8/14(金)Fri, Aug 145 entries
🔥 HOT報道NewsNews/Policy·The Verge

AppleはAlibabaと共同で中国向け独自AIモデルを開発Apple trained its own AI model for China with help from Alibaba

重要度 HighHigh priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約Appleが中国市場向けに独自の大規模言語モデルをAlibabaと共同で開発したと報じられた。米中関係が緊張する中での異例の協力であり、中国でのApple Intelligence展開に向けた重要な動きとして注目される。

AI SUMMARYApple reportedly partnered with Alibaba to develop a custom large language model tailored for the Chinese market, marking an unusual cross-border collaboration amid rising US-China tensions and signaling Apple's push to bring AI features to China.

Apple trained its own AI model for China with help from Alibaba
コミュニティCommunityLocal Models·Qiita LLM

LLMのコンテキストウィンドウ枯渇を解決する:履歴圧縮と要約のバックエンドロジックThis article explains backend strategies for handling LLM context window…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約長い会話でLLMのコンテキストウィンドウが溢れる問題に対し、会話履歴を動的に圧縮・要約するバックエンド設計手法を解説した記事。GPT-4やLlama 3などを対象に、実用的な実装パターンを提示している。

AI SUMMARYThis article explains backend strategies for handling LLM context window exhaustion by dynamically compressing and summarizing conversation history, targeting models like GPT-4 and Llama 3.

LLMのコンテキストウィンドウ枯渇を解決する:履歴圧縮と要約のバックエンドロジック
🔥 HOT公式OfficialGemini/Gemma·Google DeepMind Blog

Gemini 3.7 Flash を発表Introducing Gemini 3.7 Flash

重要度 HighHigh priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約GoogleがGemini 3.7 Flashを発表した。高速かつ効率的な新世代モデルとして、幅広いタスクへの対応力と実用性の向上が期待される。

AI SUMMARYGoogle DeepMind announced Gemini 3.7 Flash, a new efficient model in the Gemini lineup designed to deliver fast, capable AI performance across a broad range of tasks.

Introducing Gemini 3.7 Flash
🔥 HOT公式OfficialNews/Policy·Google Keyword Blog

Gemini 3.7 Flash 発表:コーディングとエージェント向け最高性能モデルIntroducing Gemini 3.7 Flash

重要度 HighHigh priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約GoogleはコーディングやAIエージェント用途に特化した新モデル「Gemini 3.7 Flash」を発表した。同社のワークホースモデルとして過去最高の性能を持つとされ、開発者ワークフローの効率化が期待される。

AI SUMMARYGoogle has launched Gemini 3.7 Flash, its most capable workhorse model to date, optimized for coding tasks and AI agent workflows, marking a significant step up in the Flash model line.

Introducing Gemini 3.7 Flash
コミュニティCommunityLocal Models·Qiita LLM

LLM の性能は prefill と decode で決まり方が違うThis article explains that LLM inference performance is governed by…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLM の推論において、入力をまとめて処理する prefill と 1 トークンずつ生成する decode では性能のボトルネックが異なり、最適化の戦略も変わる点を解説した記事。

AI SUMMARYThis article explains that LLM inference performance is governed by fundamentally different bottlenecks in the prefill and decode phases, meaning GPU speed or quantization alone cannot be evaluated without considering which phase dominates.

LLM の性能は prefill と decode で決まり方が違う
8/13(木)Thu, Aug 134 entries
コミュニティCommunityLocal Models·Zenn LLM

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話A new Udemy course on local LLM deployment using llama.cpp has launched,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約社内機密や顧客データをクラウドAIに渡せない課題を背景に、llama.cppを使ったローカルLLM構築をGPU・KVキャッシュ・RAGまで体系的に学べるUdemy講座が公開された。

AI SUMMARYA new Udemy course on local LLM deployment using llama.cpp has launched, addressing the common workplace challenge of handling confidential data that cannot be sent to cloud AI services, covering GPU usage, context management, KV cache, and RAG.

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話
コミュニティCommunityLocal Models·Qiita LLM

モデルを4分の1に圧縮しても、賢さはほぼ落ちないQuantizing LLM weights to 4-bit precision relieves memory-bandwidth…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約量子化によりLLMの重みを4ビットに削減すると、メモリ帯域のボトルネックが解消されコストと推論レイテンシを同時に低減できる一方、精度の低下はほぼ無視できる水準に抑えられる。

AI SUMMARYQuantizing LLM weights to 4-bit precision relieves memory-bandwidth bottlenecks, cutting both inference cost and latency with minimal degradation in model quality.

モデルを4分の1に圧縮しても、賢さはほぼ落ちない
コミュニティCommunityLocal Models·Qiita LLM

RTX 4090 × 4枚で Qwen3.6-27B ファインチューン「Fable-Fusion-711」を vLLM (Docker) で動かす — ハイブリッド構成の KV 設計までThis article walks through running the Qwen3.6-27B community fine-tune…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DavidAU 氏による Qwen3.6-27B のコミュニティファインチューン「Fable-Fusion-711」を、RTX 4090 4枚構成で vLLM (Docker) を使って実行する手順と、ハイブリッド構成向けの KV キャッシュ設計を解説した記事です。

AI SUMMARYThis article walks through running the Qwen3.6-27B community fine-tune "Fable-Fusion-711" — which outperforms the base model on 6 of 7 benchmarks including ARC-C — on a four-GPU RTX 4090 setup via vLLM in Docker, covering KV cache design for hybrid configurations.

RTX 4090 × 4枚で Qwen3.6-27B ファインチューン「Fable-Fusion-711」を vLLM (Docker) で動かす — ハイブリッド構成の KV 設計まで
コミュニティCommunityLocal Models·Simon Willison's Weblog

DeepSeek V4 Pro 0813がOpenRouter経由で利用可能にDeepSeek V4 Pro 0813 (on OpenRouter)

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeekの最新モデルV4 Pro 0813がAPI限定で公開され、OpenRouter経由でアクセス可能となった。オープンウェイト公開の予定は未確認。

AI SUMMARYDeepSeek V4 Pro 0813 is now accessible via API through OpenRouter, though DeepSeek has no official announcement page and open-weights release plans remain unconfirmed.

DeepSeek V4 Pro 0813 (on OpenRouter)
8/12(水)Wed, Aug 121 entries
コミュニティCommunityLocal Models·Zenn AI

賛成3vs反対3のLLMディベートで陣営内均質化(stance homogenization)を確かめたAn experiment pitting three pro-LLM agents against three con-LLM agents…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約固定陣営型のLLMディベートを検証した結果、役割ラベルだけでは発言が同一内容に収束する「stance homogenization」が生じ、多様な意見を引き出すには各役に個別の利害を与える必要があることが示された。

AI SUMMARYAn experiment pitting three pro-LLM agents against three con-LLM agents revealed that role labels alone cause intra-side stance homogenization; genuine diversity requires assigning distinct individual stakes to each agent.

賛成3vs反対3のLLMディベートで陣営内均質化(stance homogenization)を確かめた