Home›Tags›#open-model›Page 2

Tag timeline

#open-modelpage 2/5

同じキーワードで束ねられた更新の続きです。カテゴリをまたいだ関連ニュースや実装トピックの追跡に使えます。

Total121#open-model の全掲載記事All listed entries tagged #open-model
Showing30このページの件数Entries on this page
Page2/5静的ページ位置Static page position
Updated一覧の更新時刻List last updated

Entriespage 2/5 · 121 total

8/17(月)Mon, Aug 172 entries
コミュニティCommunityLocal Models·Zenn AI

実際どれだけ速くなる? Gemma-4のMTPを、普段使いのPCでllama.cpp検証してみたThis article benchmarks Gemma-4's multi-token prediction (MTP) running on…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Gemma-4のマルチトークン予測(MTP)をllama.cpp上で実際に動かし、一般的な家庭用PC環境での速度向上効果を実測データで検証した記事。理論上の利点が現実のハードウェアでどこまで発揮されるかを明らかにしている。

AI SUMMARYThis article benchmarks Gemma-4's multi-token prediction (MTP) running on llama.cpp in a typical consumer PC environment, providing real-world measurement data to show how much of the theoretical speed gain actually materializes.
実際どれだけ速くなる? Gemma-4のMTPを、普段使いのPCでllama.cpp検証してみた
コミュニティCommunityLocal Models·Simon Willison's Weblog

Qwen 3.8 27Bは優秀だが、デフォルトで過剰な思考をするQwen 3.8 27B is excellent, but it defaults to wildly overthinking things

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約AlibabaのQwen研究室がApache 2ライセンスのビジョン対応27Bモデル「Qwen 3.8 27B」をリリース。ラップトップで動作する優れたサイズだが、デフォルトで過剰な推論を行う傾向がある点に注意が必要。

AI SUMMARYAlibaba's Qwen lab released Qwen 3.8 27B, an Apache 2 licensed vision-capable model well-suited for laptop inference, though its tendency to overthink by default is a notable caveat for practical use.

Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
8/16(日)Sun, Aug 163 entries
コミュニティCommunityLocal Models·Zenn LLM

Qwen3.8 27B に Reasoning Effort を実装してみるThe author resolved Qwen3.8 27B's tendency to over-think on ambiguous tasks by…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Qwen3.8 27Bで思考が長引き生成上限に達する問題を、llama.cppのPer-request reasoning budgetで強制打ち切りすることで解消し、曖昧なタスクでも自律的に完走できるようになった。

AI SUMMARYThe author resolved Qwen3.8 27B's tendency to over-think on ambiguous tasks by enabling per-request reasoning budget in llama.cpp, allowing the model to complete complex tasks like Minecraft clone creation autonomously without hitting generation limits.

Qwen3.8 27B に Reasoning Effort を実装してみる
コミュニティCommunityLocal Models·Zenn AI

DeepSeek Harness は Windows で二級市民?根本原因と、欠けていた部品を補った話DeepSeek Harness has significant Windows compatibility issues—including broken…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Windows 環境では DeepSeek Harness のミニマルモード起動やフォルダ選択など複数の機能が動作しない問題が続出しており、著者がその根本原因を特定して独自の回避策を実装した経緯を解説している。

AI SUMMARYDeepSeek Harness has significant Windows compatibility issues—including broken minimal mode and crash-prone folder selection—and this article identifies the root causes and documents the missing pieces the author added to make it functional on Windows.

DeepSeek Harness は Windows で二級市民?根本原因と、欠けていた部品を補った話
コミュニティCommunityLocal Models·Qiita LLM

DeepSeek V4 Pro (0813)をAPIで使って分かった、AIエージェント実装の落とし穴Integrating DeepSeek V4 Pro (0813) into AI agents and tool-calling workflows…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeek V4 Proを単発チャットでなくエージェントやツール呼び出しに組み込む際、思考トークンの扱いや長文出力に起因する実装上の注意点が明らかになった。

AI SUMMARYIntegrating DeepSeek V4 Pro (0813) into AI agents and tool-calling workflows reveals subtle pitfalls—such as handling reasoning tokens and long outputs—that do not surface in simple chat usage.

DeepSeek V4 Pro (0813)をAPIで使って分かった、AIエージェント実装の落とし穴
8/15(土)Sat, Aug 151 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

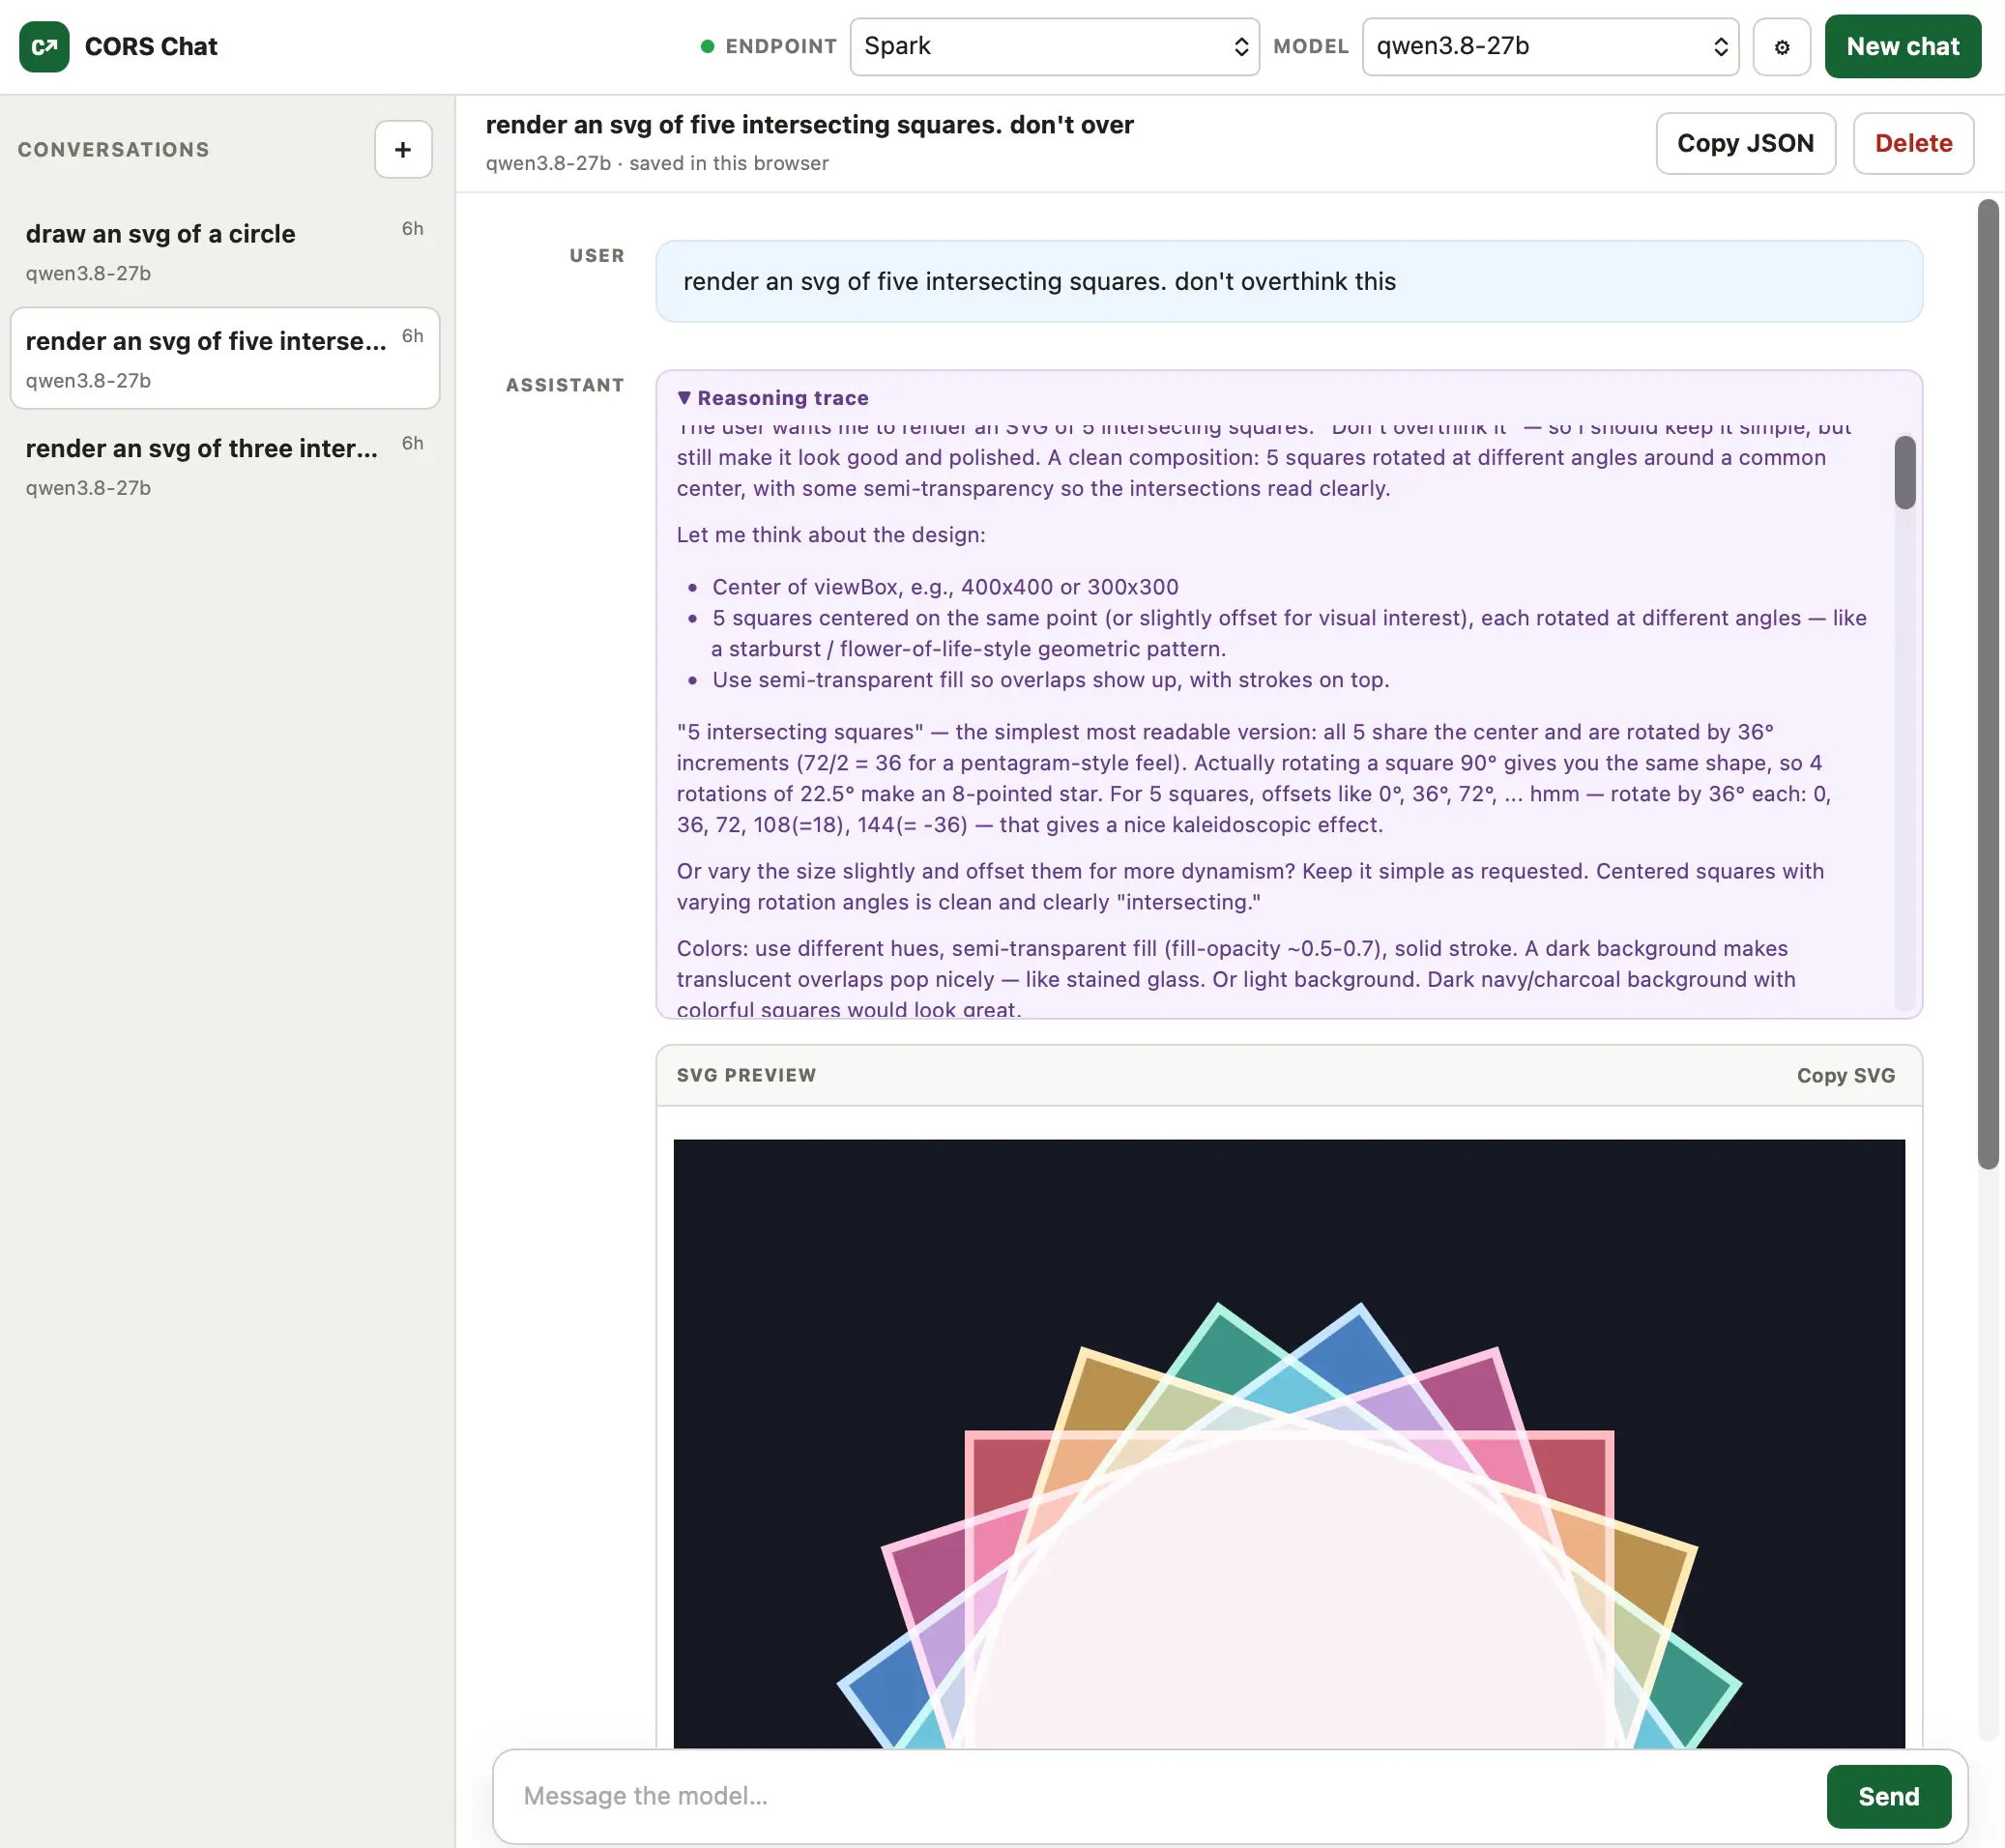
ローカルLLM検証用Web UI「CORS Chat」を公開CORS Chat

重要度 InfoInformational深掘り候補 · 技術記事 · Local LLM / Open ModelsDeep-dive candidate · technical post · Local LLM / Open Models

AI要約CORS ChatはOpenAI Responses形式のチャットAPIを操作できるWeb UIとして公開され、LM Studio上のQwen 3.8 27BをM5 MacBook ProとNVIDIA DGX Sparkで試す開発者のローカルLLM検証を容易にする。

AI SUMMARYCORS Chat adds a browser UI for OpenAI Responses-style chat APIs, tested with Qwen 3.8 27B in LM Studio on an M5 MacBook Pro and NVIDIA DGX Spark, easing local LLM checks.

CORS Chat
8/14(金)Fri, Aug 141 entries
コミュニティCommunityLocal Models·Qiita LLM

LLMのコンテキストウィンドウ枯渇を解決する:履歴圧縮と要約のバックエンドロジックThis article explains backend strategies for handling LLM context window…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約長い会話でLLMのコンテキストウィンドウが溢れる問題に対し、会話履歴を動的に圧縮・要約するバックエンド設計手法を解説した記事。GPT-4やLlama 3などを対象に、実用的な実装パターンを提示している。

AI SUMMARYThis article explains backend strategies for handling LLM context window exhaustion by dynamically compressing and summarizing conversation history, targeting models like GPT-4 and Llama 3.

LLMのコンテキストウィンドウ枯渇を解決する:履歴圧縮と要約のバックエンドロジック
8/13(木)Thu, Aug 133 entries
コミュニティCommunityLocal Models·Zenn LLM

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話A new Udemy course on local LLM deployment using llama.cpp has launched,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約社内機密や顧客データをクラウドAIに渡せない課題を背景に、llama.cppを使ったローカルLLM構築をGPU・KVキャッシュ・RAGまで体系的に学べるUdemy講座が公開された。

AI SUMMARYA new Udemy course on local LLM deployment using llama.cpp has launched, addressing the common workplace challenge of handling confidential data that cannot be sent to cloud AI services, covering GPU usage, context management, KV cache, and RAG.

クラウドAIに入力できない情報をどう扱うか?llama.cppで学ぶローカルLLM入門をUdemyで公開した話
🔥 HOTコミュニティCommunityClaude Code·Zenn Claude

【緊急解説】DeepSeek衝撃の値上げ発表!最新AIモデル価格徹底比較DeepSeek has announced a significant price increase for its DeepSeek-V4 API…

重要度 HighHigh priority技術記事 · Claude / Claude Codetechnical post · Claude / Claude Code

AI要約DeepSeekが旗艦モデルDeepSeek-V4 APIの大幅値上げとピークタイム動的料金制の導入を発表し、「価格破壊の旗手」としての地位から転換。各社AIモデルの最新API価格を徹底比較し、業界への影響を解説する。

AI SUMMARYDeepSeek has announced a significant price increase for its DeepSeek-V4 API along with dynamic peak-time pricing, marking a sharp reversal from its reputation as the industry's cheapest AI provider. The article compares current API prices across major AI models and examines the broader market implications.

【緊急解説】DeepSeek衝撃の値上げ発表!最新AIモデル価格徹底比較
コミュニティCommunityLocal Models·Simon Willison's Weblog

DeepSeek V4 Pro 0813がOpenRouter経由で利用可能にDeepSeek V4 Pro 0813 (on OpenRouter)

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeekの最新モデルV4 Pro 0813がAPI限定で公開され、OpenRouter経由でアクセス可能となった。オープンウェイト公開の予定は未確認。

AI SUMMARYDeepSeek V4 Pro 0813 is now accessible via API through OpenRouter, though DeepSeek has no official announcement page and open-weights release plans remain unconfirmed.

DeepSeek V4 Pro 0813 (on OpenRouter)
8/11(火)Tue, Aug 112 entries
公式OfficialNews/Policy·NVIDIA Blog

NVIDIA Nemotron 3.5 Lightning と NeMo Switchyard がより高速・高効率なエージェント AI を実現NVIDIA Nemotron 3.5 Lightning and NeMo Switchyard Deliver Faster, Smarter, More Efficient Agentic AI

重要度 MediumMedium priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約NVIDIAはNemotron 3モデルファミリーを拡張し、効率性を重視したNemotron 3.5 Lightningと、エージェントAIのオーケストレーションを支援するNeMo Switchyardを発表した。自律型AIエージェントの需要拡大に応える。

AI SUMMARYNVIDIA expanded its Nemotron 3 model family with Nemotron 3.5 Lightning, its highest-efficiency model yet, alongside NeMo Switchyard for agentic AI orchestration, targeting enterprises that need full control over AI deployment.

NVIDIA Nemotron 3.5 Lightning and NeMo Switchyard Deliver Faster, Smarter, More Efficient Agentic AI
公式OfficialGemini/Gemma·Google Developers Blog

LiteRTとGemmaでRaspberry Piのエッジ AIをマスターするMastering Edge AI on Raspberry Pi with LiteRT and Gemma

重要度 MediumMedium priority技術記事 · Gemini / Gemmatechnical post · Gemini / Gemma

AI要約LiteRTと軽量なGemmaオープンモデルを組み合わせることで、Raspberry Pi上でのセキュアなリアルタイムエッジAIの展開が容易になり、ロボティクスなどの用途でローカル推論が実用的な速度で動作する。

AI SUMMARYLiteRT paired with lightweight Gemma open models simplifies deploying real-time Edge AI on Raspberry Pi, optimizing CPU/GPU performance to achieve practical token speeds for local reasoning in robotics and similar applications.

Mastering Edge AI on Raspberry Pi with LiteRT and Gemma
8/6(木)Thu, Aug 61 entries
コミュニティCommunityLocal Models·Qiita LLM

119Bなのに実質6.5B!Mistral Small 4が示すOSS LLM新基準Mistral Small 4 achieves effective inference at roughly 6.5B active parameters…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Mistral Small 4は総パラメータ119Bながら、MoE構造により推論時の実効パラメータが約6.5B相当となり、軽量動作と高性能を両立するOSSモデルの新たな基準を示した。

AI SUMMARYMistral Small 4 achieves effective inference at roughly 6.5B active parameters despite a 119B total parameter count via a MoE architecture, setting a new benchmark for efficient open-source LLMs.

119Bなのに実質6.5B!Mistral Small 4が示すOSS LLM新基準
8/5(水)Wed, Aug 51 entries
🔥 HOT公式OfficialNews/Policy·NVIDIA Blog

NVIDIAのロボタクシー・自動運転向けフロンティアオープンモデル「Alpamayo 2 Super」が商用利用可能にNVIDIA Alpamayo 2 Super, the Frontier Open Model for Robotaxis and Autonomous Vehicles, Now Available for Commercial Use

重要度 HighHigh priority技術記事 · Industry & Policytechnical post · Industry & Policy

AI要約NVIDIAは自動運転車のロングテールシナリオ対応を強化するオープンモデル「Alpamayo 2 Super」を商用利用向けに公開した。日常的な場面だけでなく、予測困難な複雑な状況への対処能力が向上している。

AI SUMMARYNVIDIA has released Alpamayo 2 Super, a frontier open model for robotaxis and autonomous vehicles, for commercial use. The model targets long-tail edge cases that are rare and difficult to anticipate, going beyond basic object detection and motion prediction.

NVIDIA Alpamayo 2 Super, the Frontier Open Model for Robotaxis and Autonomous Vehicles, Now Available for Commercial Use
8/3(月)Mon, Aug 31 entries
コミュニティCommunityLocal Models·Qiita LLM

DeepSeek-V4がKVキャッシュを10分の1に減らせたCSAとHCAの設計DeepSeek-V4 addresses the memory bottleneck of KV caches in long-context LLMs…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約長文脈LLMにおけるKVキャッシュのメモリ肥大化問題に対し、DeepSeek-V4はCSAとHCAという2つのアーキテクチャ設計でキャッシュ量を従来比10分の1に抑えることに成功した。

AI SUMMARYDeepSeek-V4 addresses the memory bottleneck of KV caches in long-context LLMs by introducing CSA and HCA architectural designs that reduce cache size to one-tenth of conventional approaches, significantly improving throughput.

DeepSeek-V4がKVキャッシュを10分の1に減らせたCSAとHCAの設計
8/2(日)Sun, Aug 22 entries
コミュニティCommunityLocal Models·Zenn LLM

Qwen 35Bの品質を7つの質問で採点したら、GPT-4に勝てるのは3領域だけだったA hands-on benchmark pitting locally-run Qwen 35B against GPT-4 across seven…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 4070でQwen 35Bをローカル動作させ、7項目の質問で GPT-4と比較採点した結果、3領域では明確に優位に立てることが判明した。「賢いモデルほど汎用的」という常識とは別に、ローカルLLMが実用的に刺さる用途が存在することを示している。

AI SUMMARYA hands-on benchmark pitting locally-run Qwen 35B against GPT-4 across seven questions found that the open model wins in exactly three domains, challenging the assumption that local LLMs are purely for experimentation and highlighting specific practical use cases for consumer-grade GPUs.

Qwen 35Bの品質を7つの質問で採点したら、GPT-4に勝てるのは3領域だけだった
🔥 HOTコミュニティCommunityLocal Models·Qiita LLM

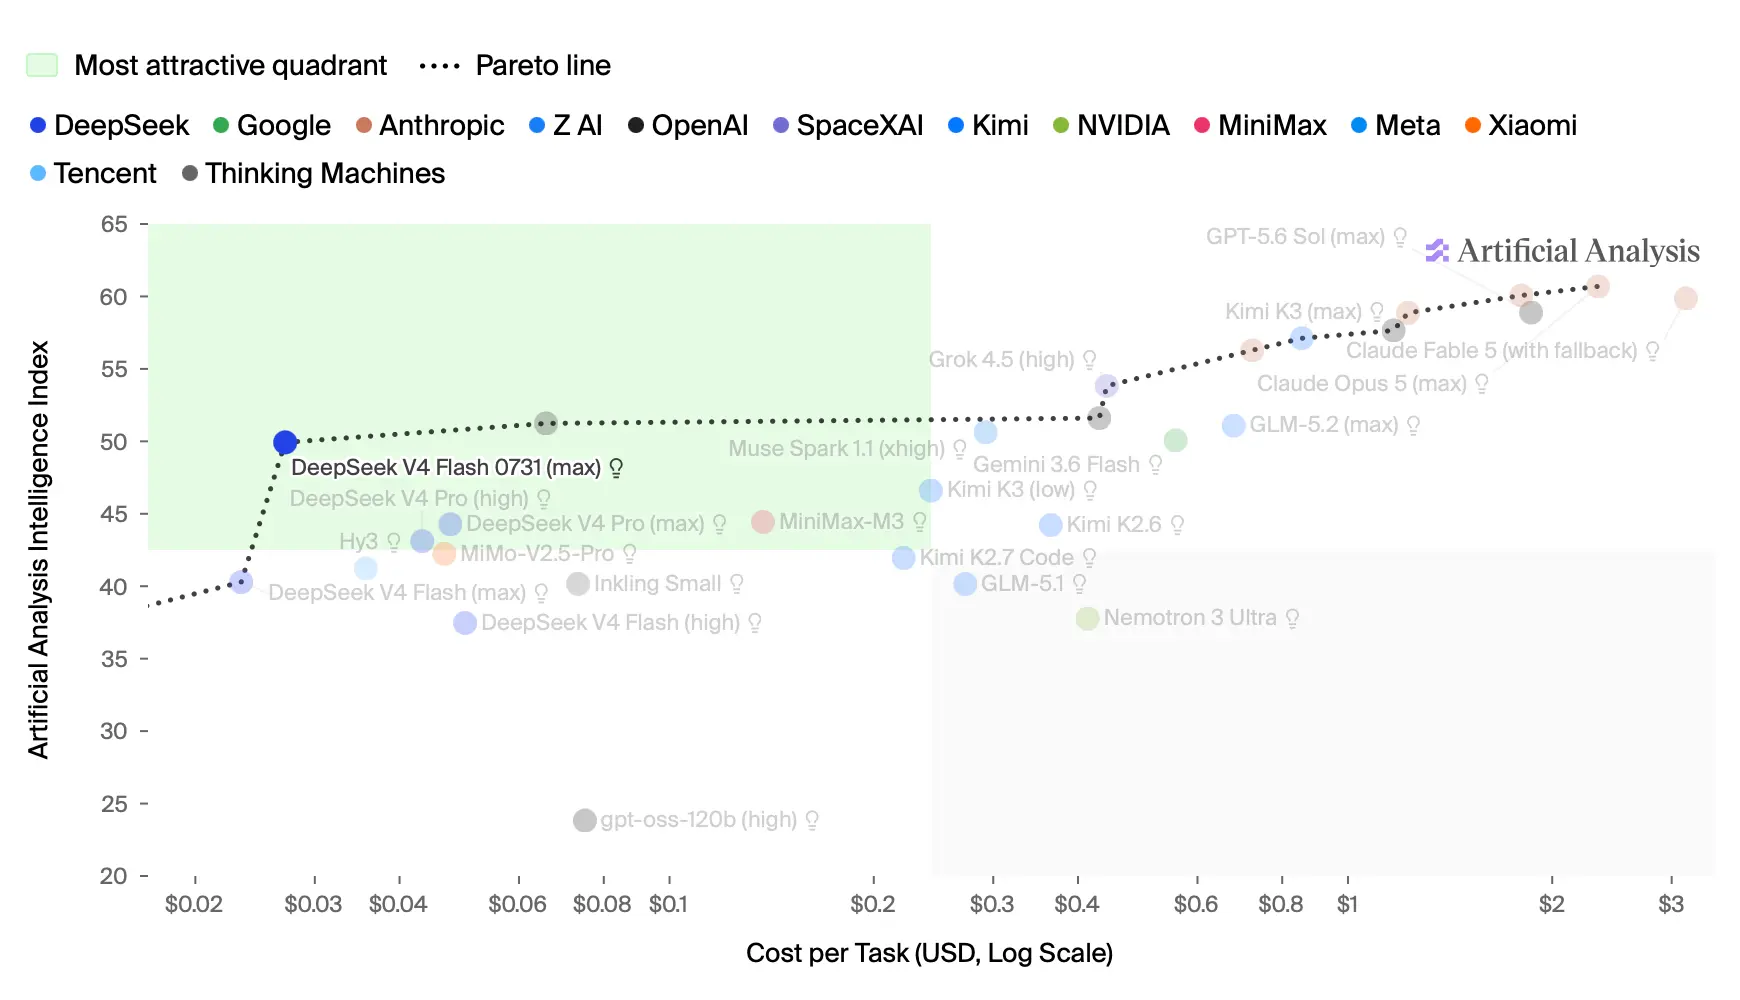
DeepSeek V4-Flash アップデート、超低価格でトップスコアを叩き出すDeepSeek released V4-Flash as an open-weight model under the MIT license,…

重要度 HighHigh priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeek が V4-Flash 正式版をオープンウェイト・MIT ライセンスで公開し、Artificial Analysis の知能指数 50 超を記録しながら業界最安水準の価格を同時に実現した。コストと性能の両立という点で注目度が高い。

AI SUMMARYDeepSeek released V4-Flash as an open-weight model under the MIT license, achieving an Artificial Analysis intelligence index above 50 while offering some of the lowest prices in the market, making high performance and low cost simultaneously viable.

DeepSeek V4-Flash アップデート、超低価格でトップスコアを叩き出す
8/1(土)Sat, Aug 11 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

DeepSeek V4 Flashの新モデル「DeepSeek-V4-Flash-0731」公開deepseek-ai/DeepSeek-V4-Flash-0731

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約DeepSeekがV4ファミリーの最新モデルを公開。3040億パラメータ(167GB)ながらエージェント能力が大幅強化され、Artificial AnalysisではMiniMax M3を上回る評価を獲得している。

AI SUMMARYDeepSeek released DeepSeek-V4-Flash-0731, a 304-billion-parameter open model (167GB) with substantially enhanced agentic capabilities that benchmarks above its weight class, surpassing MiniMax M3 on Artificial Analysis rankings.

deepseek-ai/DeepSeek-V4-Flash-0731
7/31(金)Fri, Jul 314 entries
コミュニティCommunityLocal Models·Qiita LLM

Qwen 35Bは平均42Wで動く — RTX 4070の消費電力プロファイルを推論中に4パターン実測Benchmark measurements of Qwen 35B running on an RTX 4070 show average GPU…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約RTX 4070上でQwen 35Bを動作させた際の消費電力を実測した結果、デコード中の平均はわずか42Wで、ピーク時でも175Wにとどまることが確認された。ローカルLLM運用時の電力コスト見積もりに役立つ具体的なデータとして注目される。

AI SUMMARYBenchmark measurements of Qwen 35B running on an RTX 4070 show average GPU power of only 42 W during decode, with prompt-eval peaks reaching 175 W, well below the card's 200 W TGP. These real-world power profiles offer useful reference data for estimating electricity costs of local LLM deployments.

Qwen 35Bは平均42Wで動く — RTX 4070の消費電力プロファイルを推論中に4パターン実測
コミュニティCommunityCopilot·Qiita GitHub Copilot

Mistral Vibe比較 — Claude Code・Codexより安いのに強い理由と落とし穴A practical comparison of Mistral's vibe-coding capability against Claude Code…

重要度 MediumMedium priority技術記事 · GitHub Copilottechnical post · GitHub Copilot

AI要約MistralのVibe Codingツールをコスト面でClaude CodeやCodexと比較し、低価格でも高い実力を発揮できる理由と注意すべき弱点を解説した記事。

AI SUMMARYA practical comparison of Mistral's vibe-coding capability against Claude Code and Codex, explaining why Mistral can deliver competitive results at lower cost while highlighting its key limitations.

Mistral Vibe比較 — Claude Code・Codexより安いのに強い理由と落とし穴
コミュニティCommunityLocal Models·Zenn LLM

Jetson Orin Nano Super によるローカルMLLM活用についてA new engineer at Medley shares how they built a local multimodal LLM…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約メドレーの新卒エンジニアがJetson Orin Nano Super上にGemma 4を用いたローカルマルチモーダルLLM環境を構築し、その検証手順と実用性を紹介している。エッジデバイスでのプライバシー重視なAI推論の可能性を示す内容。

AI SUMMARYA new engineer at Medley shares how they built a local multimodal LLM environment using Gemma 4 on the Jetson Orin Nano Super, demonstrating practical edge-device AI inference without cloud dependency.

Jetson Orin Nano Super によるローカルMLLM活用について
コミュニティCommunityLocal Models·Qiita LLM

TensorSharp とは — C# だけで動く GGUF 推論エンジンが llama.cpp に挑むTensorSharp, a pure C# inference engine for GGUF models, has published…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約.NET製推論エンジン「TensorSharp」がGGUFモデルをC#のみで実行し、llama.cppとのベンチマーク結果を公開してローカルLLMコミュニティで注目を集めている。

AI SUMMARYTensorSharp, a pure C# inference engine for GGUF models, has published benchmarks against llama.cpp, demonstrating that .NET can be a viable platform for local LLM inference.

TensorSharp とは — C# だけで動く GGUF 推論エンジンが llama.cpp に挑む
7/29(水)Wed, Jul 291 entries
コミュニティCommunityLocal Models·Zenn LLM

Apple Neural Engine で LLM を、出力を変えずに高速化する — Core ML 投機デコードの実装A Core ML bundle running Gemma 4 E2B on Apple Neural Engine gains lossless…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Gemma 4 E2BをANEで動かすCore MLバンドルに、ドラフトモデル不要のロスレス投機デコードとKVキャッシュのディスク永続化を実装。出力を一切変えずに推論速度を向上させる具体的な手法と実測値を公開した。

AI SUMMARYA Core ML bundle running Gemma 4 E2B on Apple Neural Engine gains lossless speculative decoding—requiring no draft model—and persistent KV cache, improving inference speed without altering outputs by a single byte.

Apple Neural Engine で LLM を、出力を変えずに高速化する — Core ML 投機デコードの実装
7/28(火)Tue, Jul 283 entries
コミュニティCommunityLocal Models·Zenn LLM

NVIDIA DGX Spark でソフトウェア開発に最適な Gemma 4 モデルを検証する (31B vs 26B)The article benchmarks Gemma 4's 31B and 26B models on NVIDIA DGX Spark for…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約NVIDIA DGX Spark 上で Gemma 4 の 31B と 26B モデルをソフトウェア開発タスクで比較検証し、用途に応じた最適モデルの選び方を考察した記事。

AI SUMMARYThe article benchmarks Gemma 4's 31B and 26B models on NVIDIA DGX Spark for software development tasks, helping developers choose the right model size for local deployment.

NVIDIA DGX Spark でソフトウェア開発に最適な Gemma 4 モデルを検証する (31B vs 26B)
論文PaperPapers/Benchmarks·arXiv cs.LG

Semalith v1.4: Llama-Guard-3-8Bの44分の1のパラメータ数で最先端のプロンプトインジェクション検出を実現した184Mキャリブレーション済み安全分類器Semalith v1.4: A Calibrated 184M Safety Classifier Achieving State-of-the-Art Prompt-Injection Detection at 44x Fewer Parameters than Llama-Guard-3-8B

重要度 MediumMedium priority論文/研究 · Papers / Benchmarkspaper/research · Papers / Benchmarks

AI要約Semalith v1.4は1億8400万パラメータの軽量安全分類器で、Llama-Guard-3-8Bの44分の1のサイズながらプロンプトインジェクション検出で同等以上の精度を達成した。小規模モデルでも高精度な安全フィルタリングが可能であることを示し、実用的なデプロイコストの大幅削減につながる。

AI SUMMARYSemalith v1.4 is a 184M-parameter safety classifier that matches or surpasses Llama-Guard-3-8B on prompt-injection detection while using 44x fewer parameters. This demonstrates that highly capable safety filtering can be achieved at a fraction of the computational cost, making deployment far more practical.

Semalith v1.4: A Calibrated 184M Safety Classifier Achieving State-of-the-Art Prompt-Injection Detection at 44x Fewer Parameters than Llama-Guard-3-8B
コミュニティCommunityLocal Models·Qiita LLM

RGBカメラ1台でロボットを動かすMistralのRobostral NavigateMistral introduced Robostral Navigate, a model enabling robot navigation using…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約MistralがRGBカメラ1台の映像だけでロボットのナビゲーションを実現する「Robostral Navigate」を発表。深度センサーや複雑なセンサー構成なしにビジョンベースの自律移動が可能になる点が注目される。

AI SUMMARYMistral introduced Robostral Navigate, a model enabling robot navigation using only a single RGB camera feed. This lowers the hardware barrier for autonomous robotics by eliminating the need for depth sensors or multi-sensor rigs.

RGBカメラ1台でロボットを動かすMistralのRobostral Navigate
7/26(日)Sun, Jul 262 entries
コミュニティCommunityLocal Models·Zenn LLM

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違いAn investigation into why perplexity scores diverged between llama.cpp and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約GGUF形式で互換性があるはずのモデルでも、llama.cpp と他実装でパープレキシティが一致しない原因をLayer 0まで追跡した結果、テンソル演算の経路の違いが数値誤差を生むことが判明した。推論再現性を重視する開発者にとって重要な知見。

AI SUMMARYAn investigation into why perplexity scores diverged between llama.cpp and another GGUF-compatible runtime traced the root cause to differences in tensor computation paths at Layer 0, revealing that format compatibility alone does not guarantee numerical reproducibility.

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違い
コミュニティCommunityLocal Models·Qiita LLM

Kimi-K2.6、Qwen3.6、gemma-4、勝つのはどれだ!無料オープンLLM対決!A benchmark comparison of three freely available open LLMs—Kimi-K2.6, Qwen3.6,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約無料で利用できるオープンLLMであるKimi-K2.6、Qwen3.6、gemma-4を複数のベンチマークで比較し、それぞれの強みと実用性を検証した記事です。

AI SUMMARYA benchmark comparison of three freely available open LLMs—Kimi-K2.6, Qwen3.6, and Gemma-4—evaluating their strengths and practical performance to help users choose the best model.

Kimi-K2.6、Qwen3.6、gemma-4、勝つのはどれだ!無料オープンLLM対決!
7/25(土)Sat, Jul 252 entries
コミュニティCommunityLocal Models·Zenn LLM

非力なGPUでローカルLLMは動くか――Gemma 4 E2B QATの実験環境とPythonコードを公開A developer shares a reproducible experiment running Gemma 4 E2B QAT on a…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約低スペックGPU環境でGemma 4 E2B QATモデルを動作させる実験を行い、その環境構成と再現可能なPythonコードを公開。手頃なハードウェアでローカルLLMを活用できる可能性を示した。

AI SUMMARYA developer shares a reproducible experiment running Gemma 4 E2B QAT on a low-end GPU, publishing the full environment setup and Python code to help others run local LLMs on modest hardware.

非力なGPUでローカルLLMは動くか――Gemma 4 E2B QATの実験環境とPythonコードを公開
コミュニティCommunityLocal Models·Zenn LLM

Gemma 4 12BをiPhoneで投機デコードする:2.4倍高速化とA19最適化This article details how speculative decoding applied to Gemma 4 12B on Apple's…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約iPhoneのA19チップ上でGemma 4 12Bを動作させる際に投機的デコードを適用し、推論速度を最大2.4倍改善した手法を解説した記事。エッジデバイスでの大規模モデル実用化に向けた具体的な最適化アプローチとして注目される。

AI SUMMARYThis article details how speculative decoding applied to Gemma 4 12B on Apple's A19 chip achieves up to 2.4× inference speedup on iPhone, offering practical techniques for running large models efficiently on edge devices.

Gemma 4 12BをiPhoneで投機デコードする:2.4倍高速化とA19最適化