Category detail

Local LLM / Open Modelspage 6/8

Local LLM / Open Models カテゴリの更新の続きです。ページを移動してもカテゴリ文脈と主要指標を維持します。Continue browsing Local LLM / Open Models updates while keeping category context and key metrics in view.

Total238現在のカテゴリ一覧Current category listing
Showing30このページの件数Entries on this page
Last 7d15直近7日の掲載数Entries in the latest 7 days
Vs prev 7d+200%その前の7日間と比較Compared with the previous 7 days
Page6/8静的ページ位置Static page position

All articlespage 6/8 · 238 total

新着順Newest first
7/29(水)Wed, Jul 295 entries
🔥 HOTコミュニティCommunityLocal Models·Zenn LLM

Kimi K3は何が公開されたのか:2.8兆パラメータと約1.56TBの意味Moonshot AI released full weights of Kimi K3, a 2.8 trillion-parameter LLM, on…

重要度 HighHigh priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Moonshot AIが2.8兆パラメータのKimi K3をHugging Faceでフルウェイト公開し、総容量は約1.56TBに達するが、一般的なPCで実用速度での動作は現実的ではない点に注意が必要だ。

AI SUMMARYMoonshot AI released full weights of Kimi K3, a 2.8 trillion-parameter LLM, on Hugging Face at roughly 1.56 TB total — making local storage feasible but practical inference on consumer hardware currently unrealistic.

Kimi K3は何が公開されたのか:2.8兆パラメータと約1.56TBの意味
コミュニティCommunityLocal Models·Zenn LLM

Local LLM で画像の PII マスキングを試してみたA practical experiment using local LLMs to mask PII in images found that…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約ローカルLLMを活用して画像内の個人情報をマスキングする手法を検証し、LLMの適用範囲をテキスト部分に絞ることで実用的な処理速度を達成できることを示した。

AI SUMMARYA practical experiment using local LLMs to mask PII in images found that limiting LLM processing to text regions achieves viable performance, making privacy-safe document handling more feasible.

Local LLM で画像の PII マスキングを試してみた
コミュニティCommunityLocal Models·Zenn LLM

Apple Neural Engine で LLM を、出力を変えずに高速化する — Core ML 投機デコードの実装A Core ML bundle running Gemma 4 E2B on Apple Neural Engine gains lossless…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Gemma 4 E2BをANEで動かすCore MLバンドルに、ドラフトモデル不要のロスレス投機デコードとKVキャッシュのディスク永続化を実装。出力を一切変えずに推論速度を向上させる具体的な手法と実測値を公開した。

AI SUMMARYA Core ML bundle running Gemma 4 E2B on Apple Neural Engine gains lossless speculative decoding—requiring no draft model—and persistent KV cache, improving inference speed without altering outputs by a single byte.

Apple Neural Engine で LLM を、出力を変えずに高速化する — Core ML 投機デコードの実装
コミュニティCommunityLocal Models·Zenn LLM

LangGraphでエージェント暴走を防ぐ設計チェックリストAs the AI landscape shifts from model benchmarking to agent operations and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約AIの競争軸がモデル性能からエージェント運用と安全統制に移行する中、LangGraphを用いたエージェント設計で先に押さえるべき安全要件とチェックリストをまとめた実務向け記事。

AI SUMMARYAs the AI landscape shifts from model benchmarking to agent operations and safety governance, this article provides a practical checklist of security and control requirements to address upfront when building LangGraph-based agents.

LangGraphでエージェント暴走を防ぐ設計チェックリスト
コミュニティCommunityLocal Models·Zenn LLM

その公開MLX変換、本当に動きますか。使えない変換を実測で見分けるEven models published on Hugging Face as MLX conversions can be broken — one…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Hugging Faceに「MLX変換済み」として公開されているモデルでも、ロード不能や全文字化けといった致命的な不具合を抱える例があり、著者がBaiduのOCRモデルを題材に既存変換2種を実測して問題を明らかにした。重みファイルが生成できても正常動作するとは限らず、実測による検証が不可欠だと示している。

AI SUMMARYEven models published on Hugging Face as MLX conversions can be broken — one failing to load and another producing garbled output — as the author discovered when benchmarking two existing conversions of Baidu's Unlimited-OCR (3.3B, MIT). The article argues that generating weight files does not guarantee a working model, and only empirical testing can confirm usability.

その公開MLX変換、本当に動きますか。使えない変換を実測で見分ける
7/28(火)Tue, Jul 285 entries
コミュニティCommunityLocal Models·Qiita LLM

[2026年版]最新Open LLMのアーキテクチャ総整理(Kimi K3, GLM-5.2, etc.)A 2026 survey comparing the architectures of leading open LLMs including Kimi…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Kimi K3やGLM-5.2など2026年時点の主要オープンLLMのアーキテクチャを横断的に比較・整理した記事。各モデルの設計上の特徴と違いを把握することで、用途に合ったモデル選定の判断材料となる。

AI SUMMARYA 2026 survey comparing the architectures of leading open LLMs including Kimi K3 and GLM-5.2, highlighting structural differences that matter for model selection and deployment.

[2026年版]最新Open LLMのアーキテクチャ総整理(Kimi K3, GLM-5.2, etc.)
コミュニティCommunityLocal Models·Zenn LLM

NVIDIA DGX Spark でソフトウェア開発に最適な Gemma 4 モデルを検証する (31B vs 26B)The article benchmarks Gemma 4's 31B and 26B models on NVIDIA DGX Spark for…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約NVIDIA DGX Spark 上で Gemma 4 の 31B と 26B モデルをソフトウェア開発タスクで比較検証し、用途に応じた最適モデルの選び方を考察した記事。

AI SUMMARYThe article benchmarks Gemma 4's 31B and 26B models on NVIDIA DGX Spark for software development tasks, helping developers choose the right model size for local deployment.

NVIDIA DGX Spark でソフトウェア開発に最適な Gemma 4 モデルを検証する (31B vs 26B)
コミュニティCommunityLocal Models·Zenn LLM

LLMでテキストから知識グラフを自動抽出する手法を動かしてみたThe author implements and evaluates an LLM-based pipeline for automatically…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約LLMを活用してテキストから知識グラフを自動生成する手法を実際に検証し、その精度や実装上の課題を明らかにした記事。RAGや情報整理への応用可能性を示す点で注目に値する。

AI SUMMARYThe author implements and evaluates an LLM-based pipeline for automatically extracting knowledge graphs from text, demonstrating practical feasibility and surfacing key challenges relevant to RAG and structured knowledge applications.

LLMでテキストから知識グラフを自動抽出する手法を動かしてみた
コミュニティCommunityLocal Models·Simon Willison's Weblog

moonshotai/Kimi-K3 ローカル実行ガイドmoonshotai/Kimi-K3

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Moonshot AIが新モデルKimi-K3を公開し、Simon Willisonがローカルでの実行方法を解説。高性能な推論モデルをセルフホストできる点が注目される。

AI SUMMARYMoonshot AI released Kimi-K3, a new reasoning-capable model, and Simon Willison documented how to run it locally, making it accessible for self-hosted LLM workflows.

コミュニティCommunityLocal Models·Qiita LLM

RGBカメラ1台でロボットを動かすMistralのRobostral NavigateMistral introduced Robostral Navigate, a model enabling robot navigation using…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約MistralがRGBカメラ1台の映像だけでロボットのナビゲーションを実現する「Robostral Navigate」を発表。深度センサーや複雑なセンサー構成なしにビジョンベースの自律移動が可能になる点が注目される。

AI SUMMARYMistral introduced Robostral Navigate, a model enabling robot navigation using only a single RGB camera feed. This lowers the hardware barrier for autonomous robotics by eliminating the need for depth sensors or multi-sensor rigs.

RGBカメラ1台でロボットを動かすMistralのRobostral Navigate
7/27(月)Mon, Jul 276 entries
コミュニティCommunityLocal Models·Zenn AI

LLMアプリは「ハーネス」が9割 ── Perl/CGIの現役SaaSにAIエージェントを組み込んで学んだことA developer shares lessons from integrating an AI agent into a legacy Perl/CGI…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約レガシーなPerl/CGI製SaaSにAIエージェントを統合した実践から、LLMアプリ開発の本質はモデルよりも「ハーネス(周辺制御構造)」にあると学んだ知見を共有している。

AI SUMMARYA developer shares lessons from integrating an AI agent into a legacy Perl/CGI SaaS, concluding that the surrounding harness—not the LLM itself—accounts for most of the engineering effort.

LLMアプリは「ハーネス」が9割 ── Perl/CGIの現役SaaSにAIエージェントを組み込んで学んだこと
コミュニティCommunityLocal Models·Zenn LLM

拡散言語モデルとは?LLMが2.42倍速くなる新しい生成の仕組みDiffusion language models generate multiple tokens in parallel rather than one…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約拡散言語モデルは従来の自己回帰型LLMと異なり、複数トークンを並列に生成することで最大2.42倍の推論高速化を実現する新しいアーキテクチャだ。ローカルLLMの実用性向上に直結する技術として注目されている。

AI SUMMARYDiffusion language models generate multiple tokens in parallel rather than one at a time, achieving up to 2.42× faster inference than autoregressive LLMs. This architectural shift could significantly improve the practicality of locally-run language models.

拡散言語モデルとは?LLMが2.42倍速くなる新しい生成の仕組み
コミュニティCommunityLocal Models·Zenn LLM

ローカルLLMにThoughtsStoreを搭載させてみた(実装応用編)This article demonstrates how to integrate a ThoughtsStore into a local LLM…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約ローカルLLMにThoughtsStoreを組み込む応用実装を解説した記事で、思考履歴を永続化することでLLMの推論品質と文脈保持能力を向上させる手法を紹介している。

AI SUMMARYThis article demonstrates how to integrate a ThoughtsStore into a local LLM setup, enabling persistent storage of reasoning traces to improve inference quality and context retention.

ローカルLLMにThoughtsStoreを搭載させてみた(実装応用編)
コミュニティCommunityLocal Models·Zenn LLM

WSL2(Ubuntu 26.04) + docker で Radeon GPU を認識させるThis article explains how to configure WSL2 (Ubuntu 26.04) and Docker to…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約WSL2上のUbuntu 26.04環境でDockerからAMD Radeon GPUを利用可能にする手順を解説した記事で、ローカルLLMをAMD GPU上で動かしたい開発者に役立つ情報を提供している。

AI SUMMARYThis article explains how to configure WSL2 (Ubuntu 26.04) and Docker to recognize AMD Radeon GPUs, enabling local LLM inference on AMD hardware for developers seeking alternatives to NVIDIA.

WSL2(Ubuntu 26.04) + docker で Radeon GPU を認識させる
コミュニティCommunityLocal Models·Zenn LLM

量子化フォーマットを比較する:GGUF・AWQ・GPTQをvLLMで実測するThis article benchmarks GGUF, AWQ, and GPTQ quantization formats on vLLM,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約GGUF・AWQ・GPTQの3つの量子化フォーマットをvLLM上で実際に計測し、推論速度・メモリ使用量・精度の観点から違いを明らかにした記事。ローカルLLM運用における最適なフォーマット選択の指針となる。

AI SUMMARYThis article benchmarks GGUF, AWQ, and GPTQ quantization formats on vLLM, comparing inference speed, memory usage, and accuracy to help practitioners choose the right format for local LLM deployment.

量子化フォーマットを比較する:GGUF・AWQ・GPTQをvLLMで実測する
コミュニティCommunityLocal Models·Zenn LLM

ローカルLLM向けハードウェアを「容量・帯域・MoE・TTFT」で選ぶThis article explains how to choose hardware for running local LLMs by…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約ローカルLLMを快適に動かすには、メモリ容量・メモリ帯域・MoEアーキテクチャへの対応・初回トークン生成速度(TTFT)という4軸でハードウェアを評価することが重要だと解説した記事。GPU・CPUオフロード・専用アクセラレータの選び方に実践的な指針を提供している。

AI SUMMARYThis article explains how to choose hardware for running local LLMs by evaluating four key axes: memory capacity, memory bandwidth, MoE architecture support, and time-to-first-token (TTFT), offering practical guidance for selecting GPUs, CPU offload setups, and dedicated accelerators.

ローカルLLM向けハードウェアを「容量・帯域・MoE・TTFT」で選ぶ
7/26(日)Sun, Jul 264 entries
コミュニティCommunityLocal Models·Zenn LLM

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違いAn investigation into why perplexity scores diverged between llama.cpp and…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約GGUF形式で互換性があるはずのモデルでも、llama.cpp と他実装でパープレキシティが一致しない原因をLayer 0まで追跡した結果、テンソル演算の経路の違いが数値誤差を生むことが判明した。推論再現性を重視する開発者にとって重要な知見。

AI SUMMARYAn investigation into why perplexity scores diverged between llama.cpp and another GGUF-compatible runtime traced the root cause to differences in tensor computation paths at Layer 0, revealing that format compatibility alone does not guarantee numerical reproducibility.

GGUF互換なのに llama.cpp と PPL が一致しなかった──Layer 0まで追って見えた「演算経路」の違い
コミュニティCommunityLocal Models·Qiita LLM

Kimi-K2.6、Qwen3.6、gemma-4、勝つのはどれだ!無料オープンLLM対決!A benchmark comparison of three freely available open LLMs—Kimi-K2.6, Qwen3.6,…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約無料で利用できるオープンLLMであるKimi-K2.6、Qwen3.6、gemma-4を複数のベンチマークで比較し、それぞれの強みと実用性を検証した記事です。

AI SUMMARYA benchmark comparison of three freely available open LLMs—Kimi-K2.6, Qwen3.6, and Gemma-4—evaluating their strengths and practical performance to help users choose the best model.

Kimi-K2.6、Qwen3.6、gemma-4、勝つのはどれだ!無料オープンLLM対決!
コミュニティCommunityLocal Models·Zenn LLM

日本語OCRモデルSarashina2.2-OCRをMLXへ移植する。モデルカードだけでは分からない実装を追った記録This article documents the process of porting the Japanese OCR model…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Sarashina2.2-OCRをApple Silicon向けMLXフレームワークへ移植する際、モデルカードに記載されていない実装の詳細を調査・解決した過程をまとめた記事。ローカル環境で高精度な日本語OCRを動かしたい開発者にとって実践的な参考資料となる。

AI SUMMARYThis article documents the process of porting the Japanese OCR model Sarashina2.2-OCR to the MLX framework for Apple Silicon, uncovering implementation details absent from the official model card. It serves as a practical guide for developers aiming to run high-accuracy Japanese OCR locally.

日本語OCRモデルSarashina2.2-OCRをMLXへ移植する。モデルカードだけでは分からない実装を追った記録
コミュニティCommunityLocal Models·Zenn LLM

LLMの監督モデルはどこまで小さくできるか。9B・35B・自己検査で実測したら三様の結果になったAn empirical study comparing 9B, 35B, and self-check supervision strategies for…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約9B・35B・自己検査という三つの監督モデル構成をローカルLLMで実測比較し、規模や手法によって検証精度が大きく異なることを明らかにした実験報告。監督モデルの最小化を検討する際の実践的な指針となる。

AI SUMMARYAn empirical study comparing 9B, 35B, and self-check supervision strategies for local LLMs found notably different verification accuracy across configurations, offering practical guidance on how small a supervisor model can realistically go.

LLMの監督モデルはどこまで小さくできるか。9B・35B・自己検査で実測したら三様の結果になった
7/25(土)Sat, Jul 253 entries
コミュニティCommunityLocal Models·Zenn LLM

非力なGPUでローカルLLMは動くか――Gemma 4 E2B QATの実験環境とPythonコードを公開A developer shares a reproducible experiment running Gemma 4 E2B QAT on a…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約低スペックGPU環境でGemma 4 E2B QATモデルを動作させる実験を行い、その環境構成と再現可能なPythonコードを公開。手頃なハードウェアでローカルLLMを活用できる可能性を示した。

AI SUMMARYA developer shares a reproducible experiment running Gemma 4 E2B QAT on a low-end GPU, publishing the full environment setup and Python code to help others run local LLMs on modest hardware.

非力なGPUでローカルLLMは動くか――Gemma 4 E2B QATの実験環境とPythonコードを公開
コミュニティCommunityLocal Models·Zenn LLM

Gemma 4 12BをiPhoneで投機デコードする:2.4倍高速化とA19最適化This article details how speculative decoding applied to Gemma 4 12B on Apple's…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約iPhoneのA19チップ上でGemma 4 12Bを動作させる際に投機的デコードを適用し、推論速度を最大2.4倍改善した手法を解説した記事。エッジデバイスでの大規模モデル実用化に向けた具体的な最適化アプローチとして注目される。

AI SUMMARYThis article details how speculative decoding applied to Gemma 4 12B on Apple's A19 chip achieves up to 2.4× inference speedup on iPhone, offering practical techniques for running large models efficiently on edge devices.

Gemma 4 12BをiPhoneで投機デコードする:2.4倍高速化とA19最適化
コミュニティCommunityLocal Models·Zenn LLM

Gemma 4 12B を Core ML で 128K コンテキストで動かすThis article explains how to run Gemma 4 12B with a 128K context window on…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Apple Silicon 上で Core ML を使い Gemma 4 12B を 128K トークンのコンテキスト長で動作させる手順を解説した記事で、ローカル環境での大規模モデル活用の可能性を示している。

AI SUMMARYThis article explains how to run Gemma 4 12B with a 128K context window on Apple Silicon using Core ML, demonstrating that large open models can be deployed locally without cloud infrastructure.

Gemma 4 12B を Core ML で 128K コンテキストで動かす
7/23(木)Thu, Jul 235 entries
コミュニティCommunityLocal Models·Zenn LLM

VRAMに乗らないMoEをNVMe+GPU推論で動かす:Hypura/llama.cpp/TurboQuant解説This article explains how to run large MoE models that exceed VRAM capacity by…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約VRAMに収まらない大規模MoEモデルをNVMeストレージとGPUを組み合わせて実用的に推論する手法を、Hypura・llama.cpp・TurboQuantの三ツールを軸に解説した記事。コンシューマー環境でも巨大モデルを動かせる可能性を示す点で注目に値する。

AI SUMMARYThis article explains how to run large MoE models that exceed VRAM capacity by offloading layers to NVMe storage while leveraging GPU acceleration, using Hypura, llama.cpp, and TurboQuant. It matters because it opens a practical path for running frontier-scale models on consumer hardware.

VRAMに乗らないMoEをNVMe+GPU推論で動かす:Hypura/llama.cpp/TurboQuant解説
コミュニティCommunityLocal Models·Zenn LLM

ollama の入力切り捨てをレスポンスだけで検知する — 3回作り直した記録A practical account of detecting silent input truncation in ollama—where…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約ollama がコンテキスト長を超えた入力を無警告で切り捨てる問題に対し、レスポンスのみを手がかりに切り捨てを検知する手法を3度の試行錯誤を経て確立した実践記録。ローカルLLM運用の信頼性向上に役立つ知見をまとめている。

AI SUMMARYA practical account of detecting silent input truncation in ollama—where prompts exceeding the context window are cut without warning—using only the model response as a signal, refined through three redesigns. The findings help improve reliability when running LLMs locally.

ollama の入力切り捨てをレスポンスだけで検知する — 3回作り直した記録
コミュニティCommunityLocal Models·Zenn LLM

Voicebox に Jetson 8GB の Bonsai 27B を繋いだ話 — OpenAI互換APIをRustで全部書いた理由The author ran Bonsai 27B on a Jetson with 8 GB RAM and built a full…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約8GBメモリのJetson上でBonsai 27Bを動かし、VoiceboxからOpenAI互換APIで呼び出せるよう、RustでAPIサーバーをゼロから実装した経緯と技術的な選択理由を解説している。

AI SUMMARYThe author ran Bonsai 27B on a Jetson with 8 GB RAM and built a full OpenAI-compatible API server in Rust to connect it to Voicebox, explaining why Rust was chosen over existing solutions.

Voicebox に Jetson 8GB の Bonsai 27B を繋いだ話 — OpenAI互換APIをRustで全部書いた理由
コミュニティCommunityLocal Models·Simon Willison's Weblog

Thomas Ptacek の言葉を引用Quoting Thomas Ptacek

重要度 InfoInformational深掘り候補 · 技術記事 · Local LLM / Open ModelsDeep-dive candidate · technical post · Local LLM / Open Models

AI要約セキュリティ研究者 Thomas Ptacek によるローカル LLM に関する見解を Simon Willison が取り上げ、その実用性や限界について注目すべき視点を紹介している。

AI SUMMARYSimon Willison highlights a notable take from security researcher Thomas Ptacek on local LLMs, surfacing an expert perspective worth attention in the ongoing conversation about their practical value.

コミュニティCommunityLocal Models·Simon Willison's Weblog

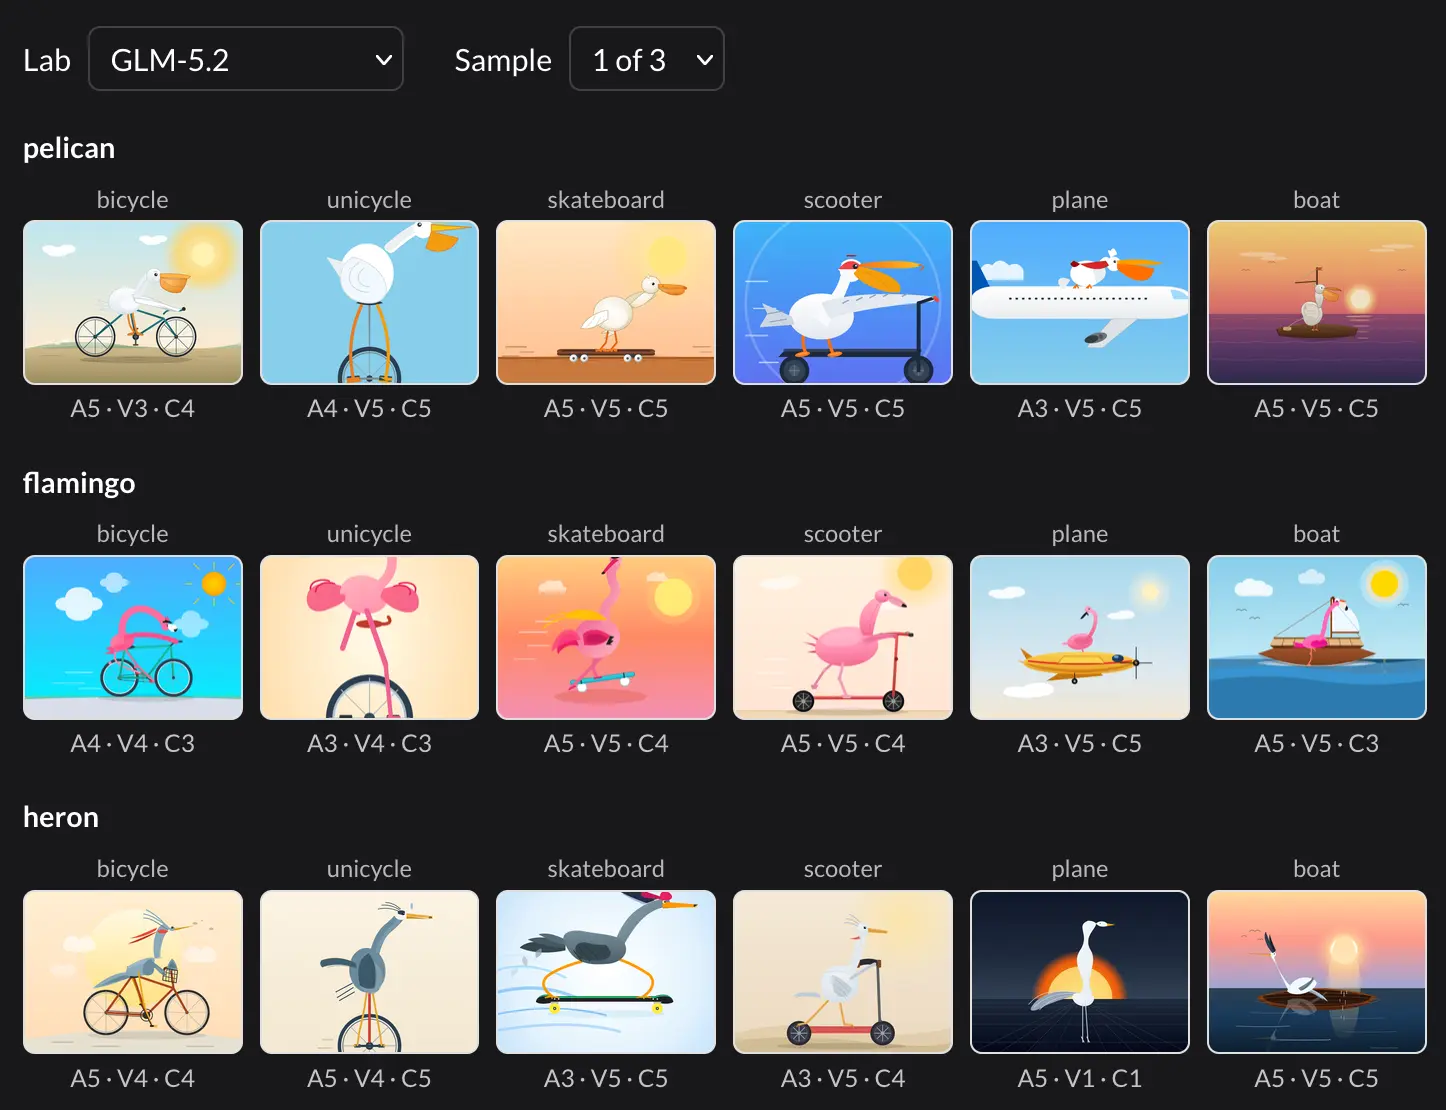
AIラボは「pelicanmaxxing」をしているのか?Are AI labs pelicanmaxxing?

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Simon Willison氏が、AIラボがベンチマーク向けに過剰最適化する「pelicanmaxxing」と呼ばれる現象を考察し、実用性より指標改善を優先するリスクを指摘した記事。

AI SUMMARYSimon Willison examines whether AI labs are "pelicanmaxxing" — over-optimizing for benchmarks and metrics at the expense of genuine usefulness, and what that means for the field.

Are AI labs pelicanmaxxing?
7/21(火)Tue, Jul 212 entries
コミュニティCommunityLocal Models·Simon Willison's Weblog

Nativ: Mac でAIモデルをローカル実行するアプリNativ: Run AI models locally on your Mac

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約NativはMac上でAIモデルをローカル動作させるアプリで、プライバシーを保ちながらオフラインでLLMを活用できる点が注目される。

AI SUMMARYNativ is a macOS app that lets users run AI models locally, enabling private and offline LLM usage without relying on cloud services.

コミュニティCommunityLocal Models·Qiita LLM

Claude Fable 5 を9Bモデルに蒸留? 100万トークンの超長文推理モデル「Qwythos-9B」を4GBのVRAMで動かすQwythos-9B is a purported Claude Fable 5 distillation that supports 1M-token…

重要度 MediumMedium priority技術記事 · Local LLM / Open Modelstechnical post · Local LLM / Open Models

AI要約Qwythos-9BはClaude Fable 5からの蒸留とされる9Bパラメータの推論モデルで、100万トークンのコンテキストを持ちながら4GB VRAMで動作する点が注目される。

AI SUMMARYQwythos-9B is a purported Claude Fable 5 distillation that supports 1M-token context while running on just 4 GB of VRAM, making long-context reasoning accessible on consumer hardware.

Claude Fable 5 を9Bモデルに蒸留? 100万トークンの超長文推理モデル「Qwythos-9B」を4GBのVRAMで動かす